# Butterbase Documentation — Full Content
> Complete documentation for Butterbase, concatenated for LLM consumption.
> Source: https://docs.butterbase.ai | Generated: 2026-09-30
> For the index of links, see /llms.txt
---
## Getting Started / Introduction
Backend built for AI-assisted development.
Butterbase is an AI-optimized Backend-as-a-Service platform for modern applications. It provides a comprehensive backend out of the box with PostgreSQL, JWT-based authentication, and S3-compatible storage. Every endpoint, from initial configuration to database operations to file uploads, is designed to be agent-friendly with consistent patterns and predictable responses.
Connect your AI assistant to Butterbase using our MCP server, and it can read documentation, set up your backend, and write complete applications, all from simple prompts. No backend knowledge required.
## Why Butterbase?
Backend development with AI agents has long been a half-solved problem. AI can generate frontend code efficiently but struggles with backend complexity — database setup, authentication flows, API design all require deep expertise. Rather than forcing developers to piece together multiple services or become DevOps experts, we believe we can do better as a community — hence, Butterbase.
## What you get
- **Apps** — Each project is an isolated backend with its own database, identifier, and API base URL. Creating an app gives you everything your client code needs to get started.
- **Multi-region** — Choose where your app's data and compute live, close to your users. Move between regions as your audience grows. One API URL works from anywhere.
- **Declarative schema** — You describe tables and columns in a JSON format; the platform diffs your desired state against the current database and applies only the necessary changes. You can preview changes before they run.
- **Automatic data API** — Once tables exist, full CRUD operations are available over HTTP with filtering, sorting, and pagination. No code generation or manual route setup required.
- **Sign-in for your users** — Email/password registration, login, email verification, password reset, and social sign-in (OAuth with any provider) can be configured per app.
- **Per-user data rules (RLS)** — You can restrict rows so each signed-in user only accesses their own data. One tool call to enable on any table.
- **File storage** — Upload and download files through presigned URLs. Files are organized per-app and per-user with configurable size limits and content-type restrictions.
- **Serverless functions** — Deploy TypeScript/JavaScript functions that run on demand (HTTP triggers) or on a schedule (cron). Functions can access your app's database, use environment variables, and return custom responses.
- **Frontend deployment** — Deploy static frontends (React, Next.js, plain HTML) to a live URL with a single tool call. Global delivery and HTTPS included.
- **AI model gateway** — Call large language models (Claude, GPT-4, Llama, and more) through an OpenAI-compatible API. Bring your own key or use the platform's shared key with usage tracking.
- **Native RAG** — Ingest documents (PDF, DOCX, TXT, and more) and query them with natural language in two API calls. The platform handles chunking, embedding with `text-embedding-3-small`, and vector storage via pgvector. No ML infrastructure required.
- **Realtime** — WebSocket-based real-time data change notifications with RLS-aware filtering, presence tracking, and custom event triggers.
- **Billing & usage tracking** — Free, Pro, and Enterprise plans with usage-based metering for AI credits, storage, function invocations, and bandwidth.
- **Monetize your app** — Optional Stripe Connect flows so your end users can subscribe to plans you define.
## Typical workflow
1. Create an app and note its `app_id` and API base URL.
2. Define your schema (tables, columns, types, constraints).
3. Preview with dry-run, then apply your schema.
4. Set row-level rules on tables that store user-owned data.
5. Configure how your end users sign in (email/password and/or OAuth providers).
6. Optionally configure CORS origins for your frontend domain.
7. Optionally deploy serverless functions for custom backend logic.
8. Optionally add AI capabilities using the model gateway.
9. Optionally ingest documents into a RAG collection for semantic search.
10. Deploy your frontend for a live URL, or call the data API from your own frontend.
11. Monitor usage through the billing dashboard.
## Next steps
Ready to start building? Check out our [framework examples](/guides/react) to see how to build complete applications with Butterbase and AI assistance.
- [Quickstart](/getting-started/quickstart) — Get your first app running in 5 minutes
- [MCP Setup](/getting-started/mcp-setup) — Connect your AI assistant
- [Dashboard](/getting-started/dashboard) — Explore the management UI
---
## Getting Started / Before You Start
Read this before you start. It takes 5 minutes and can save you from rebuilding your architecture later.
## What Butterbase is
Butterbase is a backend platform: managed PostgreSQL database, JWT authentication, S3-compatible storage, serverless functions, and frontend hosting — all agent-friendly and accessible via MCP or CLI.
## What Butterbase is NOT
### Not a full Node.js / Next.js hosting platform
You can run Next.js apps, but only in two flavors:
- **Static export** (`next export`) → deploy via [Frontend Deployment](/core-concepts/frontend-deployment) (static files only)
- **Server-side Next.js with SSR** → deploy via [Edge SSR Deployment](/core-concepts/edge-ssr-deployment), which compiles to Cloudflare Workers (not Node.js)
**You cannot** upload your Node.js next.config.js or use native Node APIs (`fs`, `child_process`, etc.) in a standard Next.js server deployment. If you need Node.js APIs, use Serverless Functions instead.
### Not stateful by default
Most apps use stateless [Functions](/core-concepts/functions/) or [Edge SSR](/core-concepts/edge-ssr-deployment/). For per-key stateful coordination (chat rooms, games, agents) use [Durable Objects](/core-concepts/durable-objects/).
### Not MySQL/MongoDB/etc.
**PostgreSQL only.** We use Neon for managed Postgres, but the API is standard PostgreSQL. No other databases.
## Architecture decision tree
Pick your stack based on what you're building:
- **Vite SPA or static HTML?** → [Frontend Deployment](/core-concepts/frontend-deployment)
- **Next.js with `output: 'export'`?** → [Frontend Deployment](/core-concepts/frontend-deployment) (static)
- **Next.js with server actions, RSCs, or route handlers?** → [Edge SSR Deployment](/core-concepts/edge-ssr-deployment) (with `@cloudflare/next-on-pages` build step)
- **Remix or other Workers-compatible framework?** → [Edge SSR Deployment](/core-concepts/edge-ssr-deployment)
- **Real-time / stateful per-room or per-user (chat, games, agents, leaderboards)?** → [Durable Objects](/core-concepts/durable-objects)
- **Backend logic, webhooks, API endpoints, cron jobs?** → [Serverless Functions](/core-concepts/functions) (Deno runtime)
- **Database queries?** → Direct PostgreSQL via auto-generated REST API or from functions/Edge SSR apps
- **File uploads/downloads?** → [File Storage](/core-concepts/storage) (S3-compatible)
- **Real-time updates?** → [Realtime](/core-concepts/realtime) (WebSocket)
- **AI model calls?** → [AI Integration](/core-concepts/ai-integration) (OpenAI-compatible API)
## Common gotchas
### "I want to use Prisma"
Only the HTTP adapter works: `@prisma/adapter-neon` over network connections.
```typescript
import { PrismaClient } from '@prisma/client';
import { PrismaNeon } from '@prisma/adapter-neon';
// ✅ Works — HTTP over network
const prisma = new PrismaClient({
adapter: new PrismaNeon(neon_connection_string),
});
// ❌ Doesn't work — binary driver
const prisma = new PrismaClient(); // fails without adapter
```
The native Prisma client (socket-based binary driver) does not work on Cloudflare Workers or in Deno serverless functions.
### "I want to deploy a Next.js app"
You have two choices:
1. **Static export** (`next build && next export` → `out/`) — Deploy via [Frontend Deployment](/core-concepts/frontend-deployment). No SSR.
2. **Full Next.js with SSR** — Must compile with `@cloudflare/next-on-pages` first, then deploy via [Edge SSR Deployment](/core-concepts/edge-ssr-deployment). This replaces your normal `npm run build` workflow.
There is no third option. The dashboard's frontend deployment is static-only.
**Don't want to install build tools locally?** Both `butterbase deploy` and `butterbase deploy:edge-ssr` accept `--from-source`. Butterbase will run `npm install` and your build command in a Cloudflare Container, no local toolchain required. See [Server-Side Build](/core-concepts/server-side-build/).
### "My function uses a Node-only npm package"
Serverless Functions run on Deno, not Node.js. Packages requiring Node APIs (`fs`, `path`, `child_process`) will fail.
Before using a package, check:
- Does it work in Deno? (Check its README or test locally)
- Does it work in Cloudflare Workers? (Many packages support both)
When in doubt, test locally in your edge/serverless environment before deploying.
## Where to go next
- [Quickstart](/getting-started/quickstart) — Build your first app in 5 minutes
- [Database & Schema](/core-concepts/database) — Define your data model
- [Serverless Functions](/core-concepts/functions) — Write backend logic
- [Frontend Deployment](/core-concepts/frontend-deployment) — Deploy static frontends
- [Edge SSR Deployment](/core-concepts/edge-ssr-deployment) — Deploy server-side Next.js apps
- [Architecture](/core-concepts/authentication) — Learn about auth, RLS, and realtime
---
## Getting Started / Quickstart
import { Steps, Tabs, TabItem } from '@astrojs/starlight/components';
This guide walks you through creating an app, defining a schema, inserting data, and setting up authentication. You can do all of this through the MCP tools (if using an AI assistant), the CLI, or the REST API.
1. **Create an app**
```
Use the init_app tool with name: "my-app"
```
```bash
butterbase apps create my-app
butterbase apps use
```
```bash
curl -X POST https://api.butterbase.ai/init \
-H "Authorization: Bearer bb_sk_..." \
-H "Content-Type: application/json" \
-d '{"name": "my-app"}'
```
You'll receive an `app_id` and API base URL. Save these — you'll need them for all subsequent operations.
To create the app in a specific region, pass `region: "us-west-2"` (MCP) or `"region": "us-west-2"` in the JSON body (REST). See [Regions](/core-concepts/regions/) for the available list.
2. **Define your schema**
Describe your tables in a declarative JSON format:
```json
{
"schema": {
"tables": {
"posts": {
"columns": {
"id": { "type": "uuid", "primary": true, "default": "gen_random_uuid()" },
"title": { "type": "text", "nullable": false },
"body": { "type": "text" },
"user_id": { "type": "uuid", "nullable": false },
"published": { "type": "boolean", "default": "false" },
"created_at": { "type": "timestamptz", "default": "now()" }
}
}
}
},
"name": "create posts table"
}
```
Preview the changes first with `dry_run: true`, then apply.
3. **Enable row-level security**
Restrict data so each user only sees their own posts:
```
Use create_user_isolation_policy with table_name: "posts", user_column: "user_id"
```
```bash
curl -X POST https://api.butterbase.ai/v1/{app_id}/rls \
-H "Authorization: Bearer bb_sk_..." \
-H "Content-Type: application/json" \
-d '{"table_name": "posts", "user_column": "user_id"}'
```
4. **Insert and query data**
```typescript
import { createClient } from '@butterbase/sdk';
const butterbase = createClient({
appId: 'app_abc123',
apiUrl: 'https://api.butterbase.ai',
});
// Insert a row
const { data } = await butterbase
.from('posts')
.insert({ title: 'Hello World', body: 'My first post' });
// Query rows
const { data: posts } = await butterbase
.from('posts')
.select('*')
.eq('published', true)
.order('created_at', { ascending: false });
```
```bash
# Insert
curl -X POST https://api.butterbase.ai/v1/{app_id}/posts \
-H "Authorization: Bearer {user_jwt}" \
-H "Content-Type: application/json" \
-d '{"title": "Hello World", "body": "My first post"}'
# Query
curl "https://api.butterbase.ai/v1/{app_id}/posts?published=eq.true&order=created_at.desc"
```
5. **Deploy your frontend**
Build your frontend, zip the output, and deploy:
```bash
npm run build
# Zip the dist/ folder (use archiver or Git Bash zip)
```
Then use the `create_frontend_deployment` and `start_frontend_deployment` MCP tools, or the REST API.
## Next steps
- [Database & Schema](/core-concepts/database) — Learn the full schema DSL
- [Authentication](/core-concepts/authentication) — Set up sign-in for your users
- [TypeScript SDK](/sdks-and-tools/typescript-sdk) — Use the SDK in your frontend
---
## Getting Started / Agents Quickstart
import { Steps, Tabs, TabItem } from '@astrojs/starlight/components';
This guide walks you through creating an agent that classifies an incoming request and answers using a serverless function you deploy yourself. By the end you'll have a real agent answering live requests with streamed events.
**You'll need**: a Butterbase app (see the [main quickstart](/getting-started/quickstart/) if you don't have one), and either the CLI installed (`npm i -g @butterbase/cli`) or the MCP server connected to your AI assistant.
1. **Deploy a function and expose it as an agent tool**
Save the following as `lookup_account.ts`:
```ts
export default async function handler(req: Request, ctx: { db: any }) {
const { email } = await req.json();
const { rows } = await ctx.db.query(
'SELECT id, plan, status FROM accounts WHERE email = $1 LIMIT 1',
[email],
);
return Response.json(rows[0] ?? { error: 'not_found' });
}
```
Deploy it with `agent_tool` enabled:
```bash
butterbase functions deploy ./lookup_account.ts \
--agent-tool \
--agent-tool-description "Look up a customer account by email. Returns id, plan, status." \
--agent-tool-mode read_only \
--agent-tool-exposed-to developer_only
```
```
Use deploy_function with:
name: "lookup_account"
code: "...source above..."
agent_tool: true
agent_tool_description: "Look up a customer account by email."
agent_tool_mode: "read_only"
agent_tool_exposed_to: "developer_only"
```
```http
POST /v1/{app_id}/functions
Authorization: Bearer {token}
{
"name": "lookup_account",
"code": "...source above...",
"agent_tool": true,
"agent_tool_description": "Look up a customer account by email.",
"agent_tool_mode": "read_only",
"agent_tool_exposed_to": "developer_only"
}
```
2. **Create an agent**
The agent's graph spec defines two LLM nodes: a triage step that classifies the message, and an answer step that calls the function you just deployed.
```json title="agent-spec.json"
{
"spec_version": "1",
"entry": "triage",
"nodes": {
"triage": {
"type": "llm",
"model": "anthropic/claude-3.5-haiku",
"system_prompt": "Classify the user's message as 'billing' or 'other'. Respond with just the category.",
"input_template": "{{ input.message }}",
"output_key": "category",
"tools": []
},
"answer": {
"type": "llm",
"model": "anthropic/claude-3.5-sonnet",
"system_prompt": "You are a {{ state.category }} agent. Use lookup_account to find the user before answering.",
"input_template": "{{ input.message }}",
"output_key": "reply",
"tools": [
{ "source": "function", "name": "lookup_account" }
]
},
"done": { "type": "end", "output_template": "{{ state.reply }}" }
},
"edges": [
{ "from": "triage", "to": "answer" },
{ "from": "answer", "to": "done" }
],
"tools": {
"builtin": [],
"mcp_servers": [],
"functions": ["lookup_account"]
},
"limits": {
"max_steps": 10,
"max_tool_calls": 5,
"max_parallel_tools": 2,
"timeout_seconds": 120,
"human_timeout_seconds": 86400
}
}
```
```bash
butterbase agents create \
--name billing-triage \
--display-name "Billing triage" \
--default-model anthropic/claude-3.5-haiku \
--spec ./agent-spec.json
```
```
Use manage_agents with:
action: "create"
name: "billing-triage"
display_name: "Billing triage"
default_model: "anthropic/claude-3.5-haiku"
graph_spec:
```
```http
POST /v1/{app_id}/agents
Authorization: Bearer {token}
{
"name": "billing-triage",
"display_name": "Billing triage",
"default_model": "anthropic/claude-3.5-haiku",
"graph_spec": { ... }
}
```
3. **Run it**
```bash
butterbase agents run billing-triage \
--input '{"message": "Why was I charged twice?"}' \
--stream
```
```http
POST /v1/{app_id}/agents/billing-triage/runs
Authorization: Bearer {token}
{ "input": { "message": "Why was I charged twice?" } }
```
Then connect to the SSE stream:
```http
GET /v1/{app_id}/agents/billing-triage/runs/{run_id}/events
Accept: text/event-stream
```
You'll see events stream by:
```
event: run_start
event: node_start {"node_id": "triage", "step": 1}
event: llm_token_usage {"input_tokens": 412, "output_tokens": 4}
event: node_end {"node_id": "triage", "step": 1}
event: node_start {"node_id": "answer", "step": 2}
event: tool_call_start {"tool_name": "lookup_account", "args": {...}}
event: tool_call_end {"tool_name": "lookup_account", "result": {...}}
event: llm_token_usage {"input_tokens": 891, "output_tokens": 142}
event: node_end {"node_id": "answer", "step": 2}
event: run_end {"output": "Hi! I found your account..."}
```
4. **Inspect runs in the dashboard**
Open **Agents → billing-triage → Runs** in the dashboard to see the full event timeline, tool inputs/outputs, and cumulative token + cost.
## Next steps
- Read the full [Agents core concepts page](/core-concepts/agents/) to learn how nodes, edges, and tools fit together.
- Browse the [Agents API reference](/api-reference/agents-api/) for every endpoint and event shape.
- See [examples/agents/](https://github.com/NetGPT-Inc/butterbase/tree/main/examples/agents) on GitHub for `approval-hitl`, `mcp-docs`, and `support-readonly` reference bundles.
---
## Getting Started / MCP Setup
Your AI assistant connects to Butterbase through MCP. That connection lets the assistant manage your entire backend — creating apps, evolving schemas, configuring authentication, managing storage, deploying functions, and more — using structured tools instead of manual work.
## What is MCP?
The **Model Context Protocol (MCP)** is a standard for connecting AI assistants to external tools and data sources. When you connect Butterbase via MCP, your assistant gains access to a broad set of tools and a quickstart prompt for managing your backend — creating apps, picking a region, evolving schemas, configuring auth, deploying functions, and more.
## Setting up the MCP connection
### Option 1: Claude Code Plugin (recommended)
Install Butterbase Skills for Claude Code. This auto-configures the MCP server and includes 6 guided skills:
```bash
# Add the marketplace
claude plugin marketplace add https://github.com/butterbase-ai/butterbase-skills
# Install the plugin
claude plugin install butterbase
```
Set your API key:
```bash
export BUTTERBASE_API_KEY=bb_sk_your_key_here
```
The plugin includes:
- **Auto-configured MCP server** — 43 tools and 1 prompt available immediately
- **6 skills** — `/butterbase-skills:build-app`, `/butterbase-skills:schema`, `/butterbase-skills:deploy`, `/butterbase-skills:debug-rls`, `/butterbase-skills:function`, `/butterbase-skills:contributing`
- **Always-on context** — environment variables, workflows, and patterns
### Option 2: CLI Setup
If you already have the Butterbase CLI installed:
```bash
butterbase plugin setup
```
This generates a `.mcp.json` in your project directory that configures the MCP connection.
### Option 3: Manual Configuration
Add this to your MCP configuration (`.mcp.json` or editor MCP settings):
```json
{
"mcpServers": {
"butterbase": {
"url": "https://api.butterbase.ai/mcp",
"headers": {
"Authorization": "Bearer ${BUTTERBASE_API_KEY}"
}
}
}
}
```
This works with Claude Code, Cursor, Windsurf, and any MCP-compatible editor.
### MCP over HTTP
The MCP endpoint is available at:
| Method | Path | Purpose |
|--------|------|---------|
| GET, POST, DELETE | /mcp | Streamable HTTP MCP session |
Include your API key as a Bearer token in the Authorization header.
## Available tools
### App Management
| Tool | What it does |
|------|--------------|
| **init_app** | Create a new backend app. You supply a name (and optionally a region); you receive the app id and API base URL. |
| **list_regions** | List the regions an app can be created or moved to. |
| **manage_app** (action: "list") | List all apps you have access to with their metadata. |
| **manage_app** (action: "delete") | Permanently delete an app and its database. This is irreversible. |
| **manage_app** (action: "get_config") | Read an app's current configuration (CORS origins, JWT settings, storage limits). |
| **manage_app** (action: "update_cors") | Set the list of allowed origins for browser requests to your app's API. |
| **manage_app** (action: "move") | Move an existing app to another region. Pass `dest_region`; returns a `migration_id`. |
| **manage_app** (action: "move_status") | Check the progress of a move in flight. Pass `migration_id`. |
| **manage_app** (action: "teardown_source_replica") | Decommission the retained source-region replica after a completed move. |
| **manage_auth_config** (action: "update_jwt") | Configure access token lifetime and refresh token lifetime. |
| **manage_auth_config** (action: "generate_service_key") | Generate a `bb_sk_` prefixed API key for programmatic access. |
### Schema & Migrations
| Tool | What it does |
|------|--------------|
| **get_schema** | Read the current database schema for an app. |
| **apply_schema** | Apply a declarative schema. Set `dry_run: true` to preview. |
| **dry_run_schema** | Preview SQL statements without executing. |
| **list_migrations** | View the history of all schema migrations. |
### Data Operations
| Tool | What it does |
|------|--------------|
| **select_rows** | Query table rows with filtering, sorting, pagination. |
| **insert_row** | Insert a row into a table. |
### Authentication & Security
| Tool | What it does |
|------|--------------|
| **configure_oauth_provider** | Register a social sign-in provider. |
| **get_oauth_config** | List all configured OAuth providers. |
| **update_oauth_provider** | Modify an existing OAuth provider. |
| **delete_oauth_provider** | Remove an OAuth provider. |
| **enable_rls** | Enable row-level security on a table. |
| **create_policy** | Create a custom RLS policy. |
| **create_user_isolation_policy** | Quick user isolation setup. |
| **get_rls_policies** | List active RLS policies. |
| **delete_rls_policy** | Remove RLS from a table. |
| **query_audit_logs** | Search authentication audit logs. |
### Storage
| Tool | What it does |
|------|--------------|
| **generate_upload_url** | Get a presigned upload URL. |
| **generate_download_url** | Get a presigned download URL. |
| **get_storage_objects** | List all files for an app. |
| **delete_storage_object** | Delete a file from storage. |
### Serverless Functions
| Tool | What it does |
|------|--------------|
| **deploy_function** | Deploy a TypeScript/JavaScript function. |
| **list_functions** | List all deployed functions. |
| **invoke_function** | Test-invoke a deployed function. |
| **delete_function** | Delete a deployed function. |
| **update_function_env** | Update environment variables. |
| **get_function_logs** | View invocation logs. |
### Frontend Deployment
| Tool | What it does |
|------|--------------|
| **create_frontend_deployment** | Create a deployment and get an upload URL. |
| **start_frontend_deployment** | Start a deployment after uploading. |
| **list_frontend_deployments** | View deployment history. |
| **set_frontend_env** | Configure environment variables for builds. |
### Realtime
| Tool | What it does |
|------|--------------|
| **configure_realtime** | Enable realtime on tables. |
| **get_realtime_config** | View current realtime configuration. |
### Feedback & Documentation
| Tool | What it does |
|------|--------------|
| **submit_suggestion** | Submit feedback or bug reports. |
| **butterbase_docs** | Read the documentation by topic. |
## Generating an API key
You can generate API keys through the [dashboard](https://dashboard.butterbase.ai) on the API Keys page, or using the `generate_service_key` MCP tool. Keys are prefixed with `bb_sk_` and provide full access to your apps and data.
---
## Getting Started / Dashboard
The Butterbase dashboard at [dashboard.butterbase.ai](https://dashboard.butterbase.ai) gives you a visual interface to manage all aspects of your backend.
## Platform pages
| Page | What it does |
|------|-------------|
| **Apps** | View, create, and manage all your backend apps |
| **API Keys** | Generate and manage `bb_sk_` API keys for programmatic access |
| **Billing** | View your plan, usage metrics, and upgrade options |
| **Settings** | Account settings and developer mode toggle |
| **Templates** | Browse public app templates and clone any of them into a new app you own |
On the Apps page, you'll also find a "Clone template" button for users who already know a source `app_id` — use it to clone without browsing the Templates page.
## App management
When you select an app, you get access to these sections:
| Section | What it does |
|---------|-------------|
| **Overview** | App ID, API base URL, and quick-start information |
| **Schema** | Visual schema editor — view and modify tables, columns, types, and constraints |
| **Data** | Data browser — view, insert, edit, and delete rows in your tables |
| **Users** | Manage end-user accounts, view profiles, and monitor sign-ups |
| **OAuth** | Configure social sign-in providers (Google, GitHub, Discord, etc.) |
| **RLS** | View and manage row-level security policies on your tables |
| **Functions** | Deploy, view, and manage serverless functions with logs and metrics |
| **Deployments** | View frontend deployment history and manage live deployments |
| **Realtime** | Configure real-time WebSocket notifications on tables |
| **AI** | Configure AI model gateway settings and view usage |
| **Storage** | Browse uploaded files, view metadata, and manage storage |
| **Monetization** | Set up Stripe Connect, manage subscription plans and products |
| **Audit** | View authentication event logs (logins, signups, password resets) |
| **App Settings** | CORS configuration, JWT token lifetimes, and app-level settings |
## Developer mode
The dashboard has a developer mode toggle in Settings. When enabled, you get access to the Apps page and full app management features. When disabled, you see a simplified view focused on billing and account settings.
## Connecting to the docs
You can access these docs at any time from the **Documentation** link in the dashboard sidebar, or directly at [docs.butterbase.ai](https://docs.butterbase.ai).
---
## Getting Started / Hackathon
When Butterbase runs a hackathon, you register with a code from the organizers, submit your project through the **`prep_and_submit_hackathon_entry`** MCP tool, and review your entry in the [dashboard](https://dashboard.butterbase.ai/hackathon).
## Before you submit
1. **Connect MCP** — Follow [MCP Setup](/getting-started/mcp-setup) so your assistant can call Butterbase tools with your API key.
2. **Get a submission code** — Organizers share a per-hackathon code (for example after you sign up). You need it on your **first** successful submission so your account is bound to that hackathon. The same code is also used during prep to identify which open hackathon you mean when more than one is running.
3. **Know your `app_id`** (recommended) — Use **`manage_app`** with `action: "list"` and copy the `id` of the app you are entering (for example `app_abc123`). See [Why include app_id](#why-include-app_id) below.
## Submitting with MCP
The tool **`prep_and_submit_hackathon_entry`** appears in your MCP tool list whenever some hackathon row has `starts_at ≤ now ≤ submission_deadline`. Calendar `ends_at` is separate from submissions closing at **`submission_deadline`**.
The flow is **two steps**: **prep** to resolve the hackathon and discover its fields, then **submit** with the confirmed values.
### Step 1 — `action: "prep"`
Pass your **`submission_code`**. The tool resolves which open hackathon you mean and returns:
- **`matched`** — `{ slug, name, submission_deadline, ends_at, field_schema }` describing the hackathon and its fields.
- **`open_hackathons`** — every hackathon currently accepting submissions, in case `matched` is `null` and you need to disambiguate.
- **`next_call`** — a fully-formed example **`submit`** invocation, including a placeholder for every field in `field_schema`. Use this as the literal shape for Step 2 — replace each placeholder in `arguments.data` with the user-confirmed value.
If `matched` is `null` and `open_hackathons` has multiple entries, ask the user which hackathon and re-run prep with the right `submission_code`.
### Step 2 — `action: "submit"`
Send:
- **`hackathon_slug`** — use **`matched.slug`** from the prep response so submit targets exactly the hackathon prep resolved.
- **`data`** — an object whose keys match each `field_schema` field's `key`. Easiest path: take `next_call.arguments.data` from prep and fill in each placeholder. A JSON-encoded string is also accepted and will be parsed.
- **`app_id`** — strongly recommended; see [Why include app_id](#why-include-app_id).
- **`submission_code`** — required only on the **first** submission so you can be bound as a participant. After that you are bound by user id and the code is no longer required.
### If `data` is missing
If you call `submit` without `data`, the tool **does not just error**. It re-resolves the hackathon and returns the field schema plus another **`next_call`** template so you have an exact shape to retry with — no extra round trip needed.
### Updates
Submissions **upsert**: calling submit again with new `data` updates your entry and bumps **`version`**.
## Why include `app_id`
Pass **`app_id`** (the Butterbase app you built) on every submission when you can.
**Automated leaderboard scoring** works like this:
- Up to **50** points for a valid **demo URL** hosted on **`*.butterbase.dev`**. The hackathon schema may mark one field with **`is_url`** for this check; otherwise the **`demo_url`** key in **`data`** is used.
- Up to **50** additional points for **Butterbase features** detected on the app tied to **`app_id`** (database, functions, deployed frontend, auth users, storage, OAuth, realtime, integrations, and more).
If **`app_id`** is omitted, only the demo URL is scored; the feature portion is **zero**, so your total is usually much lower than comparable entries that linked an app.
**Human judges** can also verify your real project faster when the submission is linked to a concrete app.
## View your submission
Open **[dashboard.butterbase.ai/hackathon](https://dashboard.butterbase.ai/hackathon)** while signed in. You will see deadlines, your submitted fields (read-only), and the current **version**. Use MCP again to update the entry.
## Related
- [MCP Setup](/getting-started/mcp-setup) — connect your assistant.
- [MCP Tools](/api-reference/mcp-tools) — full tool list, including hackathon tools when the window is open.
---
## Core Concepts / Database & Schema
Butterbase uses a declarative JSON format to define your database schema. You describe the desired state; the platform figures out what changes are needed and applies them safely.
Each app's database lives in the [region](/core-concepts/regions/) you picked when you created the app. You can move it to another region later if your audience shifts.
## Basic structure
```json
{
"schema": {
"tables": {
"table_name": {
"columns": {
"column_name": {
"type": "text",
"primary": true,
"nullable": false,
"unique": true,
"default": "gen_random_uuid()",
"references": { "table": "other_table", "column": "id" }
}
},
"indexes": {
"idx_name": {
"columns": ["col1", "col2"],
"unique": false
}
}
}
}
},
"dry_run": false,
"name": "descriptive migration name"
}
```
## Column properties
| Property | Type | Required | Description |
|----------|------|----------|-------------|
| `type` | string | Yes | The column data type |
| `primary` | boolean | No | Makes this column the primary key |
| `nullable` | boolean | No | Whether NULL values are allowed (default: true) |
| `unique` | boolean | No | Adds a unique constraint |
| `default` | string | No | Default value expression (e.g., `"now()"`, `"gen_random_uuid()"`) |
| `references` | string \| object | No | Foreign key. Either `"table.column"` shorthand or `{table, column, onDelete?, onUpdate?}`. |
## Supported column types
| Category | Types |
|----------|-------|
| **Text** | `text`, `varchar`, `varchar(N)`, `char`, `char(N)` |
| **Numbers** | `integer`, `bigint`, `smallint`, `real`, `float4`, `float8`, `decimal`, `numeric`, `numeric(P,S)` |
| **Boolean** | `boolean`, `bool` |
| **UUID** | `uuid` |
| **Date/Time** | `timestamp`, `timestamptz`, `date`, `time`, `timetz`, `interval` |
| **JSON** | `json`, `jsonb` |
| **Binary** | `bytea` |
| **Vectors** | `vector(N)` where N is the dimension (for AI embeddings) |
| **Arrays** | `text[]`, `integer[]`, etc. |
## Common patterns
### Basic table with auto-generated ID
```json
{
"tables": {
"posts": {
"columns": {
"id": { "type": "uuid", "primary": true, "default": "gen_random_uuid()" },
"title": { "type": "text", "nullable": false },
"body": { "type": "text" },
"published": { "type": "boolean", "default": "false" },
"created_at": { "type": "timestamptz", "default": "now()" },
"updated_at": { "type": "timestamptz", "default": "now()" }
}
}
}
}
```
### Table with foreign key and user ownership
```json
{
"tables": {
"comments": {
"columns": {
"id": { "type": "uuid", "primary": true, "default": "gen_random_uuid()" },
"post_id": { "type": "uuid", "nullable": false, "references": { "table": "posts", "column": "id", "onDelete": "CASCADE" } },
"user_id": { "type": "uuid", "nullable": false },
"body": { "type": "text", "nullable": false },
"created_at": { "type": "timestamptz", "default": "now()" }
},
"indexes": {
"idx_comments_post": { "columns": ["post_id"] },
"idx_comments_user": { "columns": ["user_id"] }
}
}
}
}
```
After creating this table, use `create_user_isolation_policy` with `table_name: "comments"` and `user_column: "user_id"` for per-user data isolation.
### Foreign keys with referential actions
The `references` field accepts two equivalent forms.
**String shorthand** — defaults `onDelete` and `onUpdate` to `NO ACTION`:
```json
"author_id": { "type": "uuid", "references": "users.id" }
```
**Object form** — explicit referential actions:
```json
"author_id": {
"type": "uuid",
"references": {
"table": "users",
"column": "id",
"onDelete": "CASCADE",
"onUpdate": "NO ACTION"
}
}
```
**Allowed action values** for both `onDelete` and `onUpdate`:
| Value | Effect when the referenced row is deleted/updated |
|-------|---------------------------------------------------|
| `NO ACTION` (default) | Block the operation if dependent rows exist (deferred) |
| `RESTRICT` | Block immediately, no deferral |
| `CASCADE` | Apply the same operation to dependent rows |
| `SET NULL` | Set the FK column to NULL (column must be nullable) |
| `SET DEFAULT` | Set the FK column to its declared default |
Common pattern — delete a user and cascade-delete their posts:
```json
{
"tables": {
"posts": {
"columns": {
"id": { "type": "uuid", "primary": true, "default": "gen_random_uuid()" },
"author_id": {
"type": "uuid",
"nullable": false,
"references": { "table": "users", "column": "id", "onDelete": "CASCADE" }
},
"title": { "type": "text", "nullable": false }
}
}
}
}
```
### Table with vector column (for AI embeddings)
```json
{
"tables": {
"documents": {
"columns": {
"id": { "type": "uuid", "primary": true, "default": "gen_random_uuid()" },
"content": { "type": "text" },
"embedding": { "type": "vector(1536)" },
"created_at": { "type": "timestamptz", "default": "now()" }
}
}
}
}
```
## Adding columns to existing tables
Include the existing table with both existing and new columns. The platform diffs and only applies the changes:
```json
{
"tables": {
"posts": {
"columns": {
"id": { "type": "uuid", "primary": true, "default": "gen_random_uuid()" },
"title": { "type": "text", "nullable": false },
"body": { "type": "text" },
"published": { "type": "boolean", "default": "false" },
"image_url": { "type": "text" },
"view_count": { "type": "integer", "default": "0" },
"created_at": { "type": "timestamptz", "default": "now()" },
"updated_at": { "type": "timestamptz", "default": "now()" }
}
}
}
}
```
This adds `image_url` and `view_count` without touching existing columns.
## Dropping columns
Explicitly list columns to remove in `_dropColumns`:
```json
{
"tables": {
"posts": {
"columns": {
"id": { "type": "uuid", "primary": true, "default": "gen_random_uuid()" },
"title": { "type": "text", "nullable": false },
"body": { "type": "text" },
"created_at": { "type": "timestamptz", "default": "now()" }
},
"_dropColumns": ["published", "image_url"]
}
}
}
```
## Dropping tables
Set `_drop: true` to remove an entire table:
```json
{
"tables": {
"old_table": {
"_drop": true
}
}
}
```
## Marking tables as seed data
Use `_seed: true` to mark a table as containing seed data — rows that should be included when your app is cloned as a template:
```json
{
"tables": {
"roles": {
"_seed": true,
"columns": {
"id": { "type": "uuid", "primary": true, "default": "gen_random_uuid()" },
"name": { "type": "text", "nullable": false, "unique": true },
"created_at": { "type": "timestamptz", "default": "now()" }
}
}
}
}
```
The marker persists across schema apply/introspect cycles. Use it on lookup tables, reference data, default roles, or example rows so clones of your app arrive with the data they need pre-populated.
When someone clones your app, the rows in every seed-marked table are copied into the new app's database. Tables without `_seed: true` are cloned with their schema only — no rows are copied.
## What a clone copies
When someone clones your app, the new app gets:
- Your database schema (tables, columns, indexes).
- Your access rules (row-level security policies).
- Your function code.
- Your repo files (latest snapshot at the time of clone).
- Your non-secret configuration (storage settings, allowed origins, OAuth provider and URLs, AI model defaults).
- Rows in tables you marked with `_seed: true`.
- Your most recently published frontend, with your app id rewritten to the clone's so it calls the clone's backend (best-effort — skipped if you never deployed one).
## What stays with you
The cloned app does **not** inherit:
- Your end-user accounts or sessions.
- OAuth client credentials.
- Function environment variables.
- Bring-your-own-key (BYOK) AI provider keys.
- Custom domains.
- Billing.
- Function invocation history.
- Audit logs.
The clone owner must configure these themselves after the clone completes — see [Configuring Your Clone](/templates/configure/).
## Clone regions
Clones can target any of the [supported regions](/core-concepts/regions/). Cross-region clones may take a little longer because repo files are copied across regions before the new app is ready.
## Dry run (preview changes)
Always preview before applying destructive changes:
```json
{
"schema": { "tables": { "..." : {} } },
"dry_run": true
}
```
The response includes the SQL statements that would run, without actually executing them. Review the output, then apply with `dry_run: false` (or omit it).
## Auto-generated Data API
Once tables exist, a full REST API is automatically available — no code generation needed. See [REST API](/sdks-and-tools/rest-api) for the complete reference.
## Safety
- **Destructive operations are blocked by default.** You must explicitly use `_drop` or `_dropColumns` to remove tables or columns.
- **Schema limit:** Maximum 50 tables per schema definition.
- **Idempotent:** Applying the same schema twice does nothing — only differences are applied.
## Database architecture
Each app gets its own isolated PostgreSQL database (`app_{id}`) on the data plane. Every app database is initialized with:
- `pgvector` extension for embeddings
- `uuid-ossp` extension for UUID generation
- `current_user_id()` function for RLS support
- Schema migration tracking
---
## Core Concepts / Regions
When you create an app on Butterbase, you choose a region. Your database, files, and serverless functions live in that region — close to the users you're serving. Your client code keeps using a single API URL; we handle the routing automatically.
## Available regions
| Region | Code |
|---|---|
| US East | `us-east-1` |
| US West | `us-west-2` |
More regions are coming soon. If you'd like one in a specific part of the world, [let us know](mailto:hello@butterbase.ai).
### Fetching the live list
The supported region list is always available from the API. Use this if you're building a UI that lets your users choose a region, or if you want to validate a region slug before calling `init_app` or `manage_app` (action: `"move"`).
**MCP**
```
list_regions()
```
**REST**
```bash
curl https://api.butterbase.ai/v1/regions
# → { "regions": ["us-east-1", "us-west-2"] }
```
This endpoint is public (no API key required).
## Picking a region when you create an app
Region is optional. If you don't specify one, your app is created in the default region.
**MCP**
```
init_app({ name: "my-app", region: "us-west-2" })
```
**CLI**
```bash
butterbase apps create my-app --region us-west-2
```
**REST**
```bash
curl -X POST https://api.butterbase.ai/init \
-H "Authorization: Bearer $BUTTERBASE_API_KEY" \
-H "Content-Type: application/json" \
-d '{"name": "my-app", "region": "us-west-2"}'
```
## What lives in a region
Each app has a home region. The following stay there:
- Your database
- Your serverless functions
- Your file storage
- Your end users' accounts and sessions
The following are global and unaffected by region choice:
- The API URL — `https://api.butterbase.ai` works from anywhere
- Frontend deployments — served from a global edge network
- Your Butterbase account, billing, and the dashboard
## One URL, anywhere
Your frontend and SDK code always point at `https://api.butterbase.ai`. You don't pin to a regional URL, and you don't change anything when you move an app between regions. Requests are routed to the right region for you.
## Moving an app to another region
If your audience shifts — or you want to be closer to a different part of the world — you can move an app to another region.
**MCP**
```
manage_app({ action: "move", app_id: "app_abc123", dest_region: "us-east-1" })
```
**CLI**
```bash
butterbase apps move app_abc123 --to us-east-1
```
While the move is in progress, your app stays available for reads. Writes pause briefly during the cutover and resume automatically once the move completes. The whole process typically takes a few minutes, depending on how much data your app has.
Check progress at any time:
```
manage_app({ action: "move_status", app_id: "app_abc123", migration_id: "" })
```
You can't move an app while another move is already in progress for it.
## Choosing a region
A few things to consider:
- **Where your users are.** Pick the region closest to most of them. Round-trip latency between users and the database is the single biggest factor in how fast your app feels.
- **Data residency.** If you need to keep data in a specific jurisdiction, pick a region in that jurisdiction. Reach out if you need a region we don't list yet.
- **You can change your mind.** Apps aren't locked to their initial region. If you outgrow your first choice, move the app.
If you're not sure, leave the region unset and Butterbase picks a sensible default. You can always move the app later.
---
## Core Concepts / Authentication
Butterbase provides a complete authentication service for your app's end users. Each app has independent user accounts and tokens, scoped by `app_id`. End-user data lives in the same [region](/core-concepts/regions/) as the app it belongs to.
## Access modes
Each app has an `access_mode` that controls whether anonymous (unauthenticated) requests can reach the data API and realtime WebSocket. RLS policies still apply on top of this.
| Mode | Behavior |
|------|----------|
| `public` (default) | Anonymous requests allowed. RLS policies, if configured, still apply. |
| `authenticated` | Anonymous data and realtime requests are rejected with HTTP 401. Only end-user JWTs and API keys pass. |
`access_mode` does not affect function invocations or storage — those have their own auth rules.
### Toggle access mode
```json
PATCH /v1/{app_id}/config/access-mode
Authorization: Bearer {token}
{ "access_mode": "authenticated" }
```
Response:
```json
{
"message": "Access mode updated to \"authenticated\"",
"app_id": "app_abc123",
"access_mode": "authenticated"
}
```
### Lock down in one call
`POST /v1/{app_id}/secure` is a composite shortcut: it sets `access_mode = "authenticated"` and, for every table you list, enables RLS with a user-isolation policy and an auto-populate trigger.
```json
POST /v1/{app_id}/secure
Authorization: Bearer {token}
{
"tables": [
{ "table_name": "posts", "user_column": "author_id" },
{ "table_name": "comments", "user_column": "user_id" }
]
}
```
Pass `public_read_column` (a boolean column name) to additionally allow any user to read rows where it is `true`:
```json
{
"tables": [
{ "table_name": "posts", "user_column": "author_id", "public_read_column": "is_published" }
]
}
```
Omit `tables` entirely to only flip `access_mode` without RLS changes.
Response includes `tables_secured` and a `table_errors` array — if a table is missing or a column doesn't exist, the call still succeeds for the other tables.
To revert: PATCH the access mode back to `"public"`.
## Signup
| Method | Path | Rate Limit |
|--------|------|------------|
| POST | /auth/\{app_id}/signup | 5 requests per 15 minutes |
```json
{
"email": "user@example.com",
"password": "MyP@ssw0rd!",
"display_name": "Jane Doe"
}
```
**Password requirements:** At least 8 characters, must include uppercase, lowercase, a number, and a special character.
A verification email is sent automatically with a 6-digit code.
## Login
| Method | Path | Rate Limit |
|--------|------|------------|
| POST | /auth/\{app_id}/login | 10 requests per 15 minutes |
```json
{
"email": "user@example.com",
"password": "MyP@ssw0rd!"
}
```
**Response:**
```json
{
"access_token": "eyJhbGciOi...",
"refresh_token": "...",
"expires_in": 3600,
"token_type": "Bearer",
"user": {
"id": "uuid",
"email": "user@example.com",
"email_verified": true,
"display_name": "Jane Doe",
"avatar_url": null
}
}
```
The **access token** is what your frontend sends with API requests. The **refresh token** is used to get a new access token when the current one expires.
## Magic link sign-in
Passwordless sign-in: the user enters an email, receives a 6-digit code, and is signed in on verify. New users are auto-created (no separate signup step).
**Step 1: Send the code**
| Method | Path | Rate Limit |
|--------|------|------------|
| POST | /auth/\{app_id}/magic-link | 5 requests per 15 minutes |
```json
{
"email": "user@example.com"
}
```
The response is a generic message regardless of whether the email exists (prevents user enumeration). The code expires after **15 minutes**.
**Step 2: Verify the code**
| Method | Path | Rate Limit |
|--------|------|------------|
| POST | /auth/\{app_id}/magic-link/verify | 10 requests per 15 minutes |
```json
{
"email": "user@example.com",
"code": "123456"
}
```
Response is the same shape as `/login` — `access_token`, `refresh_token`, `expires_in`, `token_type`, and `user`. The user's email is marked verified automatically. Codes are single-use.
**Error responses (HTTP 400):**
| `error` | Cause |
|---------|-------|
| `Invalid sign-in code` | Code does not match |
| `Sign-in code already used` | Code was already exchanged |
| `Sign-in code expired` | 15-minute window passed |
**SDK:**
```ts
const { data, error } = await client.auth.sendMagicLink('user@example.com');
// later, after the user enters the code:
const { data, error } = await client.auth.verifyMagicLink('user@example.com', '123456');
```
`verifyMagicLink` persists the session automatically (same as `signIn`).
### Behavior notes
- **Frictionless signup:** if no user exists for the email, one is created automatically when the code is sent. The first verification logs them in.
- **`isNewUser` detection:** users who verified within 2 minutes of being created are flagged as new in audit logs and in the post-auth hook payload.
- **Post-auth hook:** verifying a code fires the configured hook with `event: "magic_link_login"` and `provider: "magic_link"` (see [Post-auth hooks](#post-auth-hooks)).
- **Audit events:** `magic_link_requested` (on send) and `magic_link_login` (on verify).
## Token refresh
| Method | Path | Rate Limit |
|--------|------|------------|
| POST | /auth/\{app_id}/refresh | 20 requests per 15 minutes |
Exchange a refresh token for a new access token. The old refresh token is invalidated (token rotation).
```json
{
"refresh_token": "your-refresh-token"
}
```
## Logout
| Method | Path | Auth Required |
|--------|------|---------------|
| POST | /auth/\{app_id}/logout | Yes (Bearer token) |
Revokes all refresh tokens. The user must log in again.
## Email verification
| Method | Path | Rate Limit |
|--------|------|------------|
| POST | /auth/\{app_id}/verify-email | 10 requests per 15 minutes |
```json
{
"email": "user@example.com",
"code": "123456"
}
```
The code expires after **24 hours**.
## Password reset
**Step 1: Request a reset code**
| Method | Path | Rate Limit |
|--------|------|------------|
| POST | /auth/\{app_id}/forgot-password | 3 requests per 15 minutes |
Always returns success regardless of whether the email exists (prevents user enumeration).
**Step 2: Reset the password**
| Method | Path | Rate Limit |
|--------|------|------------|
| POST | /auth/\{app_id}/reset-password | 5 requests per 15 minutes |
```json
{
"email": "user@example.com",
"code": "123456",
"new_password": "NewP@ssw0rd!"
}
```
The reset code expires after **1 hour**. All existing sessions are invalidated.
## Social sign-in (OAuth)
Configure a provider using the `configure_oauth_provider` MCP tool or the [OAuth configuration API](/api-reference/auth-api).
### Built-in providers
These only need `client_id`, `client_secret`, and `redirect_uris` — URLs and default scopes are auto-filled:
| Provider | Default Scopes |
|----------|---------------|
| **google** | openid, email, profile |
| **github** | user:email |
| **discord** | identify, email |
| **facebook** | email, public_profile |
| **linkedin** | openid, profile, email |
| **microsoft** | openid, email, profile, User.Read |
| **apple** | name, email (requires `provider_metadata`) |
| **x** | tweet.read, users.read (no email; synthetic email used) |
Custom providers require `authorization_url`, `token_url`, and `userinfo_url`.
### OAuth flow
1. Direct the user's browser to `/auth/{app_id}/oauth/{provider}?redirect_to=https://yourapp.com/callback`
2. The user signs in with the provider
3. The provider redirects to the callback URL
4. Tokens are returned as query parameters: `?access_token=...&refresh_token=...&expires_in=900`
### Provider-specific notes
- **Google, LinkedIn, Apple:** User info extracted from ID token via JWKS.
- **GitHub:** If email is not public, it's fetched from /user/emails automatically.
- **Apple:** Uses POST callback (form_post). Requires `provider_metadata` with teamId, keyId, and privateKey. Only provides name on first authorization.
- **X (Twitter):** Uses PKCE. No email provided — a synthetic email is generated.
## User profile
| Method | Path | Auth Required |
|--------|------|---------------|
| GET | /auth/\{app_id}/me | Yes |
Returns the authenticated user's profile.
## Token verification (JWKS)
| Method | Path | Cache |
|--------|------|-------|
| GET | /auth/\{app_id}/.well-known/jwks.json | 5 minutes |
Returns public keys for verifying access tokens in your own backend.
## Using tokens with the Data API
Include the access token when calling the data API:
```
GET /v1/{app_id}/posts
Authorization: Bearer {access_token}
```
With RLS enabled, the user only sees their own rows automatically.
## Post-auth hooks
Run custom logic after any successful authentication event (OAuth login, email login, email signup). The hook is a regular Butterbase function that is invoked fire-and-forget — it never delays token delivery to the user.
### Configuring
Use the `configure_auth_hook` MCP tool or the API:
```json
PATCH /v1/{app_id}/config/auth-hooks
Authorization: Bearer {token}
{
"post_auth_function": "on-auth"
}
```
Set `post_auth_function` to `null` to remove the hook. The function must be deployed before it can be configured as a hook.
### Hook payload
The hook function receives a POST request with this JSON body:
```json
{
"event": "oauth_login",
"user": {
"id": "uuid",
"email": "user@example.com",
"provider": "google",
"display_name": "Jane Doe",
"avatar_url": "https://..."
},
"isNewUser": true,
"provider": "google"
}
```
| Field | Values |
|-------|--------|
| `event` | `"oauth_login"`, `"signup"`, `"login"` |
| `isNewUser` | `true` for first-time users, `false` for returning users |
| `provider` | `"google"`, `"github"`, `"email"`, etc. |
### Example hook function
```typescript
export default async function handler(req: Request, ctx: any): Promise {
const { event, user, isNewUser } = await req.json();
if (isNewUser) {
// Send welcome email
ctx.waitUntil(
fetch("https://api.email.com/send", {
method: "POST",
body: JSON.stringify({ to: user.email, template: "welcome" }),
})
);
// Sync profile to your own table
await ctx.db.query(
"INSERT INTO profiles (user_id, display_name) VALUES ($1, $2)",
[user.id, user.display_name]
);
}
return new Response("ok");
}
```
The hook runs as `butterbase_service` (RLS bypassed). `ctx.user` is null — use the payload body to identify the user.
## Token lifetimes
Configurable per app using `update_jwt_config`:
- **Access token:** Default `1h` (options: `15m`, `30m`, `1h`, `2h`, `1d`)
- **Refresh token:** Default 7 days (configurable in days)
The 1-hour default is chosen so that cookie-based sessions in SSR apps don't fail silently when the JWT expires inside the cookie's lifetime. If you want stricter rotation, lower it with `update_jwt_config({ access_token_ttl: '15m' })` and make sure your client refreshes proactively before the cookie outlives the token.
---
## Core Concepts / Row-Level Security
Row-Level Security (RLS) lets you control which rows each user can access. It's powered by PostgreSQL's built-in RLS mechanism and enforced automatically based on how requests are authenticated.
## Built-in roles
Butterbase has three built-in roles that are **automatically determined** by the Authorization header. You never create or configure these roles:
| Request type | Authorization header | Role assigned |
|---|---|---|
| No auth header | (none) | butterbase_anon |
| End-user JWT | `Bearer {end_user_jwt}` | butterbase_user |
| Platform API key | `Bearer {platform_api_key}` | butterbase_service |
**butterbase_anon** — Access to public data only (based on your policies). Use for product catalogs, public profiles.
**butterbase_user** — Access to user-specific data. `current_user_id()` returns the authenticated user's ID. Use for dashboards, personal data.
**butterbase_service** — Full access to all data (bypasses RLS). A service bypass policy is auto-created on every RLS-enabled table.
## Three tools for RLS
### 1. enable_rls — Foundation
Enable RLS on a table. The service bypass policy is auto-created.
```
enable_rls({ app_id: "app_abc123", table_name: "posts" })
```
### 2. create_user_isolation_policy — Simple
One-call setup for the common case: users see only their own data.
```
create_user_isolation_policy({
app_id: "app_abc123",
table_name: "posts",
user_column: "user_id"
})
```
This automatically:
- Enables RLS
- Creates a user isolation policy (scoped to butterbase_user)
- Adds a trigger to auto-populate the user column on INSERT
- Creates a service bypass policy
### 3. create_policy — Power user
Full control over USING and WITH CHECK expressions:
```
create_policy({
app_id: "app_abc123",
table_name: "products",
policy_name: "public_read_products",
command: "SELECT",
role: "anon",
using_expression: "active = true AND published = true"
})
```
**Expression rules by command:**
| Command | USING | WITH CHECK |
|---------|-------|------------|
| SELECT | Yes | No |
| INSERT | No | Yes |
| UPDATE | Both | Both |
| DELETE | Yes | No |
| ALL | Both | Both |
## Policy examples
### Public read access (anonymous users)
```
create_policy({
policy_name: "public_read_products",
command: "SELECT",
role: "anon",
using_expression: "active = true AND published = true"
})
```
### User-specific access (authenticated users)
Quick way:
```
create_user_isolation_policy({
table_name: "orders",
user_column: "user_id"
})
```
Custom way:
```
create_policy({
policy_name: "users_own_orders",
command: "ALL",
role: "user",
using_expression: "user_id = current_user_id()"
})
```
### INSERT policy (user can only insert their own rows)
```
create_policy({
policy_name: "users_insert_own",
command: "INSERT",
role: "user",
with_check_expression: "user_id = current_user_id()::uuid"
})
```
### Mixed access (public read, user write)
1. Enable RLS: `enable_rls({ table_name: "products" })`
2. Public read: `create_policy({ command: "SELECT", role: "anon", using_expression: "active = true" })`
3. Authenticated write: `create_policy({ command: "INSERT", role: "user", with_check_expression: "user_id = current_user_id()" })`
## Role scoping
Always use the `role` parameter to prevent cross-role policy leaks:
- `role: "anon"` — Policy applies only to unauthenticated requests
- `role: "user"` — Policy applies only to authenticated end-users
Without role scoping, a policy applies to ALL roles, which can expose data unintentionally.
## Helper functions
- **current_user_id()** — Returns the authenticated user's ID as TEXT. Cast to UUID if needed: `current_user_id()::uuid`. Returns NULL for anonymous users.
## Auto-populate trigger
Only `create_user_isolation_policy` and `create_policy` with the `user_column` parameter create a BEFORE INSERT trigger that auto-fills the user column. Without the trigger, clients must include the user column in POST bodies.
## Common pitfall: Cross-table subqueries
When **any** policy expression (USING or WITH CHECK, permissive or restrictive) contains a subquery like `EXISTS (SELECT 1 FROM other_table WHERE …)` or `column IN (SELECT … FROM other_table)`, that subquery reads `other_table` **through `other_table`'s own RLS**, under the same calling role. If the subquery can't see the row it's looking for, the outer expression evaluates false and the operation fails with `AUTH_RLS_POLICY_VIOLATION` on writes (or returns empty on reads) — even for expressions that look trivially true.
There are three ways this bites you:
### 1. Referenced table has RLS enabled but no permissive `user` policy
Once a table has RLS enabled, the `butterbase_user` role sees zero rows unless a policy explicitly permits it. A subquery like `EXISTS (SELECT 1 FROM institutions WHERE id = '')` then returns false even though the row obviously exists.
Fix — expose the rows the subquery needs to see:
```
create_policy({
table_name: "institutions",
policy_name: "institutions_user_read",
command: "SELECT",
role: "user",
using_expression: "true" // or a narrower predicate
})
```
### 2. Referenced table has user_isolation — cross-user reads blocked
User B tries to comment on User A's public post. The policy on `comments` checks `EXISTS (SELECT 1 FROM posts WHERE id = post_id AND is_public = true)`. But `posts` has user_isolation, so User B can only see their own posts and the insert is blocked.
Fix — use `create_user_isolation_policy` with `public_read_column: "is_public"` on the referenced table, or add a permissive SELECT policy scoped to the public rows.
### 3. Subquery joins on a column different from the isolation column
Your `users` table is isolated by `id = current_user_id()::uuid`, but the session's `sub` is actually a separate `auth_user_id` value (common with OAuth callbacks that generate their own session id). A policy on `checkpoints` that reads `EXISTS (SELECT 1 FROM users WHERE u.id = checkpoints.student_id AND u.auth_user_id = current_user_id()::uuid)` fails: the subquery is filtered to just the row where `id = current_user_id()`, and that row's `auth_user_id` never matches, so nothing comes back.
Fix — align the referenced table's user_isolation column with the column your session id actually maps to. If your session `sub` is the OAuth `auth_user_id`, run:
```
create_user_isolation_policy({
table_name: "users",
user_column: "auth_user_id" // not "id"
})
```
### Quick diagnosis
If a policy fires `AUTH_RLS_POLICY_VIOLATION` on an INSERT that looks like it should pass, run the subquery portion by hand as the same user (`select_rows` with `as_role: "user", as_user: `) against the referenced table. If it returns no rows, that's your policy failing — not a WITH CHECK bug.
## REST API
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/rls/enable | Enable RLS on a table |
| POST | /v1/\{app_id}/rls/policies | Create a custom RLS policy |
| POST | /v1/\{app_id}/rls | Quick user isolation setup |
| GET | /v1/\{app_id}/rls | List all active policies |
| DELETE | /v1/\{app_id}/rls/\{table} | Remove RLS from a table |
---
## Core Concepts / File Storage
Butterbase provides file storage with presigned URLs. Files are organized per-app and per-user. Your frontend uploads and downloads files directly — file data never flows through your backend code.
Storage is co-located with your app's [region](/core-concepts/regions/), so uploads and downloads stay close to your users.
## How it works
1. **Request an upload URL** — Your app asks Butterbase for a presigned upload URL, providing the filename, content type, and size.
2. **Upload directly** — Your frontend uses the presigned URL to upload the file directly to storage.
3. **Reference the file** — Store the returned `objectId` in your database (e.g., as an `image_url` column).
4. **Download when needed** — Request a presigned download URL using the object ID.
## Object ID, object key, and URLs
| Value | What it is | What to do with it |
|--------|------------|---------------------|
| **`objectId`** | A stable UUID for this file | **Persist this** in your database. Use it for downloads and deletes. |
| **`objectKey`** | The path inside the bucket | **Not a URL.** Metadata only; do not store for display. |
| **`uploadUrl` / `downloadUrl`** | Temporary presigned HTTPS URLs | Use only for **immediate** operations. They **expire**. |
:::caution
Butterbase does not provide permanent public URLs for private files. Always mint a fresh presigned download URL when you need to show or fetch a file.
:::
## Common mistakes
- **Saving `objectKey` as a URL** — It's a path, not a URL. The UI will show broken images.
- **Using `objectKey` as `img src`** — Use `objectId` with the download endpoint to get a `downloadUrl`.
- **Storing only a presigned URL** — Presigned URLs expire. Store `objectId` as the source of truth.
## Uploading a file
**Step 1:** Request the upload URL.
```json
POST /storage/{app_id}/upload
Authorization: Bearer {token}
{
"filename": "profile.jpg",
"contentType": "image/jpeg",
"sizeBytes": 102400,
"public": false
}
```
Set `public: true` to mark the file as downloadable by any authenticated user. See [Public files](#public-files).
**Response:**
```json
{
"uploadUrl": "https://storage.example.com/...",
"objectKey": "app_id/user_id/uuid_profile.jpg",
"objectId": "uuid",
"expiresIn": 300
}
```
**Step 2:** Upload the file using the presigned URL.
```javascript
await fetch(uploadUrl, {
method: 'PUT',
headers: { 'Content-Type': 'image/jpeg' },
body: fileBlob
});
```
**Step 3:** Save the `objectId` in your database.
## Downloading a file
```json
GET /storage/{app_id}/download/{object_id}
Authorization: Bearer {token}
```
**Response:**
```json
{
"downloadUrl": "https://storage.example.com/...",
"filename": "profile.jpg",
"expiresIn": 3600
}
```
## Showing images in the UI
After loading rows that reference stored files by `objectId`:
1. For each file, call the download API or SDK `getDownloadUrl(objectId)`.
2. Use the returned `downloadUrl` as `![]() ` or download link.
3. For lists, resolve download URLs **in parallel** (`Promise.all`) for speed.
## Listing files
```
GET /storage/{app_id}/objects
Authorization: Bearer {token}
```
Returns an array of objects with `id`, `filename`, `content_type`, `size_bytes`, and `created_at`.
## Storage limits
| Limit | Default |
|-------|---------|
| Max file size | 10 MB per file |
| Total storage | 1 GB per app |
| Allowed content types | All types (configurable) |
## Access control
- **Service key:** Full access to all files. Uploads have no user association.
- **End-users:** Can only see and manage their own files. Uploads are automatically associated with the authenticated user.
## Public files
By default every uploaded file is private — only its uploader (or callers with a service key) can mint a download URL. There are two ways to make files publicly downloadable.
### Per-object: `public: true` at upload time
Set `public: true` in the upload request to mark a single file as publicly downloadable:
```json
{
"filename": "post-image.jpg",
"contentType": "image/jpeg",
"sizeBytes": 204800,
"public": true
}
```
Any authenticated end-user can then call `GET /storage/{app_id}/download/{object_id}` regardless of who uploaded it.
### App-wide: `publicReadEnabled`
Flip the app-level switch to make **all** files in the app readable by any authenticated user:
```json
PATCH /v1/{app_id}/config/storage
Authorization: Bearer {token}
{ "publicReadEnabled": true }
```
When enabled:
- Any authenticated user can download any file in the app.
- Uploads and deletes remain user-scoped — users can still only manage their own files.
- The per-object `public` flag becomes redundant.
### Authorization summary
A download URL is issued if **any** of the following is true:
1. The caller authenticated with a service key (`bb_sk_...`).
2. The app has `publicReadEnabled: true`.
3. The object has `public: true`.
4. The authenticated user owns the object.
## URL expiration
- Upload URLs expire after **5 minutes**
- Download URLs expire after **1 hour**
## SDK usage
```typescript
const { data } = await butterbase.storage.upload(file);
const { data: url } = await butterbase.storage.getDownloadUrl(objectId);
const { data: objects } = await butterbase.storage.list();
await butterbase.storage.delete(objectId);
// Mark a file as publicly downloadable
await butterbase.storage.upload(file, 'avatar.png', { public: true });
```
---
## Core Concepts / Serverless Functions
Deploy custom backend logic as serverless functions. Functions are written in TypeScript or JavaScript and run in an isolated Deno environment with database access, environment variables, and network capabilities.
Functions run in your app's [region](/core-concepts/regions/), so database calls stay fast.
## Deploying a function
```json
POST /v1/{app_id}/functions
Authorization: Bearer {token}
{
"name": "hello-world",
"code": "export default async function handler(req) {\n return new Response(JSON.stringify({ message: 'Hello!' }), {\n headers: { 'Content-Type': 'application/json' }\n });\n}",
"description": "A simple greeting function",
"trigger": {
"type": "http",
"config": {}
}
}
```
**Required fields:**
- `name` — Unique name (1-100 characters)
- `code` — Function source code with a default export handler
**Optional fields:**
- `description` — What the function does
- `envVars` — Key-value pairs for environment variables (encrypted at rest). On redeploy they merge into the existing env (incoming keys win); omit `envVars` to leave it untouched.
- `envVarsReplace` — Set `true` to replace the function's entire env with `envVars` instead of merging (default: `false`).
- `timeoutMs` — Max execution time (default: 30000, max: 300000)
- `memoryLimitMb` — Memory limit (default: 128, range: 64-1024)
- `triggers` — Array of one or more triggers describing how the function is invoked (`trigger` singular is also accepted and normalized to a 1-element array).
- `agent_tool` — Set `true` to expose this function to agents in this app as a callable tool. See [Agents](/core-concepts/agents/).
## Trigger types
A function can have **multiple triggers** — for example an HTTP endpoint plus a daily cron — by listing them in the `triggers` array. At most one trigger of each type per function.
| Type | Description | Config |
|------|-------------|--------|
| `http` | Called via HTTP request | `{ "method"?, "path"?, "auth"?: "required" \| "optional" \| "none" }` |
| `cron` | Runs on a schedule | `{ "schedule": "*/5 * * * *", "timezone"?: "UTC" }` |
| `s3_upload` | Fires when an object lands in a bucket | `{ "bucket": "name", "prefix"?: "uploads/", "contentTypes"?: ["image/*"] }` |
| `webhook` | Generates a signed webhook URL the platform routes to your handler | `{ "secret_required"?: true, "allowed_sources"?: "github,stripe" }` |
| `websocket` | Invoked on incoming realtime WebSocket frames | `{}` |
```json
"triggers": [
{ "type": "http", "config": { "auth": "required" } },
{ "type": "cron", "config": { "schedule": "0 9 * * *" } }
]
```
## Functions as agent tools
Set `agent_tool: true` on a function to expose it as a tool any [agent](/core-concepts/agents/) in this app can call. The agent runtime reads `agent_tool_description` to decide when to call the tool, and respects `agent_tool_mode` (`read_only` runs without approval; `read_write` pauses the run for a human to approve).
```json
{
"name": "lookup_account",
"code": "...",
"agent_tool": true,
"agent_tool_description": "Look up a customer by email.",
"agent_tool_mode": "read_only",
"agent_tool_exposed_to": "developer_only"
}
```
Agents must still list the function name in their graph spec's `tools.functions` array. The dashboard agent editor warns you when a referenced function does not exist or does not have `agent_tool: true`.
## Writing functions
Functions receive a Request and must return a Response:
```typescript
export default async function handler(req: Request, ctx: any): Promise {
const body = await req.json();
return new Response(JSON.stringify({ result: 'ok' }), {
status: 200,
headers: { 'Content-Type': 'application/json' }
});
}
```
**Available inside a function:**
- Standard Web APIs (fetch, Request, Response, Headers, URL, etc.)
- Environment variables via `ctx.env.VAR_NAME`
- Database access via `ctx.db.query(sql)`
- User info via `ctx.user` (populated for end-user JWTs, or for service-key callers that pass `X-Butterbase-As-User` — see "Server-to-server function calls" below)
- Caller identity via `ctx.caller` — type, key id, scope, propagated user id (see "Server-to-server function calls" below)
- Sibling-function calls via `ctx.invoke('fn-name', body)` — no manual auth, identity propagates automatically
- App metadata via `ctx.app` and per-request data via `ctx.request` — see "Platform context" below
- Console output (`console.log`, `console.info`, `console.warn`, `console.error`, `console.debug`) — captured and visible in invocation logs
- Network access
- Webhook idempotency via `ctx.idempotency.claim(key)` — see "Idempotent webhook handlers" below
- Background work via `ctx.waitUntil(promise)` — see "Background work" below
:::note
Use `ctx.env`, not `Deno.env.get()` for function-specific environment variables.
:::
## Environment variables
`ctx.env` is populated from three layers, merged in this order (later wins):
1. **App-level** — one shared set per app. Every function in the app inherits these.
2. **Function-level** — per-function `envVars` on `deploy_function` or `manage_function.update_env`. Overrides app-level for that function only.
3. **Platform** — `BUTTERBASE_*` keys the runtime injects (see [Platform context](#platform-context)). Always wins.
So a value set only at the app level shows up in every function; a per-function value shadows the app value just for that function; and `BUTTERBASE_APP_ID` can never be shadowed by either.
### App-level
Set once, inherited by every function:
```bash
# Via MCP
manage_app({ action: "update_env", app_id, env: { STRIPE_SECRET: "sk_live_…", SENTRY_DSN: "…" } })
# Via HTTP
PATCH /v1/{appId}/env
{ "envVars": { "STRIPE_SECRET": "sk_live_…", "SENTRY_DSN": "…" } }
# Pass value `null` to delete a key:
{ "envVars": { "SENTRY_DSN": null } }
```
- Encrypted at rest (AES-256-GCM); values are **never** returned by any read — `GET /v1/{appId}/env` returns only `{ keys, updatedAt }`.
- Keys matching `/^BUTTERBASE_/i` are rejected at write time as reserved.
- Updates fan out cache invalidation to every function in the app in one request; the response lists which functions were invalidated. Next invocation of each function picks up the new values.
- In the dashboard: **App Settings → Environment variables**. The Function detail page splits its env card into an "Inherited from app" section (read-only, marks overridden keys) and a "Function-level" section (editable).
### Function-level
Set at deploy time or updated in place. Values live only on that function.
```bash
# On deploy
deploy_function({ app_id, name, code, envVars: { API_KEY: "…" } })
# Update without redeploying code
manage_function({ action: "update_env", app_id, function_name, env: { API_KEY: "…", OLD_KEY: null } })
```
- Same encryption / never-returned / reserved-prefix guarantees as app-level.
- Function-level entries override app-level entries with the same key.
### Precedence in code
```ts
export async function handler(req, ctx) {
// If STRIPE_SECRET is set at both levels, the function-level value wins.
const stripe = ctx.env.STRIPE_SECRET;
// Platform value — always the real app id, even if a user "sets" it at either level (writes are rejected).
const appId = ctx.env.BUTTERBASE_APP_ID;
}
```
## Platform context
The runtime auto-injects platform-known values so you don't have to set them as env vars yourself. Two surfaces, same source of truth:
**Flat (`ctx.env.BUTTERBASE_*`)** — always present unless noted:
| Key | Value |
|-----|-------|
| `BUTTERBASE_APP_ID` | App ID (e.g. `app_abc123`) |
| `BUTTERBASE_API_URL` | Public API base URL |
| `BUTTERBASE_APP_NAME` | App display name |
| `BUTTERBASE_REGION` | Primary region (e.g. `sjc`) |
| `BUTTERBASE_ANON_KEY` | App's public anon key (safe to expose to browsers) |
| `BUTTERBASE_FRONTEND_URL` | Deployed frontend URL — **absent when no frontend is deployed** |
| `BUTTERBASE_SUBDOMAIN` | Platform-assigned subdomain — absent if unset |
| `BUTTERBASE_STRIPE_ACCOUNT_ID` | Connected Stripe account — absent if billing not configured |
| `BUTTERBASE_AI_DEFAULT_MODEL` | Default model from `manage_ai` — absent if unset |
Optional keys are **omitted** rather than empty-stringed. Branch on `typeof ctx.env.BUTTERBASE_FRONTEND_URL === "string"`.
**Structured (`ctx.app`)** — same values, typed access, optional sub-objects are `null` when absent:
```ts
ctx.app = {
id, name, ownerId, region, subdomain, anonKey, allowedOrigins,
substrateUserId, // substrate user the app is linked to, or null if not linked. ctx.substrate is also null in that case.
frontend: { url } | null, // null when no frontend deployed
auth: { accessTokenTtl, refreshTokenTtlDays, hookFunction },
ai: { defaultModel } | null, // null when AI config empty
billing: { stripeAccountId } | null, // null when billing not connected
}
```
**Per-request (`ctx.request`)** — derived from incoming headers:
```ts
ctx.request = { id, ip, country, functionName }
```
Platform keys are injected **after** your function-specific env vars, so a user-set `BUTTERBASE_APP_ID` will not shadow the real one.
## Server-to-server function calls
A common pattern is a cron-triggered function that fans out to sibling
functions on the same app — e.g. `auto-sync-google` calls `ingest-gmail` and
`ingest-calendar`. The platform gives you three tools for this:
### Calling a Durable Object from a function
Use `ctx.invokeDO(className, instanceKey, body?, opts?)`. See
[Durable Objects → Server-to-server calls](../durable-objects#server-to-server-calls-into-durable-objects).
### `ctx.invoke('fn-name', body)` — the easy path
Use this for any same-app function call. No bearer ceremony, no env-var keys.
```typescript
export async function handler(req, ctx) {
// Identity propagates automatically: if this fn was invoked with an
// end-user JWT, the callee sees the same ctx.user.id.
const r = await ctx.invoke('ingest-gmail', { workspace_id: 'ws_abc' });
const data = await r.json();
return new Response(JSON.stringify({ enqueued: data.queued }), { status: 200 });
}
```
Behavior:
- Authenticated with the per-app internal function key (auto-injected, never
exposed via `ctx.env`).
- `ctx.user.id` propagates: the callee sees the same user the caller saw.
- `ctx.caller.type === 'loopback'` in the callee.
- Cycle guard: `ctx.invoke` chains are capped at depth 4; the 5th hop throws
`ctx.invoke loop limit exceeded` synchronously.
- Returns a standard `Response` (just like `fetch`).
### `ctx.caller` — who called this function
Populated on every invocation. Use it for audit logging or to make policy
decisions in user code without parsing `req.headers.authorization` by hand.
```ts
ctx.caller = {
type: 'service_key' | 'end_user_jwt' | 'loopback' | 'anonymous',
keyId: string | null, // present iff type === 'service_key'
scope: string | null, // first app- or gateway-scope on the key
userId: string | null, // user this request is acting on behalf of
}
```
| Caller | type | userId | keyId |
|--------|------|--------|-------|
| Browser with end-user JWT | `end_user_jwt` | JWT `sub` | `null` |
| Cron / external service with `bb_sk_*` | `service_key` | `null` (unless impersonating) | api key row id |
| Sibling function via `ctx.invoke` | `loopback` | propagated | `null` |
| No bearer / invalid bearer | `anonymous` | `null` | `null` |
### `X-Butterbase-As-User` — when you have to call from outside
For callers that can't use `ctx.invoke` (cron jobs running outside the
runtime, external services, scripts), send the header alongside an
app-scoped `bb_sk_*`:
```http
POST /v1/app_abc/fn/ingest-gmail
Authorization: Bearer bb_sk_…
X-Butterbase-As-User: 11111111-2222-3333-4444-555555555555
Content-Type: application/json
{ "workspace_id": "ws_abc" }
```
The runtime populates `ctx.user.id` with the asserted id before invoking the
function — no in-function bearer comparison required.
**Per-function gate.** Functions can opt out of impersonation with
`allow_service_key_impersonation: false` at deploy time (or via
`manage_function action: "update_settings"`). The platform 403s any
`X-Butterbase-As-User` header on those functions at the edge. Use this for
admin-only or billing-webhook handlers that must never act on behalf of an
end user.
### Anti-pattern: bearer-equality checks
Some older templates compared the incoming bearer to their own
`ctx.env.BUTTERBASE_API_KEY` to decide whether to trust an `as_user_id` body
field:
```ts
// ❌ Don't do this — fragile under key rotation, multi-key environments,
// or cloned apps where every function gets a different key.
const expected = `Bearer ${ctx.env.BUTTERBASE_API_KEY}`;
if (req.headers.get('authorization') === expected) {
userId = body.as_user_id;
}
```
Replace with `ctx.user.id` (impersonation is now a platform concern) or
`ctx.invoke` (no bearer involved at all).
## RLS in functions
Functions respect RLS policies based on how they're invoked:
| Invocation | Role | RLS |
|-----------|------|-----|
| End-user JWT | butterbase_user | Enforced — sees only user's data |
| Platform API key | butterbase_service | Bypassed — sees all data |
| Cron trigger | butterbase_service | Bypassed — sees all data |
### User-scoped function
```typescript
export default async function handler(req: Request, ctx: any): Promise {
if (!ctx.user) {
return new Response('Unauthorized', { status: 401 });
}
// Automatically filtered to current user's orders (RLS enforced)
const orders = await ctx.db.query('SELECT * FROM orders');
return new Response(JSON.stringify(orders.rows), {
headers: { 'Content-Type': 'application/json' }
});
}
```
### Testing RLS from service functions
Use `ctx.db.asUser()` and `ctx.db.asAnon()` to run queries under a specific role:
```typescript
export default async function handler(req: Request, ctx: any): Promise {
const userId = 'some-user-uuid';
// Runs as butterbase_user with RLS enforced
const userPosts = await ctx.db.asUser(userId, async (db) => {
const result = await db.query('SELECT * FROM posts');
return result.rows;
});
// Runs as butterbase_anon with RLS enforced
const publicProducts = await ctx.db.asAnon(async (db) => {
const result = await db.query('SELECT * FROM products');
return result.rows;
});
return new Response(JSON.stringify({ userPosts, publicProducts }), {
headers: { 'Content-Type': 'application/json' }
});
}
```
## Using environment variables
```typescript
// Deploy with: envVars: { "API_KEY": "secret123", "BASE_URL": "https://api.example.com" }
export default async function handler(req: Request, ctx: any): Promise {
const apiKey = ctx.env.API_KEY;
const baseUrl = ctx.env.BASE_URL;
const response = await fetch(`${baseUrl}/data`, {
headers: { 'Authorization': `Bearer ${apiKey}` }
});
return new Response(await response.text());
}
```
### Updating environment variables
Use `PATCH /v1/{app_id}/functions/{name}/env` to update env vars without redeploying:
```json
PATCH /v1/{app_id}/functions/{name}/env
{
"envVars": {
"API_KEY": "new-value",
"OLD_KEY": null
}
}
```
New values are **merged** with existing env vars (not replaced). Set a value to `null` to delete a key.
## Idempotent webhook handlers with ctx.idempotency.claim()
Third-party webhook providers (Stripe, Telegram, GitHub, Slack, Twilio, Discord) retry delivery on non-2xx responses with the **same event id**. Without dedup, that means processing the same webhook twice (sending the same email twice, charging the same card twice, posting the same Slack message twice).
`ctx.idempotency.claim(key)` is an atomic primitive that returns `true` the first time a key is seen and `false` on every retry, so your handler can safely ack duplicate deliveries:
```typescript
export default async function handler(req: Request, ctx: any): Promise {
const event = await req.json();
// Returns true the first time, false on every retry of the same event.
if (!(await ctx.idempotency.claim(event.id, { scope: 'stripe' }))) {
// Already processed — ack the retry without re-running side effects.
return new Response('duplicate', { status: 200 });
}
await processEvent(event);
return new Response('ok', { status: 200 });
}
```
**Options:**
| Option | Type | Default | Purpose |
|---|---|---|---|
| `scope` | `string` | `"default"` | Namespace claims per provider so keys can never collide (e.g. `"stripe"`, `"telegram"`, `"github"`). |
| `ttlSeconds` | `number` | none | Mark the claim with an expiry so you know which keys are safe to clean up. |
**Storage and cleanup.** Claims live in a per-app system table `_idempotency_keys` in your data-plane DB. The runtime never deletes them automatically — schedule a cleanup yourself, e.g. from a daily cron function:
```typescript
export default async function handler(_req: Request, ctx: any): Promise {
await ctx.db.query("DELETE FROM _idempotency_keys WHERE expires_at < now()");
return new Response("ok");
}
```
**Behavior:**
- The claim runs as `butterbase_service` regardless of who invoked the function (anon webhook, end-user, cron) so RLS never blocks it.
- Keys are limited to 255 characters; longer keys throw.
- The claim is atomic via `INSERT ... ON CONFLICT DO NOTHING` — concurrent invocations with the same key are safe.
## Background work with ctx.waitUntil()
Use `ctx.waitUntil(promise)` to keep a function alive after the response is sent. The response is returned to the caller immediately while the background work continues.
This is useful for fire-and-forget tasks like sending emails, logging to external services, or syncing data to third-party APIs.
```typescript
export default async function handler(req: Request, ctx: any): Promise {
const body = await req.json();
// Schedule background work — continues after response is sent
ctx.waitUntil(
fetch("https://api.email.com/v1/send", {
method: "POST",
headers: { "Content-Type": "application/json" },
body: JSON.stringify({ to: body.email, subject: "Welcome!" }),
})
);
// You can register multiple waitUntil promises
ctx.waitUntil(
ctx.db.query("INSERT INTO activity_log (event) VALUES ($1)", ["user_signup"])
);
// Response is returned immediately — background work continues
return new Response(JSON.stringify({ status: "accepted" }), {
headers: { "Content-Type": "application/json" }
});
}
```
**Behavior:**
- Background work has a **30-second timeout** after the response is sent. Promises that take longer are cancelled.
- `ctx.db` is available inside waitUntil promises.
- Failures in background work are silently swallowed — they do not affect the response.
- Use `Promise.allSettled` semantics: all registered promises run regardless of individual failures.
## Calling functions from your frontend
HTTP-triggered functions are available at:
```
ANY /v1/{app_id}/fn/{function_name}
```
Any HTTP method is supported. End-user tokens are forwarded to the function.
```javascript
const response = await fetch(`${API_BASE}/v1/${appId}/fn/hello-world`, {
method: 'POST',
headers: {
'Content-Type': 'application/json',
'Authorization': `Bearer ${userAccessToken}`
},
body: JSON.stringify({ input: 'data' })
});
```
## Cron functions
Use standard cron expressions:
| Expression | Schedule |
|-----------|----------|
| `* * * * *` | Every minute |
| `*/5 * * * *` | Every 5 minutes |
| `0 * * * *` | Every hour |
| `0 9 * * *` | Daily at 9 AM |
| `0 0 * * 1` | Every Monday at midnight |
## Function metrics
Each function tracks: total invocation count, error count and rate, average execution duration, and last invocation time.
## Invocation logs
Logs include: HTTP method and path, status code, execution duration, memory usage, error messages with stack traces, and console output (`consoleLogs`) from `console.log/info/warn/error/debug` calls.
### Reading logs for a deleted function (forensics)
By default, `get_function_logs` returns 404 for soft-deleted functions — the logs are still in the database but hidden so the function looks gone. For post-incident forensics, pass `include_deleted=true`:
```bash
butterbase functions logs my-fn --include-deleted
```
```typescript
await admin.functions.logs('my-fn', { includeDeleted: true });
```
```http
GET /v1/{app_id}/functions/{name}/logs?include_deleted=true
```
This is owner-scoped (same auth as the default path) — only the app owner can read forensic logs.
## Pausing an app (kill-switch)
`pause_app` is a single API call that halts **all data-plane traffic** for an app — useful when a buggy webhook is spamming end users, a runaway cron is burning external API quotas, or you want to take an app offline for maintenance.
While paused:
- Function invocations (HTTP and cron) return **503** with code `APP_PAUSED`.
- Data-plane CRUD (`select_rows`, `insert_row`, REST) returns 503.
- Storage uploads / downloads return 503.
- Realtime websockets close with code `1013` ("Try again later").
What stays available so you can recover:
- All control-plane endpoints (`list_apps`, `get_app_config`, schema, RLS, env vars, the `pause_app` toggle itself).
- Auth (login / signup) — operators may need to re-authenticate while paused.
**MCP:**
```json
{ "app_id": "app_abc123", "paused": true, "reason": "investigating outbound spam" }
```
**CLI:**
```bash
butterbase apps pause app_abc123 --reason "investigating outbound spam"
butterbase apps resume app_abc123
```
**SDK:**
```typescript
await admin.config.pause('investigating outbound spam');
await admin.config.resume();
```
The pause is durable (a column on `apps`) — restarts of the control-API don't clear it. Owner-only, audited as `app.config.paused`.
---
## Core Concepts / Agents
Agents are multi-step LLM workflows defined declaratively as a **graph spec**. A graph spec is JSON: a set of nodes connected by edges, where each node is either an LLM call, a tool call, or an end marker. The agent runtime executes the graph step by step, persists checkpoints between steps so runs can resume, and streams events back to the caller over SSE.
Agents are stored per-app. They can be invoked from your dashboard, the CLI, the MCP server, the SDK, or — for `public` agents — anonymous HTTP.
## Graph spec at a glance
```json
{
"spec_version": "1",
"entry": "classify",
"nodes": {
"classify": {
"type": "llm",
"model": "anthropic/claude-3.5-haiku",
"system_prompt": "Classify the user's request as 'billing', 'support', or 'sales'.",
"input_template": "{{ input.message }}",
"output_key": "category",
"tools": []
},
"respond": {
"type": "llm",
"model": "anthropic/claude-3.5-sonnet",
"system_prompt": "You are a {{ state.category }} agent.",
"input_template": "{{ input.message }}",
"output_key": "reply",
"tools": [
{ "source": "function", "name": "lookup_account" }
]
},
"done": { "type": "end", "output_template": "{{ state.reply }}" }
},
"edges": [
{ "from": "classify", "to": "respond" },
{ "from": "respond", "to": "done" }
],
"tools": {
"builtin": ["select_rows"],
"mcp_servers": [],
"functions": ["lookup_account"]
},
"limits": {
"max_steps": 20,
"max_tool_calls": 50,
"max_parallel_tools": 4,
"timeout_seconds": 300,
"human_timeout_seconds": 86400
}
}
```
The spec is versioned (`spec_version: "1"`), validated server-side, and rejected at run time if it references a tool that does not exist.
## Node types
| Type | Purpose |
|---|---|
| `llm` | Call a model. Renders `system_prompt` and `input_template` against current state, optionally exposes `tools` to the model, writes the response (or any tool results) into `output_key`. |
| `tool` | Invoke a tool directly without an LLM. Useful for deterministic preprocessing (`select_rows`, a known function call, etc). |
| `end` | Render `output_template` against state and emit it as the run's final output. |
Edges describe sequencing — each node, when it finishes, transitions to its outgoing edge's target. The graph must be a DAG that reaches `end` from `entry`.
## Tools
Three sources can be exposed to an agent:
### Built-in tools
Platform-managed tools that talk to your app's database, storage, KV, etc. Listed in `tools.builtin` by name. The runtime enforces RLS by mapping the caller (`end_user` → `butterbase_user`, otherwise `butterbase_service`).
### MCP tools
Tools served by a Model Context Protocol server you've registered via `POST /v1/{app_id}/mcp-servers`. Reference them in `tools.mcp_servers` by `server_id` + the subset of tool names you want exposed.
### Functions
Any [serverless function](/core-concepts/functions/) you've deployed and **marked as an agent tool** is callable by the agent. Mark a function:
```http
POST /v1/{app_id}/functions
{
"name": "lookup_account",
"code": "...",
"agent_tool": true,
"agent_tool_description": "Look up a customer by email or account ID.",
"agent_tool_mode": "read_only",
"agent_tool_exposed_to": "developer_only"
}
```
Then list it in the agent spec's `tools.functions` array. If you reference a function that does not have `agent_tool: true`, the runtime silently skips it — the dashboard editor warns you about this before save.
`agent_tool_mode`:
- `read_only` — no approval needed.
- `read_write` — the runtime pauses the run and emits a `run_paused` event with an approval payload; resume the run after a human approves.
`agent_tool_exposed_to`:
- `developer_only` — usable only from dashboard / CLI test runs.
- `end_user` — also usable from public agent invocations.
## Run lifecycle
```
queued → running → (paused →) running → completed | failed | cancelled
```
A run progresses through the graph one step at a time. After each node, a checkpoint is written. If the runtime restarts, the run resumes from the last checkpoint.
Pausing happens when a `read_write` tool is invoked or the agent explicitly calls a HITL primitive — the next `POST /runs/{id}/resume` (or dashboard "Approve" button) continues from the checkpoint.
The complete event stream over SSE:
| Event | When |
|---|---|
| `run_start` | Run accepted, before any node runs. |
| `node_start` / `node_end` | A node is about to run / has finished. Includes `node_id` and `step`. |
| `tool_call_start` / `tool_call_end` | A tool is about to be invoked / has returned. Includes `tool_name`, `args`, `result`. |
| `llm_token_usage` | Per-LLM-call token counts. |
| `run_paused` | A `read_write` tool needs human approval. |
| `run_cancelled` | The caller cancelled the run. |
| `run_failed` | An error terminated the run. |
| `run_end` | Run completed successfully; payload contains the rendered `output_template`. |
## Idempotency
Every `POST /runs` carries an implicit idempotency key — a SHA-256 hash of the request body. Re-posting the same body returns the existing run (HTTP 200) instead of creating a duplicate. Submitting a *different* body with the same agent name within the dedupe window returns `409 conflict`.
## Limits
Each spec declares its own limits. The runtime hard-caps them server-side:
| Limit | Cap |
|---|---|
| `max_steps` | 200 graph traversals per run |
| `max_tool_calls` | 500 tool invocations per run |
| `max_parallel_tools` | 16 tools in flight |
| `timeout_seconds` | 1 hour wall-clock |
| `human_timeout_seconds` | 7 days while paused for approval |
Apps also have per-agent access controls — `max_runs_per_user_per_hour`, `daily_budget_usd`, `max_concurrent_runs`, etc. — set via the dashboard's "Access and limits" section or `PATCH /v1/{app_id}/agents/{name}`.
## Visibility
| Visibility | Who can start runs |
|---|---|
| `private` | Owner of the app (dashboard, CLI, MCP). |
| `authenticated` | Any logged-in user of the app. |
| `public` | Anyone with the app's public anon key. Use with caution — combine with strict rate limits and a `daily_budget_usd`. |
## See also
- [Agents quickstart](/getting-started/agents-quickstart/) — deploy a function, expose it as a tool, run an agent end-to-end.
- [Agents API reference](/api-reference/agents-api/) — every REST endpoint, every event payload.
- [Serverless functions](/core-concepts/functions/) — how to deploy the functions you'll expose as tools.
---
## Core Concepts / Frontend Deployment
Deploy your frontend directly from Butterbase. Build your app locally, zip the output, upload it, and deploy to a live URL powered by Cloudflare Pages.
Frontend deployments are served globally and aren't tied to a single [region](/core-concepts/regions/) — your static assets reach users fast no matter where your app's backend lives.
## How it works
1. Call `create_frontend_deployment` to get a deployment ID and upload URL
2. Upload your built frontend as a zip file
3. Call `start_frontend_deployment` to trigger the deployment
4. Your site goes live at a `.pages.dev` URL
## Supported frameworks
| Framework | Value | Notes |
|-----------|-------|-------|
| React (Vite) | `react-vite` | `dist/` folder from `npm run build` |
| Next.js (static) | `nextjs-static` | `out/` folder from `next build && next export` |
| Static HTML | `static` | Any plain HTML/CSS/JS files |
| Other | `other` | Any framework that produces static output |
## Deploying via MCP
**Step 1: Create deployment**
```
create_frontend_deployment({ app_id: "app_abc123", framework: "react-vite" })
```
**Step 2: Upload your zip**
```bash
curl -X PUT "{uploadUrl}" \
-H "Content-Type: application/zip" \
--data-binary @frontend.zip
```
**Step 3: Start deployment**
```
start_frontend_deployment({ app_id: "app_abc123", deployment_id: "uuid-1234" })
```
## Deployment statuses
| Status | Meaning |
|--------|---------|
| `WAITING` | Created, awaiting zip upload |
| `UPLOADING` | Files are being processed |
| `BUILDING` | Deployment is being built |
| `READY` | Succeeded — URL is assigned |
| `ERROR` | Failed — check the error message |
| `CANCELED` | Deployment was canceled |
:::note
`READY` means the deployment is accepted by Cloudflare — but edge propagation can take several minutes. Verify by requesting the live URL before telling users the site is updated.
:::
## Creating the zip file correctly
:::caution
**Do not use** Windows File Explorer "Send to Compressed folder", PowerShell `Compress-Archive`, or `ZipFile.CreateFromDirectory` without explicit `/` paths. These tools create backslash paths inside the zip, causing Cloudflare Pages to serve assets with wrong MIME types.
:::
### Recommended: Node.js archiver
```bash
npm install archiver --save-dev
```
```javascript
// zip-dist.js
const fs = require('fs');
const path = require('path');
const archiver = require('archiver');
const output = fs.createWriteStream(path.join(__dirname, 'frontend.zip'));
const archive = archiver('zip', { zlib: { level: 9 } });
output.on('close', () => {
console.log(`frontend.zip created (${archive.pointer()} bytes)`);
});
archive.on('error', (err) => { throw err; });
archive.pipe(output);
archive.directory('dist/', false);
archive.finalize();
```
### Alternative: Git Bash / WSL
```bash
cd dist && zip -r ../frontend.zip .
```
## Environment variables
Set environment variables for frontend builds:
```json
PUT /v1/{app_id}/frontend/env
{
"VITE_API_URL": "https://api.butterbase.ai/v1/app_abc123",
"VITE_APP_NAME": "My App"
}
```
Framework-specific prefixes:
- **Vite:** `VITE_` (e.g., `VITE_API_URL`)
- **Next.js:** `NEXT_PUBLIC_` (e.g., `NEXT_PUBLIC_API_URL`)
- **Create React App:** `REACT_APP_` (e.g., `REACT_APP_API_URL`)
## SPA routing
For single-page app frameworks, a `_redirects` file is automatically injected so all routes serve `index.html`. Client-side routing works out of the box. If your zip includes a custom `_redirects`, it is preserved.
## Redeployment
Each deployment is kept independently until you hit your plan's deployment limit. Delete old deployments you no longer need.
## Custom domains
Point your own hostname at this deployment — `app.example.com` instead of `*.pages.dev` — with SSL issued and renewed automatically. Requires the **Launch plan or above**.
```bash
butterbase domains add app.example.com
butterbase domains status
```
Full setup, DNS records, validation methods, apex handling, and troubleshooting live on the [Custom Domains](/core-concepts/custom-domains/) page.
## Limits
| Limit | Value |
|-------|-------|
| Maximum deployment size | 100 MB (compressed) |
| Upload URL expiration | 15 minutes |
| Deployments per app — Playground | 2 |
| Deployments per app — Launch | 10 |
| Deployments per app — Certified | 25 |
| Deployments per app — Enterprise | Unlimited |
---
## Core Concepts / Preview Deployments
A preview deployment is a copy of your live app that you can safely break.
It has its own database, its own files, its own sign-ups, and its own URL — so nothing you do in a preview can reach the app your real users are using. When the change works, you push it live.
Think of it as a rehearsal space: same stage, same props, no audience.
:::note[This is a whole second app, not just a frontend deploy]
"Deploying your frontend" pushes new files to your existing app. A *preview deployment* is bigger than that — it's a second copy of everything, backend included. The two are unrelated.
:::
## What's in a preview
A preview starts as a copy of your live app, and that includes **your real data**:
- Every row in every table.
- Every account that has signed up, including their password — so people can sign in to the preview with the password they use on the live app.
- Every uploaded file.
:::caution[A preview holds a real copy of your users' data]
If your live app stores personal information, your preview now stores a second copy of it. Anyone you give access to the preview can read all of it. Treat it as carefully as you treat the real thing.
:::
### What deliberately doesn't come along
Some things are left behind on purpose, so a preview can't reach into the real world and do damage:
| Left behind | Why |
|---|---|
| The **values** of your secrets and API keys | A preview must never hold your live keys — otherwise a test checkout charges a real credit card. The key *names* are created but left **empty**, so anything that needs one fails loudly instead of quietly spending your money. Fill them in with [preview secrets](#preview-secrets). |
| Connected accounts (Stripe, Google, and so on) | Copied and then disconnected, so the preview can't act as you. Reconnect them on the preview if you need them. |
| Scheduled jobs and integrations | Switched **off**. A preview copy of your nightly billing job should not run. |
| Billing and analytics history | That history belongs to your live app. |
One more: uploaded files get new ids in the preview. If your app stores a file's id inside one of your own tables, that column still points at the live app's copy of the file.
## Creating a preview
You get **one** preview per app, and it's always created in the same place in the world as your live app.
**Just ask your AI assistant** — "create a preview deployment for this app" — or do it yourself:
**MCP**
```
manage_preview({ app_id: "app_abc123", action: "create" })
```
**REST**
```bash
curl -X POST https://api.butterbase.ai/v1/apps/app_abc123/staging \
-H "Authorization: Bearer $BUTTERBASE_API_KEY"
```
**Dashboard** — open your app and choose **Preview** in the sidebar.
Creating hands you back a `job_id`. Copying your data takes as long as your data needs it to, so this is **not instant**:
```
manage_preview({ app_id: "app_abc123", action: "status" })
```
Until that job says `completed`, you do not have a usable preview yet — it won't show up in `status` and it isn't connected to your app.
## Preview secrets
Your preview knows the *names* of your secrets but none of their *values*. Preview secrets are how you fill them in — usually with test credentials, so the preview talks to Stripe's test mode while your live app keeps the real key.
```
manage_preview({
app_id: "app_abc123",
action: "set_env_overrides",
env_overrides: { PAYMENT_PROVIDER_KEY: "sk_test_..." }
})
```
Two things worth knowing:
- They're stored against your **live** app, so you can set them *before* you create the preview and it comes up already working. They also survive a reset, or deleting the preview and making a new one.
- Reading them back gives you the key **names** only, never the values. Nothing can read a secret back out.
Setting them replaces the whole set at once. Pass an empty object to clear them.
## Pushing a preview live
Pushing live copies your preview's **structure** onto your live app: your tables and fields, your access rules, your functions, your settings, and your code — and it deploys the frontend. This is a real deploy to your real app.
**Your live data stays exactly where it is.** Rows are never overwritten and never removed. If you added a table in the preview, pushing live creates that table on your live app — empty.
Always look before you leap:
```
promote_preview({ app_id: "app_abc123", action: "check" })
```
```json
{
"can_promote": true,
"additive": ["ALTER TABLE orders ADD COLUMN refunded_at timestamptz"],
"blocked": [],
"ignored_removals": []
}
```
`additive` is the list of changes that are safe to apply. If `blocked` is empty and `can_promote` is true, you're clear:
```
promote_preview({ app_id: "app_abc123", action: "run" })
```
### What gets blocked, and why
Butterbase will not let a push-live throw away your real users' data. If your change needs any of these, the **whole push is cancelled** and nothing at all is applied:
| What you changed in the preview | Why it's blocked |
|---|---|
| Deleted a field | Your live app has real values in it. Deleting the field throws them away. |
| Deleted a table | The same, for every row in it. |
| Changed a field's type — text to number, say | Existing values might not survive the conversion. |
| Made an existing field required | Live rows that are currently blank would break. |
It's all-or-nothing on purpose. If your change has one blocked piece and five safe ones, none of the six go through — an app that's half-updated is in worse shape than one that didn't update at all.
Butterbase names the exact change that's stuck. If you really do mean it, make that one change on your live app directly, then push again.
One pair that looks the same and isn't:
- **Adding a new field that's required, with a default value** is safe even when the table already has rows — every existing row gets the default. This goes through fine.
- **Making an existing field required** can fail against live rows that are blank right now. This is blocked.
### Deleting things is ignored, not applied
If you delete a table or a field in your preview, pushing live **keeps** it on your live app. The preview lists these under `ignored_removals` so you know about them — they never block the push, and they're never applied.
Deleting something from your live app is a decision you make against the live app directly, on purpose.
## Starting a preview over
Resetting throws away everything in the preview and copies it fresh from your live app. Use it when the preview has wandered somewhere you don't want to be.
```
manage_preview({ app_id: "app_abc123", action: "reset" })
```
Reset also puts the preview's **structure** back in line with your live app — which means it can destroy things that only ever existed in the preview: a table you added, a field you deleted, a rule you tightened. It tells you exactly what it destroyed:
> Reset changed the preview's structure to match your live app and, in doing so, destroyed 2 things that existed only on the preview or differed from it: dropped preview-only column "orders"."currency"; made "orders"."status" optional again to match. Reset makes the preview match your live app; your live app was not touched.
Reset only ever destroys things in the **preview**. Your live app is never written to by a reset.
Your preview secrets survive a reset.
## Previews you stop using get paused
A preview nobody has touched for 30 days is **paused**, not deleted — it stops serving traffic, but all its data stays put. Resume it from the Preview page whenever you want it back.
Actually deleting a preview is always something you do deliberately, by hand.
## What it costs, and what it counts against
- **Preview deployments need the Launch plan or above.** On the free Playground plan you'll see an upgrade prompt instead of a create button.
- **A preview counts as one project** against your plan's limit. On Launch (3 projects), your live app + its preview = 2 of 3, leaving room for one more app. If you're already at your limit, creating a preview fails and tells you so.
- **One preview per app.**
- **A preview lives in the same region as your live app**, and the link between them is region-local.
- **You can't move an app to another region while it has a preview.** Delete or disconnect the preview first, then move. This works both ways — you can't move the preview away from its app either.
- **A preview bills like a normal app.** It has its own database and its own usage, and it counts toward your plan. The dashboard's Billing page shows preview usage separately from your live app's.
## Disconnecting a preview
Disconnecting breaks the link between the two apps without deleting either one. The preview app stays exactly where it is — it just stops being *your app's preview*, and you're free to create a new one.
```bash
curl -X DELETE https://api.butterbase.ai/v1/apps/app_abc123/staging \
-H "Authorization: Bearer $BUTTERBASE_API_KEY"
```
To actually get rid of it, delete that app the way you'd delete any other app.
## Reference
The REST paths below still say `staging` — that's the internal name for the same thing, and they are unchanged.
### MCP tools
| Tool | Actions |
|---|---|
| `manage_preview` | `create`, `status`, `reset`, `get_env_overrides`, `set_env_overrides` |
| `promote_preview` | `check`, `run` |
:::caution[These tools were renamed]
They used to be `manage_staging` and `promote_staging`, and `promote`'s read-only action used to be called `preview`. The old names are gone — update any saved prompt or script that still calls them.
:::
### REST endpoints
| Method | Path |
|---|---|
| `POST` | `/v1/apps/:app_id/staging` |
| `GET` | `/v1/apps/:app_id/staging` |
| `DELETE` | `/v1/apps/:app_id/staging` |
| `POST` | `/v1/apps/:app_id/staging/reset` |
| `GET` | `/v1/apps/:app_id/staging/promote/preview` |
| `POST` | `/v1/apps/:app_id/staging/promote` |
| `GET` | `/v1/apps/:app_id/staging/env-overrides` |
| `PUT` | `/v1/apps/:app_id/staging/env-overrides` |
Track any job with `GET /v1/clone-jobs/:job_id`.
---
## Core Concepts / Custom Domains
Every frontend deployment gets a `*.pages.dev` URL for free. A **custom domain** puts that same deployment on a hostname you own — `app.example.com`, or the apex `example.com` — with an SSL certificate Butterbase issues and renews for you.
Custom domains are a **Launch plan or above** feature.
## How it works
Butterbase uses Cloudflare for SaaS. When you add a hostname:
1. Butterbase registers it as a *custom hostname* with Cloudflare and stores it against your app.
2. A KV mapping is written so the edge dispatcher knows which app that hostname belongs to.
3. You point DNS at us and prove you own the name.
4. Cloudflare issues a certificate. Renewal is automatic and you never touch it.
You keep control of your DNS the whole way through — nothing about this requires moving your domain to Cloudflare.
## Requirements
| Requirement | Why |
|---|---|
| Launch plan or above | The `custom_domain` plan feature gates the endpoint. Playground apps get a `403`. |
| The app owns the domain | A hostname is globally unique across Butterbase — a second app adding the same name gets a `409`. |
| A live frontend deployment | The domain routes to whatever the app currently serves. Add the domain first if you like; it just won't have anything to serve yet. |
| WfP deployment backend | Apps on the legacy backend return `400`. New apps are already on WfP. |
| Access to your DNS provider | You must be able to create CNAME and TXT records. |
## Step 1 — Pick a validation method
`validation_method` decides how Cloudflare proves you own the hostname before it issues a certificate. Choosing wrong here is the single most common reason a domain sits at "pending" forever.
| Method | How it works | Use it when | Do **not** use it when |
|---|---|---|---|
| `http` *(default)* | Cloudflare serves a challenge file from our zone; you only add the routing CNAME | Subdomains, and any DNS provider that isn't Cloudflare | Your DNS is a Cloudflare-**proxied** zone, or the hostname is an **apex on Cloudflare** — the orange-cloud intercept swallows the challenge, and CNAME flattening hides the record entirely |
| `txt` | Cloudflare gives you a TXT record to add in DNS | Apex domains on Cloudflare, proxied zones, or any time you want the method that always works | — |
Rule of thumb: **subdomain on a normal DNS provider → `http`. Anything on Cloudflare, or any apex → `txt`.**
## Step 2 — Add the domain
**Dashboard:** **App → Settings → Custom domains → Add domain.**
**CLI:**
```bash
butterbase domains add app.example.com
butterbase domains add example.com --validation-method txt
```
**REST API:**
```
POST /v1/{app_id}/custom-domains
Authorization: Bearer {token}
{ "hostname": "app.example.com", "validation_method": "http" }
```
**MCP:**
```
manage_frontend({
app_id: "app_abc123",
action: "configure_custom_domain",
domain_action: "add",
hostname: "app.example.com"
})
```
The `201` response carries everything you need for the next step:
```json
{
"domain": { "id": "…", "hostname": "app.example.com", "status": "pending", "ssl_status": "pending" },
"cname_target": "butterbase.dev",
"validation_method": "http",
"verification_records": [{ "txt_name": "_acme-challenge.app.example.com", "txt_value": "…" }],
"ownership_verification": null,
"instructions": "Add a CNAME record at your DNS provider: …"
}
```
Keep `domain.id` — it's what the status, verify, and delete calls take.
## Step 3 — Add your DNS records
### If you chose `http`
One record:
| Type | Name | Value |
|---|---|---|
| CNAME | `app.example.com` | `butterbase.dev` |
:::caution
**Cloudflare DNS users: set this record to DNS-only (grey cloud).** A proxied (orange cloud) CNAME pointing between two different Cloudflare accounts returns **Error 1014** and will never work.
:::
### If you chose `txt`
Two records, sometimes three:
| # | Type | Name | Value |
|---|---|---|---|
| 1 | CNAME | `app.example.com` | `butterbase.dev` — for an apex, use whatever your provider offers at the root (Cloudflare's flattened CNAME is fine) |
| 2 | TXT | `verification_records[].txt_name` | `verification_records[].txt_value` — authorizes the certificate |
| 3 | TXT | `ownership_verification.name` | `ownership_verification.value` — **only** returned for Cloudflare-proxied zones; add it if present |
If `verification_records` came back empty, Cloudflare hasn't minted the record yet. Call the status endpoint in a minute and it will be there.
## Step 4 — Watch it go active
```bash
butterbase domains status
```
```
GET /v1/{app_id}/custom-domains/{domain_id}/status
```
The endpoint re-reads live state from Cloudflare on every call and writes it back, so it's always current.
```json
{
"domain": {
"hostname": "app.example.com",
"status": "active",
"ssl_status": "active",
"verification_errors": null
},
"cname_target": "butterbase.dev",
"verification_records": [],
"ownership_verification": null
}
```
| Field | Meaning |
|---|---|
| `status` | Cloudflare's hostname state. `pending` → waiting on DNS/validation. `active` → routing works. |
| `ssl_status` | Certificate state. `pending`/`initializing`/`pending_validation` → still issuing. `active` → HTTPS works. |
| `verification_errors` | Populated when Cloudflare rejected validation — read this first when something is stuck. |
**You're live when `status` and `ssl_status` are both `active`.** Typical time is 5–15 minutes; DNS propagation is usually the long pole.
If it's stuck, re-trigger validation without recreating the domain (this preserves the original `validation_method`):
```bash
butterbase domains verify
```
```
POST /v1/{app_id}/custom-domains/{domain_id}/verify
```
## Apex vs `www`
Butterbase does **not** force a redirect between the apex and `www`. Both are just hostnames; either can be canonical.
- Decide which one is canonical and add **that one** as the custom domain.
- Redirect the other at your DNS provider's edge (Cloudflare Redirect Rules, Netlify/Vercel DNS redirects, an ALIAS + rule at your registrar, etc.).
- Apex on Cloudflare requires `validation_method: "txt"`. Apex on a provider that supports CNAME flattening works with `http`.
- No CNAME flattening available? Use `www.example.com` as the custom domain and redirect the apex to it.
## Managing domains
| Method | Path | MCP `domain_action` | Purpose |
|--------|------|---------------------|---------|
| POST | `/v1/{app_id}/custom-domains` | `add` | Add a hostname (accepts `validation_method`) |
| GET | `/v1/{app_id}/custom-domains` | `list` | List every hostname on the app |
| GET | `/v1/{app_id}/custom-domains/{id}/status` | `status` | Live verification + SSL status |
| POST | `/v1/{app_id}/custom-domains/{id}/verify` | `verify` | Re-trigger validation |
| DELETE | `/v1/{app_id}/custom-domains/{id}` | `remove` | Remove the hostname |
```bash
butterbase domains list
butterbase domains add [--validation-method http|txt]
butterbase domains status
butterbase domains verify
butterbase domains delete [--yes]
```
```typescript
await bb.admin.domains.list();
await bb.admin.domains.add('app.example.com', 'txt');
await bb.admin.domains.getStatus(domainId);
await bb.admin.domains.verify(domainId);
await bb.admin.domains.remove(domainId);
```
:::caution
Deleting a domain stops all traffic to that hostname immediately. Visitors get an error until you point DNS somewhere else.
:::
## Troubleshooting
| Symptom | Cause | Fix |
|---|---|---|
| `403` on add | App's org is on a tier without `custom_domain` | Upgrade — see [Plans & Usage](/core-concepts/plans-and-usage/) |
| `409 already registered` | The hostname is claimed — by this app, or another one | If it's this app, just check status. Otherwise pick a different hostname. |
| `400` about the deployment backend | App is on the legacy backend | Migrate the app to the WfP backend first |
| `503 Cloudflare is not configured` | Self-hosted instance without Cloudflare credentials | Configure Cloudflare on the control API |
| **Error 1014** in the browser | Proxied (orange-cloud) CNAME across Cloudflare accounts | Switch the record to DNS-only (grey cloud) |
| Stuck `pending` on an apex | Used `http` on a Cloudflare-hosted zone | Delete and re-add with `validation_method: "txt"` |
| `ssl_status` stuck, `status` active | TXT validation record missing or wrong | Re-read `verification_records` from the status endpoint and fix the record, then `verify` |
| Domain resolves but shows the old site | Edge cache after a redeploy | Wait a few minutes and hard-refresh — see [Frontend Deployment](/core-concepts/frontend-deployment/) |
## Related
- [Frontend Deployment](/core-concepts/frontend-deployment/) — getting a site live in the first place
- [Edge SSR Deployment](/core-concepts/edge-ssr-deployment/) — server-rendered apps
- [Plans & Usage](/core-concepts/plans-and-usage/) — which plans include custom domains
- Cloned an app? Custom domains do **not** transfer — see [Configuring Your Clone](/templates/configure/)
---
## Core Concepts / Durable Objects
Durable Objects (DOs) are Butterbase's stateful compute primitive. Each DO is an actor identified by a class + instance ID; the actor lives in memory across requests, persists state via built-in transactional storage, and can hold WebSocket connections. They are the natural fit for **anything where state is per room/per user/per agent**: chat rooms, multiplayer games, real-time collaboration, leaderboards, rate limiters, long-running AI agents.
For stateless work, use [Functions](/core-concepts/functions/) instead.
## Quick start
Write a single TypeScript file that exports one class:
```ts
// chat-room.ts
export class ChatRoom {
constructor(public state: DurableObjectState, public env: any) {}
async fetch(req: Request): Promise {
if (req.headers.get('Upgrade') === 'websocket') {
const pair = new WebSocketPair();
this.state.acceptWebSocket(pair[1]);
// Bootstrap the new client with current state. Without this, late
// joiners see nothing until the next message arrives.
const messages: any[] = (await this.state.storage.get('messages')) ?? [];
pair[1].send(JSON.stringify({ type: 'init', messages }));
return new Response(null, { status: 101, webSocket: pair[0] });
}
if (req.method === 'POST') {
const msg = await req.json();
const messages: any[] = (await this.state.storage.get('messages')) ?? [];
messages.push(msg);
await this.state.storage.put('messages', messages.slice(-100));
this.broadcast(JSON.stringify(msg));
return Response.json({ ok: true });
}
const messages = (await this.state.storage.get('messages')) ?? [];
return Response.json(messages);
}
// The runtime delivers either a string or an ArrayBuffer. Guard before
// treating the payload as text — JSON.parse on an ArrayBuffer crashes the DO.
async webSocketMessage(ws: WebSocket, msg: string | ArrayBuffer) {
if (typeof msg !== 'string') return;
this.broadcast(msg);
}
broadcast(msg: string) {
for (const ws of this.state.getWebSockets()) {
try { ws.send(msg); } catch { /* dead conn */ }
}
}
}
```
:::tip[Co-locating DO source with a Next.js app]
If you keep your DO file in the same repo as a Next.js / Edge SSR app, exclude the directory from the Next.js `tsconfig.json` — DO source uses Cloudflare globals (`DurableObjectState`, `WebSocketPair`) that aren't in the Next.js type environment, and TypeScript will complain.
```json
{ "exclude": ["node_modules", "durable-objects"] }
```
:::
Deploy with the CLI:
```bash
butterbase do deploy chat-room.ts --name chat-room
```
Or with the MCP tool: `deploy_durable_object`.
## URL pattern
After deploy, every instance is reachable at:
```
https://.butterbase.dev/_do//
```
The same URL accepts both HTTP and WebSocket upgrade. Different instance IDs (`/lobby`, `/general`, `/team-1`) are completely isolated — separate state, separate connections.
:::caution[Subdomain only]
DOs are reachable **only** on your app's subdomain (`.butterbase.dev`). They are **not** mounted under the control API — `https://api.butterbase.ai/v1//_do/...` returns `404 Route not found`. If you're constructing URLs from `VITE_API_URL` or any `api_base` value, swap to the app subdomain before appending `/_do//`.
:::
```js
// Browser
const ws = new WebSocket('wss://my-app.butterbase.dev/_do/chat-room/lobby');
ws.onmessage = (e) => console.log('msg:', e.data);
ws.send(JSON.stringify({ user: 'alice', text: 'hello' }));
```
## Constraints
- **Single file source.** No npm imports. Only `import { ... } from 'cloudflare:workers'` is permitted.
- **One class per file.** The class must be `export`-ed and the filename serves as a default URL name (you can override with `--name`).
- **5 DO classes per app maximum** for v1.
- **Bundle (sum of all DO classes for an app) max 10 MB compressed.**
- **Storage: built-in.** Use `state.storage` (Cloudflare's transactional KV). Do not try to use Postgres for per-DO state — that defeats the point of co-location.
- **No service bindings yet.** Functions and Edge SSR Workers must reach DOs over HTTP, not via env binding. (Service bindings are a future enhancement.)
## Access modes
Each DO declares an access mode at deploy time:
- `public` — anyone can call.
- `authenticated` (default) — requires a valid end-user JWT (`Authorization: Bearer ...`).
- `service_key` — requires a Butterbase service key (`Authorization: Bearer bb_sk_...`).
:::caution
**v1 limitation:** The DO worker only checks the *shape* of the Authorization header (e.g. that it starts with `Bearer bb_sk_`). It does NOT verify that the key is valid, unrevoked, or belongs to your app. For now, the dispatcher in front of WfP terminates traffic from the public internet but does not perform fine-grained auth on `/_do/*` paths.
If you need strong authentication, validate the bearer token inside your DO's `fetch` handler. Two options:
- **Round-trip:** call `GET https://api.butterbase.ai/auth//me` with `Authorization: Bearer `. A 200 response confirms the token is valid and returns the user.
- **Offline crypto verify:** fetch the per-app JWKS from `https://api.butterbase.ai/auth//.well-known/jwks.json` (cached 5 min) and verify the JWT signature locally with the Web Crypto API.
Real authentication enforcement at the dispatcher is on the v2 roadmap.
:::
:::caution[WebSocket auth gotcha]
**Browser WebSockets cannot use `access_mode: 'authenticated'`.** Browsers can't set custom headers on a `WebSocket` upgrade, and the `_do//` dispatcher reads auth **only** from the `Authorization` header. `?token=…` in the URL and `Sec-WebSocket-Protocol` are *silently ignored* by the dispatcher — you'll see a 401 with no clue why, and the upgrade never reaches your `fetch` handler.
> This differs from the platform's `/realtime` WebSocket route, which *does* accept `?token=`. DOs do not — the dispatcher in front of WfP is a thinner shim.
**Pattern for browser-facing WebSocket DOs:** set `access_mode: 'public'` and validate the token yourself inside `fetch()`, reading it from `?token=` or `Sec-WebSocket-Protocol` (both are visible to your handler once the dispatcher lets the request through):
```ts
async fetch(req: Request): Promise {
if (req.headers.get('Upgrade') === 'websocket') {
const token = new URL(req.url).searchParams.get('token');
if (!token || !(await verifyToken(token, this.env))) {
return new Response('unauthorized', { status: 401 });
}
const pair = new WebSocketPair();
this.state.acceptWebSocket(pair[1]);
return new Response(null, { status: 101, webSocket: pair[0] });
}
// ... non-WS branches can still require Authorization header
}
```
`verifyToken` should either call `GET https://api.butterbase.ai/auth//me` with `Authorization: Bearer `, or verify the JWT signature offline against the per-app JWKS (see the v1 limitation note above). Server-to-server callers (Functions, your own backend) can keep using `access_mode: 'authenticated'` or `'service_key'` and pass `Authorization` normally — the gotcha only affects browser WS.
:::
## Environment variables
DOs can read app-level config from `env.KEY` (alongside the DO namespace bindings). Manage them with the CLI:
```bash
butterbase do env set APP_ID app_abc123
butterbase do env set API_BASE_URL https://api.example.com
butterbase do env list
butterbase do env unset OLD_KEY
```
- Keys must match `^[A-Z_][A-Z0-9_]*$` (UPPER_SNAKE).
- Setting or removing a value triggers an automatic redeploy of the DO Worker if any classes are active, so the change is live immediately.
- Values are write-only via the API: `list` returns keys only, never plaintext.
- Env values are visible to **every** DO class deployed for the app — they share one Worker script.
- A key cannot collide with a DO class binding (the UPPER_SNAKE form of a class URL name, e.g. `chat-room` → `CHAT_ROOM`). The deploy will fail with a clear error if it does.
```ts
export class ChatRoom {
constructor(public state: DurableObjectState, public env: { APP_ID: string; API_BASE_URL: string }) {}
async authorize(token: string) {
const res = await fetch(`${this.env.API_BASE_URL}/auth/${this.env.APP_ID}/me`, {
headers: { Authorization: `Bearer ${token}` },
});
return res.ok;
}
}
```
## Lifecycle
- **Add or update a class:** `butterbase do deploy file.ts --name X` — re-bundles all the app's DOs and redeploys the WfP script. Existing in-memory instances are evicted and reload with the new code on the next request.
- **Delete a class:** `butterbase do delete X` — Cloudflare immediately deletes all instances and storage for that class. **This cannot be undone.**
- **Delete the app:** all DO classes and instances are torn down with the app.
- **Class renaming** is not yet supported — register the new name, copy data over, delete the old.
## Server-to-server calls into Durable Objects
Server code (functions and other DOs in the same app) can invoke a DO
directly through platform-managed routing — no bearer to plumb, no public
URL to construct.
### From a function
// Inside a function
export default async (req, ctx) => {
const res = await ctx.invokeDO('support-ticket-do', 'ticket-42', {
cmd: 'handleFollowup',
note: 'customer replied',
});
return new Response(await res.text());
};
`ctx.invokeDO(className, instanceKey, body?, opts?)`:
- `className` — the DO class's registered name (e.g. `'support-ticket-do'`)
- `instanceKey` — the instance identifier (same string used with `idFromName`)
- `body` — request body, JSON-stringified for you
- Returns a standard `Response`
### From another DO
DO code opts into ctx via a helper. The bundler prepends `butterbase` to every DO bundle; user code calls `butterbase.ctx(req, env, state)` at the top of `fetch`:
export class SupportTicketDo {
constructor(state, env) { this.state = state; this.env = env; }
async fetch(req) {
const ctx = butterbase.ctx(req, this.env, this.state);
// Call another DO in the same app
const audit = await ctx.invokeDO('audit-log-do', 'app_events', { evt: 'closed' });
// Call a function in the same app
const notif = await ctx.invoke('send-slack', { text: 'ticket closed' });
// App-level env (platform BUTTERBASE_* + app_env_vars — scrubbed of platform-only keys)
const stripeKey = ctx.env.STRIPE_SECRET;
return new Response('ok');
}
}
Old DO code that doesn't call `butterbase.ctx(...)` continues to work unchanged.
### What's NOT in `ctx.env`
`ctx.env` deliberately hides platform-only keys that user code should never
read directly:
- `DO_INVOKER_URL` / `DO_INVOKER_TOKEN` — the shim's bearer. Use
`ctx.invokeDO(...)` instead of trying to reach it yourself.
- `BUTTERBASE_INTERNAL_FN_KEY` — the fn-invocation bearer. Use `ctx.invoke(...)`
instead of minting your own Authorization header.
Everything else (all `BUTTERBASE_*` platform values, your `app_env_vars`, your
per-DO env vars) remains visible via `ctx.env` exactly as documented for
functions. If you want the underlying `this.env` directly (e.g. to log the
raw key set for a bug report), that's still available inside the class body
untouched — the scrub only applies to the object returned by
`butterbase.ctx(...)`.
### Who called me?
Requests arriving via server-to-server routing carry:
- `ctx.request.caller` — `'fn:widget-ingest'` or `'do:support-ticket-do:ticket-42'`
- `ctx.user?.id` — the impersonated user id, if the call chain carried one
- `ctx.request.loopDepth` — how many hops deep this call chain is (max 4)
The public HTTP path is unchanged — browsers and external services still
hit `{subdomain}.butterbase.dev/_do/…` and are subject to your DO's
`access_mode` and visitor-token checks. `ctx.request.caller` is `null` on
that path.
## Usage and billing
Cloudflare reports per-script metrics (request count, CPU duration). A 15-minute cron pulls these into Butterbase's usage meters:
- `do_requests` — total HTTP + WebSocket invocations
- `do_cpu_ms` — CPU time in milliseconds
Storage GB·s: not yet implemented (v2).
In v1, these meters are recorded but not enforced. Inspect with `butterbase do usage ` or the `get_do_usage` MCP tool. Note that the v1 reporter returns app-wide DO totals across all classes — per-class breakdown is on the v2 roadmap.
## When NOT to use a DO
- **Stateless API endpoint:** use a [Function](/core-concepts/functions/).
- **Static frontend:** use [Frontend Deployment](/core-concepts/frontend-deployment/).
- **Server-rendered Next.js:** use [Edge SSR](/core-concepts/edge-ssr-deployment/).
- **Database-style queries across keys:** use Postgres + the [Auto-API](/core-concepts/database/).
- **Real-time fan-out from DB changes:** use [Postgres Realtime](/core-concepts/realtime/).
## Troubleshooting
**"Source must export exactly one class"** — Your file must `export class X { ... }`. No interfaces, no functions, no extra exports.
**"Import 'X' is not allowed"** — Only `cloudflare:*` imports are permitted. v1 has no npm bundling.
**"Too many DO classes for one app"** — Hard cap of 5 in v1. Delete unused ones to make room.
**WebSocket connection drops immediately** — Check the access mode. Authenticated mode rejects upgrade requests without a valid bearer token.
**Storage limit** — Cloudflare DO storage is ~unlimited per instance, but each key/value is capped at 128 KB. For larger blobs, use [Storage](/core-concepts/storage/).
---
## Core Concepts / Edge SSR Deployment
Deploy server-side rendered Next.js and Remix applications directly from Butterbase. Use `@cloudflare/next-on-pages` to compile your app locally, zip the output, and deploy to Cloudflare Workers for fast edge execution.
:::tip[Skip local builds]
On Windows or want to avoid local toolchain setup? Use [Server-Side Build](/core-concepts/server-side-build/) — Butterbase runs `npm install` and `next-on-pages` for you.
:::
## What is Edge SSR?
Edge SSR (Server-Side Rendering) is a deployment model for server-centric frameworks running on Cloudflare Workers through Butterbase's WfP backend. Unlike static frontend deployment, Edge SSR allows your Next.js app to use server actions, route handlers, dynamic rendering, and React Server Components — without a traditional Node.js server.
**Key difference from static deployment:**
- **Static Frontend Deployment:** Your Vite SPA or statically-exported Next.js app is served as fixed HTML/CSS/JS files via Cloudflare Pages.
- **Edge SSR Deployment:** Your Next.js app's server logic runs on Cloudflare Workers, dynamically rendering pages and handling server actions at request time.
## When to use Edge SSR vs Static
| Use Case | Deployment | Notes |
|----------|-----------|-------|
| React SPA (Vite) | Static | Use [Frontend Deployment](/core-concepts/frontend-deployment) |
| Next.js with `output: 'export'` | Static | Fully static; no server needed |
| Next.js with App Router (RSCs, Server Components) | **Edge SSR** | Requires `@cloudflare/next-on-pages` build |
| Next.js with server actions | **Edge SSR** | Can't run on static hosting |
| Next.js with route handlers (`/api/...`) | **Edge SSR** | Need server runtime |
| Remix with server logic | **Edge SSR** | Supported; see frameworks table |
| Vite / Create React App | Static | Client-side rendering only |
## Prerequisites
You **must** compile your Next.js app locally using `@cloudflare/next-on-pages` before deploying. This tool converts your Next.js app into a Workers-compatible format.
1. Install the tool globally or as a dev dependency:
```bash
npm install -D @cloudflare/next-on-pages
# or
npx @cloudflare/next-on-pages
```
2. Run the build in your Next.js project root:
```bash
npx next build
npx @cloudflare/next-on-pages --build-cache-dir=.next
```
3. Verify the output:
```bash
ls -la .vercel/output/static/
# Should contain _worker.js and other static assets
```
:::caution
If you skip this step or see "_worker.js not found" during deployment, the deployment will fail. **This build step is mandatory — it cannot be skipped.**
:::
## Deployment flow
### Option 1: CLI
```bash
butterbase deploy:edge-ssr
```
This command:
- Detects your `.vercel/output/static/` directory (created by `@cloudflare/next-on-pages`)
- Zips the worker script and assets
- Uploads to your app on Butterbase
- Starts the deployment automatically
Environment variables are set via the dashboard or the `set_frontend_env` MCP tool and take effect on the next deploy. There is no `--env` flag on the CLI.
### Option 2: MCP
**Step 1: Create deployment**
```
create_edge_ssr_deployment({ app_id: "app_abc123", framework: "nextjs-edge" })
```
Response includes a `deployment_id` and `uploadUrl`.
**Step 2: Upload your zip**
```bash
cd .vercel/output/static/
zip -r ../../edge-ssr.zip .
curl -X PUT "{uploadUrl}" \
-H "Content-Type: application/zip" \
--data-binary @edge-ssr.zip
```
**Step 3: Start deployment**
```
start_edge_ssr_deployment({ app_id: "app_abc123", deployment_id: "uuid-1234" })
```
## Supported frameworks
| Framework | Value | Notes |
|-----------|-------|-------|
| Next.js | `nextjs-edge` | **Fully documented and tested in v1** |
| Remix | `remix-edge` | Supported via Cloudflare Workers adapter; see Remix docs |
| Other Workers-compatible | `other-edge` | Must output a `_worker.js` compatible with Cloudflare Workers |
:::note
Only Next.js is documented and officially tested in Butterbase v1. Other frameworks may work if they support Cloudflare Workers output, but we recommend starting with Next.js.
:::
## Runtime constraints (critical)
Edge SSR runs on Cloudflare Workers, not Node.js. Understand these limits before deploying:
### No arbitrary Node.js APIs
- ❌ `fs`, `fs/promises`
- ❌ `child_process`
- ❌ Native `crypto` module (use Web Crypto instead)
- ❌ `net`, `http` (use `fetch`)
### Prisma
Prisma only works via `@prisma/adapter-neon` over HTTP:
```typescript
import { PrismaClient } from '@prisma/client';
import { PrismaNeon } from '@prisma/adapter-neon';
import { Pool } from '@neondatabase/serverless';
const neon = new Pool({ connectionString: process.env.DATABASE_URL });
const adapter = new PrismaNeon(neon);
const prisma = new PrismaClient({ adapter });
export const POST = async (req: Request) => {
const user = await prisma.user.create({ data: { ... } });
return Response.json(user);
};
```
The native Prisma client (binary driver) does **not** work on Cloudflare Workers.
### Timeouts and CPU
- Maximum 30 seconds per request
- 30 seconds of CPU time per Worker invocation (varies by plan)
- Streaming SSR optimization is automatic; no special setup required
### Dependencies
Check that your npm packages are Deno/Workers-compatible. Packages requiring Node.js APIs will fail at runtime. When in doubt, test locally:
```bash
npx @cloudflare/next-on-pages --build-cache-dir=.next
```
If you see build errors, you have incompatible dependencies.
## Edge runtime requirement
`@cloudflare/next-on-pages` only compiles pages and route handlers that opt into the edge runtime. Add this export at the top of every dynamic page, layout, and route handler:
```ts
// app/some-page/page.tsx, app/api/foo/route.ts, etc.
export const runtime = 'edge';
```
Without it, the build fails with `BUILD_NONZERO_EXIT` and a list of "incompatible" pages. The one exception is files marked `'use server'` (Server Actions) — see the pitfall below.
## Server Actions pitfalls
Server Actions have several Next.js-imposed rules that bite specifically when you deploy. Each of these fails silently or with a confusing error in production:
### `allowedOrigins` must include your Butterbase subdomain
Next.js wraps Server Actions in a CSRF check. By default it accepts only the development origin — calls from your deployed `*.butterbase.dev` (or custom) domain are rejected with no clear message. Add the deployed origin to `next.config.js`:
```js
/** @type {import('next').NextConfig} */
module.exports = {
experimental: {
serverActions: {
allowedOrigins: ['my-app.butterbase.dev', 'app.example.com'],
},
},
};
```
If your app suddenly stops working after deploy and Server Actions return blank or 403-ish errors, check this first.
### Don't put `export const runtime = 'edge'` in a `'use server'` file
Files marked `'use server'` are only allowed to export async functions. Adding the `runtime` constant breaks the build with a confusing message. Server Actions inherit the runtime from the page that imports them, so just remove the export:
```ts
// app/actions.ts
'use server';
// ❌ export const runtime = 'edge'; // breaks the build
export async function createPost(formData: FormData) { ... }
```
### Re-throw `NEXT_REDIRECT` inside client `try/catch`
`redirect()` works by throwing a sentinel error with `digest` starting with `NEXT_REDIRECT`. If a client component wraps the action in `try/catch`, the redirect is swallowed and navigation never happens. Always re-throw it:
```ts
try {
await myServerAction(formData);
} catch (err: any) {
if (err?.digest?.startsWith('NEXT_REDIRECT')) throw err;
setError(err.message);
}
```
## Size limits
- **Worker script:** 5 MB compressed (separate limit)
- **Total deployment:** 100 MB compressed (script + static assets)
If your deployment exceeds 5 MB:
1. Enable code splitting in `next.config.js`
2. Move heavy dependencies into edge functions (as separate Butterbase Serverless Functions)
3. Use tree-shaking optimizations in your build
Example `next.config.js`:
```javascript
/** @type {import('next').NextConfig} */
const nextConfig = {
webpack: (config) => {
config.optimization.splitChunks = {
chunks: 'all',
minSize: 20000,
};
return config;
},
};
module.exports = nextConfig;
```
## Environment variables
Set environment variables via the dashboard or the `set_frontend_env` MCP tool — they take effect on the next deploy. There is no `--env` flag on the CLI.
Alternatively, use the REST API directly:
```json
PUT /v1/{app_id}/edge-ssr/env
{
"DATABASE_URL": "postgresql://...",
"NEXT_PUBLIC_API_BASE": "https://api.butterbase.ai"
}
```
**Important:** Environment variables are baked into the Worker script at deploy time. Changing variables requires a new deployment.
Framework-specific prefixes (same as static):
- **Next.js:** `NEXT_PUBLIC_` (visible in browser), `NEXT_` (server-only)
- **Remix:** Depends on your setup; check your `.env.server` file
## Replacement semantics
Only **one frontend per app** is active at any time:
- Deploying an Edge SSR app **replaces** any active static deployment
- Deploying a static frontend **replaces** any active Edge SSR deployment
- Older deployments are kept for rollback but are not served
To roll back to a previous deployment, redeploy the older version.
## Troubleshooting
### "_worker.js not found" on upload
**Cause:** You skipped the `@cloudflare/next-on-pages` build step.
**Fix:** Run the build in your Next.js root:
```bash
npx next build
npx @cloudflare/next-on-pages --build-cache-dir=.next
ls .vercel/output/static/_worker.js
```
Then re-upload the `.vercel/output/static/` folder.
### WORKER_TOO_LARGE
**Cause:** Your compiled Worker script exceeds 5 MB compressed.
**Fix:**
1. Enable code splitting in `next.config.js` (see Size Limits section)
2. Audit dependencies — remove or replace heavy packages
3. Move compute-heavy logic into Butterbase Serverless Functions, called from your Edge SSR app via API
### WRONG_BACKEND
**Cause:** Your app is not on the `wfp` backend (required for Edge SSR).
**Fix:** New apps default to `wfp`. For older apps, contact support or create a new app.
### Prisma/Neon connection errors
**Cause:** Using the native Prisma client instead of `@prisma/adapter-neon`.
**Fix:** Update your Prisma setup to use the Neon adapter (see Runtime Constraints section).
### Package import errors at runtime
**Cause:** A dependency uses Node.js APIs incompatible with Cloudflare Workers.
**Fix:** Test locally with `@cloudflare/next-on-pages`, check the build output for warnings, and replace or remove the incompatible package.
## Monitoring and logs
Once deployed, check status and logs via the dashboard or the `list_edge_ssr_deployments` MCP tool. Live request logs appear in the Butterbase dashboard under your app's Frontend section.
---
## Core Concepts / AI Integration
Butterbase includes a built-in AI model gateway that lets your app call large language models through an OpenAI-compatible API.
## Two ways to call the gateway
- **App-scoped** (`/v1/{app_id}/...`) — tied to an app you've created in Butterbase. Use this when AI calls happen on behalf of an app and you want them logged against it. The app's AI configuration (default model, allowed models) applies.
- **App-less** (`/v1/...`) — for using Butterbase as a generic model gateway. Authenticate with a platform JWT or a personal API key that has the `ai:gateway` scope. Useful for scripts, CLIs, the OpenAI SDK, or any client that doesn't need an app on the platform.
The request and response shapes are identical between the two — only the path differs. See the [AI API reference](/api-reference/ai-api/) for the gateway endpoints, error contract, and how to mint a personal API key.
## How it works
Your app sends chat completion or embedding requests to Butterbase. Usage cost is tracked automatically and counted against your plan's AI credits allowance.
## Chat completions
```json
POST /v1/{app_id}/chat/completions
Authorization: Bearer {token}
{
"model": "anthropic/claude-sonnet-4.6",
"messages": [
{ "role": "system", "content": "You are a helpful assistant." },
{ "role": "user", "content": "What is Butterbase?" }
],
"max_tokens": 500,
"temperature": 0.7
}
```
**Streaming:** Set `"stream": true` to receive server-sent events.
## Multimodal content
Message `content` can be a plain string or an array of typed content parts. Mix text, images, and video in a single message.
### Images
Pass a publicly accessible URL (or a `data:` URI for base64-encoded images):
```json
POST /v1/{app_id}/chat/completions
Authorization: Bearer {token}
{
"model": "anthropic/claude-sonnet-4.6",
"messages": [
{
"role": "user",
"content": [
{ "type": "text", "text": "What's in this image?" },
{ "type": "image_url", "image_url": { "url": "https://example.com/photo.jpg" } }
]
}
]
}
```
The optional `detail` field controls resolution when the model supports it (`"low"`, `"high"`, or `"auto"`):
```json
{ "type": "image_url", "image_url": { "url": "https://example.com/diagram.png", "detail": "high" } }
```
### Video
```json
{
"role": "user",
"content": [
{ "type": "text", "text": "Summarise this clip." },
{ "type": "video_url", "video_url": { "url": "https://example.com/clip.mp4" } }
]
}
```
:::note
Multimodal support depends on the model. Vision models such as `anthropic/claude-sonnet-4.6`, `anthropic/claude-opus-4.6`, and `openai/gpt-4o` accept images. Not all models accept video. Passing unsupported content parts to a text-only model returns a provider error.
:::
### Multiple images
```json
{
"role": "user",
"content": [
{ "type": "text", "text": "Compare these two screenshots." },
{ "type": "image_url", "image_url": { "url": "https://example.com/before.png" } },
{ "type": "image_url", "image_url": { "url": "https://example.com/after.png" } }
]
}
```
### Using Butterbase Storage URLs
If your images are stored in Butterbase Storage, resolve a presigned download URL first:
```typescript
const { data } = await butterbase.storage.getDownloadUrl(objectId);
const response = await fetch(`${apiUrl}/v1/${appId}/chat/completions`, {
method: 'POST',
headers: { Authorization: `Bearer ${token}`, 'Content-Type': 'application/json' },
body: JSON.stringify({
model: 'anthropic/claude-sonnet-4.6',
messages: [{
role: 'user',
content: [
{ type: 'text', text: 'Describe this image.' },
{ type: 'image_url', image_url: { url: data.url } },
],
}],
}),
});
```
## Embeddings
Generate vector embeddings for semantic search, clustering, and other ML tasks:
```json
POST /v1/{app_id}/embeddings
Authorization: Bearer {token}
{
"model": "openai/text-embedding-3-small",
"input": "What is Butterbase?",
"encoding_format": "float"
}
```
**Batch input:** Pass an array of strings:
```json
{
"model": "openai/text-embedding-3-small",
"input": ["first text", "second text", "third text"]
}
```
### Available embedding models
| Model | ID | Dimensions |
|-------|-----|------------|
| Text Embedding 3 Small | `openai/text-embedding-3-small` | 1536 |
| Text Embedding 3 Large | `openai/text-embedding-3-large` | 3072 |
| Text Embedding Ada 002 | `openai/text-embedding-ada-002` | 1536 |
## Video generation
Video models work differently from chat: generation is **asynchronous** and can take 30 seconds to several minutes. You submit a job, poll until it's ready, and then download the rendered MP4. See [Video generation](/api-reference/ai-api/#video-generation) in the API reference for the full flow.
Video is billed per call (not per token) — the actual cost appears as `charged_credits_usd` in the job's final poll response.
## Available models
Butterbase supports a wide range of frontier and open-source models, including:
| Model | ID |
|-------|-----|
| Claude Sonnet 4.6 | `anthropic/claude-sonnet-4.6` |
| Claude Opus 4.6 | `anthropic/claude-opus-4.6` |
| Claude Haiku 4.5 | `anthropic/claude-haiku-4.5` |
| Claude 3.7 Sonnet | `anthropic/claude-3.7-sonnet` |
| Claude 3.7 Sonnet (thinking) | `anthropic/claude-3.7-sonnet:thinking` |
| GPT-4o | `openai/gpt-4o` |
| GPT-4o Mini | `openai/gpt-4o-mini` |
| Llama 3.3 70B | `meta-llama/llama-3.3-70b-instruct` |
| DeepSeek R1 | `deepseek/deepseek-r1` |
| Gemini 2.5 Flash | `google/gemini-2.5-flash` |
Browse the complete catalog (with current pricing) on the **AI models** page in the dashboard, or fetch it programmatically — no auth required — via [`GET /v1/public/models`](/api-reference/ai-api/#public-model-catalog).
## AI configuration
Configure AI settings per app:
```json
PUT /v1/{app_id}/ai/config
{
"defaultModel": "anthropic/claude-sonnet-4.6",
"maxTokensPerRequest": 4096,
"allowedModels": ["anthropic/claude-sonnet-4.6", "anthropic/claude-haiku-4.5"]
}
```
| Setting | Description |
|---------|-------------|
| `defaultModel` | Model used when none is specified |
| `maxTokensPerRequest` | Maximum tokens per request (1–100,000) |
| `allowedModels` | Restrict which models can be used |
## Usage tracking
```
GET /v1/{app_id}/ai/usage?startDate=2026-01-01&endDate=2026-01-31
```
Returns total tokens, cost, and breakdown by model.
## Using AI in serverless functions
The runtime auto-injects `BUTTERBASE_APP_ID` and `BUTTERBASE_API_URL` — you only need to supply your API key via `envVars`:
```typescript
export default async function handler(req: Request, ctx: any): Promise {
const { BUTTERBASE_APP_ID, BUTTERBASE_API_URL, BUTTERBASE_API_KEY } = ctx.env;
const aiResponse = await fetch(`${BUTTERBASE_API_URL}/v1/${BUTTERBASE_APP_ID}/chat/completions`, {
method: 'POST',
headers: {
'Content-Type': 'application/json',
'Authorization': `Bearer ${BUTTERBASE_API_KEY}`
},
body: JSON.stringify({
model: 'anthropic/claude-haiku-4.5',
messages: [{ role: 'user', content: 'Summarize this text: ...' }],
max_tokens: 200
})
});
const result = await aiResponse.json();
return new Response(JSON.stringify(result), {
headers: { 'Content-Type': 'application/json' }
});
}
```
## AI credits
AI usage (chat completions and embeddings) is billed against your unified credit balance. See [Plans & Usage](/core-concepts/plans-and-usage/) for plan allowances, topups, spending caps, and how credits are consumed.
---
## Core Concepts / AI Meetings
Butterbase includes a meeting bot primitive at `ctx.ai.meetings` (or `bb.ai.meetings` from the SDK). You pass a meeting URL, the platform spawns a bot that joins the call, and you receive recordings + transcripts back when the call ends. Usage is billed against your AI credits allowance just like chat or embeddings.
## When to use it
- Meeting notetakers ("our AI joined the call, here's the recap")
- Sales call transcript ingestion + follow-up generation
- Internal recording of all customer calls
- Any product surface that needs the audio, video, or transcript of a third-party call
## How it works
1. Your code calls `POST /v1/{app_id}/ai/meetings` with the meeting URL. The platform spawns a bot, returns its `id` and `status` immediately, and reserves a small credit lease against your balance.
2. The bot joins the call. Its lifecycle (`joining → waiting_room → in_call → recording → ended → done`) is exposed over webhooks; you can also poll `GET /v1/{app_id}/ai/meetings/{id}`.
3. When the call ends, recording and transcript artifacts become available. The exact charge is computed from real measured duration and settles against your reserved lease — unused portion refunded automatically.
4. Your registered webhook endpoint receives a forwarded event when each artifact is ready. The webhook payload only carries the recording / transcript **id**; to get the download URL, follow up with a `GET` on the bot — `recordingUrl` and `transcriptUrl` are populated there.
## Controlling when the bot gives up
By default, the bot leans on the provider's built-in auto-leave defaults — it'll sit in a waiting room or an empty room for a while before giving up. Pass `automaticLeave` on spawn to override any of those timers per bot. Each sub-field is optional (omitted ones inherit the provider default) and takes a positive number of seconds.
| Sub-field | Triggers when… |
|---|---|
| `waitingRoomTimeoutSec` | The bot has been stuck in the waiting room (host hasn't admitted it) for this many seconds. |
| `noOneJoinedTimeoutSec` | The bot is in the call but no participants ever joined within this many seconds. |
| `everyoneLeftTimeoutSec` | All participants have left and this many seconds pass with the room empty. |
| `inCallNotRecordingTimeoutSec` | The bot is in the call but not recording (e.g. recording consent denied) for this many seconds. |
**Example — leave if not admitted within 15 minutes:**
```ts
await bb.ai.meetings.start({
meetingUrl,
automaticLeave: { waitingRoomTimeoutSec: 900 },
});
```
See the [AI Meetings API reference](/api-reference/ai-meetings-api/#auto-leave-timers) for the full HTTP shape.
## Configuring webhooks
For each app, register one forward URL plus a per-app HMAC secret. Butterbase signs every forwarded event with your app's own secret — verification on your side is the standard HMAC-SHA256 pattern, identical to Stripe / GitHub / Recall.ai webhooks.
```bash
curl -X PUT https://api.butterbase.ai/v1/{app_id}/ai/meetings/webhook \
-H "authorization: Bearer bb_sk_..." \
-H "content-type: application/json" \
-d '{
"forward_url": "https://your-app.example.com/recall/events",
"rotate_secret": true
}'
```
Response (only `secret` is sensitive — store it before navigating away, you can't read it again):
```json
{
"ok": true,
"app_id": "app_abc123",
"forward_url": "https://your-app.example.com/recall/events",
"secret": "wsec_..."
}
```
The default event subscriptions:
- `bot.in_call_recording` — bot joined, recording started
- `bot.done` — bot left, call finished cleanly
- `bot.fatal` — bot terminated with an error
- `recording.done` — recording artifact ready
- `transcript.done` — transcript artifact ready
- `transcript.failed` — transcription failed
## Verifying a forwarded event
```ts
// node or deno function
const expected = 'v1,' + crypto
.createHmac('sha256', Buffer.from(ctx.env.MEETINGS_WEBHOOK_SECRET, 'utf8'))
.update(rawBody)
.digest('base64');
if (!timingSafeEqual(expected, req.headers.get('x-bb-signature'))) {
return new Response('invalid signature', { status: 401 });
}
```
The secret is the same `wsec_...` Butterbase returned to you at `PUT` time. The platform stores it AES-256-GCM-encrypted; only your app and the platform ever see the plaintext.
## Pricing
Recording: $0.50 / hour. Transcription: $0.15 / hour. Both charged against the AI credits pool documented under [AI Integration](/core-concepts/ai-integration/). Up-front the platform reserves a small lease (a few cents); the unused portion is refunded when the call settles.
Use `GET /v1/{app_id}/ai/meetings/_estimate?durationMinutes=30` to predict cost for any duration.
## Complete worked example
A minimal app that records every meeting URL it receives, stores tracking metadata, and back-fills recording / transcript URLs from webhooks.
### Schema
```json
{
"tables": {
"meetings": {
"columns": {
"id": { "type": "uuid", "primaryKey": true, "default": "gen_random_uuid()" },
"bot_id": { "type": "text", "nullable": false, "unique": true },
"meeting_url": { "type": "text", "nullable": false },
"status": { "type": "text", "nullable": false, "default": "'pending'" },
"last_event": { "type": "text" },
"events_count": { "type": "integer", "nullable": false, "default": "0" },
"recording_url": { "type": "text" },
"transcript_url": { "type": "text" },
"created_at": { "type": "timestamptz", "nullable": false, "default": "now()" }
},
"indexes": { "meetings_bot_id_idx": { "columns": ["bot_id"], "unique": true } }
}
}
}
```
### Spawn function (`POST /fn/spawn-bot`)
```ts
export default async function handler(req: Request, ctx: any): Promise {
const { meetingUrl } = await req.json();
const res = await fetch(
`${ctx.env.BUTTERBASE_API_URL}/v1/${ctx.env.BUTTERBASE_APP_ID}/ai/meetings`,
{
method: 'POST',
headers: {
'content-type': 'application/json',
authorization: `Bearer ${ctx.env.BUTTERBASE_API_KEY}`,
},
body: JSON.stringify({ meetingUrl, transcript: true, recording: 'mp4' }),
},
);
const bot = await res.json();
if (!res.ok) return new Response(JSON.stringify(bot), { status: 502 });
await ctx.db.query(
'INSERT INTO meetings (bot_id, meeting_url, status, last_event) VALUES ($1, $2, $3, $4)',
[bot.id, meetingUrl, bot.status ?? 'joining', 'spawn'],
);
return new Response(JSON.stringify({ bot_id: bot.id, status: bot.status }), {
headers: { 'content-type': 'application/json' },
});
}
```
Deploy with `envVars: { BUTTERBASE_API_KEY: 'bb_sk_...' }`.
### Webhook function (`POST /fn/meetings-webhook`)
```ts
function timingSafeEqual(a: string, b: string) {
if (a.length !== b.length) return false;
let r = 0;
for (let i = 0; i < a.length; i++) r |= a.charCodeAt(i) ^ b.charCodeAt(i);
return r === 0;
}
async function hmacBase64(secret: string, body: string) {
const key = await crypto.subtle.importKey(
'raw', new TextEncoder().encode(secret),
{ name: 'HMAC', hash: 'SHA-256' }, false, ['sign'],
);
const mac = await crypto.subtle.sign('HMAC', key, new TextEncoder().encode(body));
return btoa(String.fromCharCode(...new Uint8Array(mac)));
}
export default async function handler(req: Request, ctx: any): Promise {
const rawBody = await req.text();
const sig = req.headers.get('x-bb-signature') ?? '';
const event = req.headers.get('x-bb-event') ?? '';
// wsec_... from PUT, stored in envVars.MEETINGS_WEBHOOK_SECRET
const expected = `v1,${await hmacBase64(ctx.env.MEETINGS_WEBHOOK_SECRET, rawBody)}`;
if (!timingSafeEqual(expected, sig)) return new Response('invalid signature', { status: 401 });
const payload = JSON.parse(rawBody);
const botId = payload?.data?.bot?.id;
if (!botId) return new Response('ok');
let nextStatus: string | null = null;
if (event === 'bot.in_call_recording') nextStatus = 'recording';
else if (event === 'bot.done') nextStatus = 'done';
else if (event === 'bot.fatal') nextStatus = 'fatal';
let recordingUrl: string | null = null;
let transcriptUrl: string | null = null;
if (event === 'recording.done' || event === 'transcript.done' || event === 'bot.done') {
const res = await fetch(
`${ctx.env.BUTTERBASE_API_URL}/v1/${ctx.env.BUTTERBASE_APP_ID}/ai/meetings/${botId}`,
{ headers: { authorization: `Bearer ${ctx.env.BUTTERBASE_API_KEY}` } },
);
if (res.ok) {
const bot = await res.json();
recordingUrl = bot.recordingUrl ?? null;
transcriptUrl = bot.transcriptUrl ?? null;
}
}
await ctx.db.query(
`UPDATE meetings
SET status = COALESCE($2, status),
last_event = $3,
recording_url = COALESCE($4, recording_url),
transcript_url = COALESCE($5, transcript_url),
events_count = events_count + 1
WHERE bot_id = $1`,
[botId, nextStatus, event, recordingUrl, transcriptUrl],
);
return new Response(JSON.stringify({ ok: true }));
}
```
Deploy with `trigger: { type: 'http', config: { method: 'POST', path: '/meetings-webhook', auth: 'none' } }` and `envVars: { MEETINGS_WEBHOOK_SECRET: 'wsec_...', BUTTERBASE_API_KEY: 'bb_sk_...' }`. `auth: 'none'` is correct here — the HMAC inside is what authenticates the caller.
### Drive it
```bash
curl -X POST https://{app_id}.api.butterbase.ai/fn/spawn-bot \
-H "content-type: application/json" \
-d '{ "meetingUrl": "https://zoom.us/j/12345..." }'
# → { "bot_id": "...", "status": "joining" }
```
That's it. The bot joins the meeting, events arrive on `meetings-webhook` as the lifecycle advances, and the row is kept current with the latest status plus the recording / transcript URLs.
## Reference
- [AI Meetings API](/api-reference/ai-meetings-api/) — every endpoint, request shape, and response shape
- [TypeScript SDK](/sdks-and-tools/typescript-sdk/) — `bb.ai.meetings.start / get / list / stop / estimateCost`
- [CLI](/sdks-and-tools/cli/) — `bb ai meetings start | get | list | stop | estimate | usage | webhook`
---
## Core Concepts / RAG (Native)
Butterbase includes a native RAG (Retrieval-Augmented Generation) primitive that lets your app ingest documents and search them semantically. The platform handles chunking, embedding with `text-embedding-3-small`, and vector storage via pgvector — two API calls: ingest and query.
## How it works
1. **Ingest** — Upload a file or pass raw text. The platform parses the content, splits it into overlapping chunks, and generates vector embeddings.
2. **Store** — Chunks and embeddings are stored in pgvector (HNSW index for fast cosine similarity search) inside your app's database.
3. **Query** — Send a natural language question. The platform embeds it, finds the most similar chunks, and returns them ranked by similarity. Optionally synthesizes an AI answer.
Processing is asynchronous. Ingestion returns immediately with a document ID; use the status endpoint to poll until `ready`.
## Collections
A **collection** is a namespace for related documents (e.g. `support-docs`, `product-manual`). All ingested documents and their chunks belong to a collection. Collections are scoped to your app.
**Name rules:** lowercase alphanumeric, hyphens, and underscores only (e.g. `support-docs`, `product_manual`).
### Access modes
| Mode | Behavior |
|------|----------|
| `private` (default) | Each user can only query their own documents. RLS policies are auto-created. |
| `shared` | All authenticated users can query all documents in the collection. |
| `custom` | No auto-policies are created — define your own RLS rules. |
### Creating a collection
```json
POST /v1/{app_id}/rag/collections
Authorization: Bearer bb_sk_...
{
"name": "support-docs",
"accessMode": "shared",
"description": "Product support documentation"
}
```
Response:
```json
{
"id": "uuid",
"name": "support-docs",
"description": "Product support documentation",
"accessMode": "shared",
"chunkSize": 512,
"chunkOverlap": 64,
"createdAt": "2026-04-23T10:00:00Z"
}
```
## Ingesting documents
### From raw text
```json
POST /v1/{app_id}/rag/collections/support-docs/ingest
Authorization: Bearer bb_sk_...
{
"text": "Refunds are accepted within 30 days of purchase...",
"filename": "refund-policy.txt"
}
```
### From a stored file
1. Upload the file using `POST /storage/{app_id}/upload` and save the returned `objectId`.
2. Pass that ID to the ingest endpoint:
```json
POST /v1/{app_id}/rag/collections/support-docs/ingest
Authorization: Bearer bb_sk_...
{
"storage_object_id": "uuid-from-upload"
}
```
### Supported file types
| Type | Extensions |
|------|------------|
| Plain text | `.txt`, `.md` |
| PDF | `.pdf` |
| Word | `.docx` |
| Excel | `.xlsx` |
| PowerPoint | `.pptx` |
| HTML | `.html` |
| CSV | `.csv` |
### Async lifecycle
```
pending → processing → ready
↘ failed
```
The ingest response returns immediately with `status: "pending"`. Poll with `GET /v1/{app_id}/rag/collections/{name}/documents/{id}` until status is `ready` or `failed`.
## Querying
```json
POST /v1/{app_id}/rag/collections/support-docs/query
Authorization: Bearer Bearer bb_sk_...
{
"query": "What is the refund policy?",
"topK": 5,
"threshold": 0.7
}
```
Response:
```json
{
"chunks": [
{
"text": "Refunds are accepted within 30 days of purchase...",
"score": 0.92,
"documentId": "uuid",
"metadata": {}
}
]
}
```
### Query parameters
| Parameter | Type | Default | Description |
|-----------|------|---------|-------------|
| `query` | string | required | Natural language question |
| `topK` | number | 5 | Number of chunks to return |
| `threshold` | number | — | Minimum similarity score (0–1); chunks below excluded |
| `synthesize` | boolean | false | Generate an AI answer from the retrieved chunks |
| `model` | string | auto | Model to use for synthesis (e.g. `anthropic/claude-haiku-4-5`) |
| `filter` | object | — | Metadata filter to narrow results |
### Synthesized answers
Set `synthesize: true` to get an AI-generated answer in addition to the raw chunks:
```json
{
"query": "What is the refund policy?",
"synthesize": true
}
```
Response includes an `answer` field:
```json
{
"chunks": [...],
"answer": "Refunds are accepted within 30 days of purchase with a valid receipt.",
"model": "anthropic/claude-haiku-4-5"
}
```
## Access control
RAG collections respect the same RLS model as regular tables:
- **`private`** — Auto-created policies restrict each user to their own documents and chunks. The `user_id` stored at ingest time is matched against the request JWT.
- **`shared`** — Auto-created policies allow all authenticated users to read all documents and chunks.
- **`custom`** — No policies are created. You define your own using `CREATE POLICY` via the schema tools.
## SDK usage
```typescript
import { createClient } from '@butterbase/sdk';
const butterbase = createClient({
appId: 'app_abc123',
apiUrl: 'https://api.butterbase.ai',
});
// Create a shared collection
await butterbase.rag.createCollection({
name: 'support-docs',
accessMode: 'shared',
});
// Ingest raw text
const { data: doc } = await butterbase.rag.ingest('support-docs', {
text: 'Refunds are accepted within 30 days of purchase...',
filename: 'refund-policy.txt',
});
// Poll until ready
let status = doc.status;
while (status === 'pending' || status === 'processing') {
await new Promise(r => setTimeout(r, 1000));
const { data } = await butterbase.rag.getDocument('support-docs', doc.documentId);
status = data.status;
}
// Query with synthesis
const { data: result } = await butterbase.rag.query('support-docs', {
query: 'What is the return policy?',
synthesize: true,
});
console.log(result.answer);
```
## AI credits
- Embedding costs during ingestion and querying count against your plan's AI credits allowance.
- Synthesis (when `synthesize: true`) uses an LLM and also counts against AI credits.
- File storage for uploaded documents counts against your storage quota.
- No additional RAG-specific charges.
---
## Core Concepts / Key-Value Store
Butterbase KV gives every app a fast, durable key-value store co-located in the same [region](/core-concepts/regions/) as your database. It is purpose-built for data that is accessed by key, expires naturally, and does not benefit from relational joins — think session tokens, distributed locks, idempotency keys, rate-limit counters, and feature flags.
Keys are automatically scoped to your app. You never need to prefix keys with an app ID or worry about collisions with other apps.
## When to use KV
| Use case | Best fit |
|---|---|
| Sessions, auth tokens, refresh tokens | **KV** |
| Distributed locks, leader election | **KV** — use `setnx` or `cas` |
| Idempotency keys | **KV** — use `setnx` |
| Rate-limit counters, page-view counters | **KV** — use `incr` / `decr` |
| Feature flags, A/B config | **KV** |
| Short-lived cache (computed results, API responses) | **KV** — use `ephemeral: true` |
| Structured user data, relational queries | **Database** |
| Uploaded files, images, documents | **File Storage** |
KV is not designed for: message queues, pub/sub channels, sorted sets, lists, or streaming. Use Realtime or a function-to-function call for those patterns.
## Data model
KV stores values as arbitrary JSON (strings, numbers, objects, arrays) up to a per-plan size limit. Counters are a first-class type — `incr` and `decr` initialize to `0` if the key does not exist and operate atomically.
### Keys
Keys are plain strings. They may contain any characters, though `:` is the conventional namespace separator (e.g., `session:user_abc123`, `lock:checkout:order_99`). You do not need to add any prefix for app isolation — that happens automatically.
### TTL
The default TTL for every new key is **30 days**. You can override this at write time:
| TTL option | Behaviour |
|---|---|
| Omitted | 30-day default |
| `{ ttl: N }` | Expires after `N` seconds |
| `{ ttl: null }` | Never expires |
To update the TTL of an existing key without changing its value, call `expire(key, seconds)` or `expire(key, null)` (pin forever).
### Persistence
Keys are **durable by default** — they survive server restarts and are replicated. For purely cache-tier data that you are comfortable losing on a cold restart, pass `{ ephemeral: true }` at write time. Ephemeral writes are faster but not guaranteed to survive a node restart.
## Quickstart
Inside a [serverless function](/core-concepts/functions/), use `ctx.kv`:
```typescript
export default async function handler(ctx) {
// Store a session token for 1 hour
await ctx.kv.set('session:abc123', { userId: 'u_1', role: 'admin' }, { ttl: 3600 });
// Read it back (returns null if missing or expired)
const session = await ctx.kv.get<{ userId: string; role: string }>('session:abc123');
// Atomic counter — initialises to 0 if missing, then increments
const views = await ctx.kv.incr('counter:page:/home');
// Acquire a lock — only succeeds if key does not exist
const acquired = await ctx.kv.setnx('lock:checkout:order_99', 1, { ttl: 30 });
return { session, views, acquired };
}
```
Make a counter visible to the frontend without granting writes:
```ts
// In a function handler — set up the rule once
await ctx.kv.expose('hits:home', { read: 'public', write: 'deny' });
await ctx.kv.incr('hits:home');
```
```ts
// In the frontend
const res = await fetch(`${api}/v1/${appId}/kv/hits:home`);
const { value } = await res.json();
```
## Access control
By default, **all KV keys are private** — they are only accessible from your own serverless functions using a service key. End-user clients (browser, mobile) cannot read or write KV keys at all unless you explicitly opt in.
Use `ctx.kv.expose(pattern, { read, write })` to open a key pattern to end-users. This is typically called once during app setup or in a migration function.
Per-user keyspaces use `{user.id}` templating — each end user sees only their own keys:
```ts
// Function: allow each signed-in user to read & write their own profile blob
await ctx.kv.expose('profile:{user.id}', { read: 'owner', write: 'owner' });
// User u_42 signs in. From the frontend:
// GET /v1/:app_id/kv/profile:u_42 → 200, value
// GET /v1/:app_id/kv/profile:u_99 → 403 (not their key)
```
### Roles
| Role | Who it applies to |
|---|---|
| `'deny'` | Access blocked (the default for all keys) |
| `'public'` | Anyone, including unauthenticated requests |
| `'authed'` | Any authenticated user |
| `'owner'` | Only the user whose ID is embedded in the key (see `{user.id}` below) |
### Pattern syntax
Patterns use glob-style matching:
| Token | Matches |
|---|---|
| `*` | One path segment (no `:` inside) |
| `**` | Any number of segments, including nested separators |
| `{user.id}` | The authenticated user's ID (substituted at request time) |
| `{user.role}` | The authenticated user's role |
### Examples
**Per-user keyspace** — each user can read and write only their own keys:
```typescript
// Keys like "prefs:user_abc123" are readable/writable only by user_abc123
await ctx.kv.expose('prefs:{user.id}', { read: 'owner', write: 'owner' });
```
**Public read, admin write** — a feature-flag namespace any client can read:
```typescript
// Any authenticated user can read flags; only service keys can write
await ctx.kv.expose('flags:**', { read: 'authed', write: 'deny' });
```
**Global public read** — useful for anonymous counters or config:
```typescript
await ctx.kv.expose('public:**', { read: 'public', write: 'deny' });
```
**Remove a rule** when you no longer need it:
```typescript
await ctx.kv.unexpose('prefs:{user.id}');
```
**Inspect active rules** at any time:
```typescript
const rules = await ctx.kv.listRules();
// [{ pattern: 'prefs:{user.id}', read: 'owner', write: 'owner', order: 0 }, ...]
```
The most-specific pattern wins (longest literal prefix). Adding a rule with the same pattern but different roles returns a `409 KV_EXPOSE_CONFLICT` — call `unexpose` first.
## TTL & persistence
```typescript
// 30-day default
await ctx.kv.set('key', 'value');
// Explicit TTL in seconds
await ctx.kv.setex('key', 'value', 3600); // 1 hour
await ctx.kv.set('key', 'value', { ttl: 3600 }); // same
// Never expires
await ctx.kv.set('key', 'value', { ttl: null });
// Update TTL of an existing key
await ctx.kv.expire('key', 7200); // 2 hours from now
await ctx.kv.expire('key', null); // pin forever
// Read remaining TTL in seconds (null = no expiry, null if key missing)
const remaining = await ctx.kv.ttl('key');
// Touch-on-read: resets TTL to the default each time the key is read
const value = await ctx.kv.get('key', { touch: true });
// Ephemeral write — fast cache tier, not guaranteed durable
await ctx.kv.set('cache:heavy-query', result, { ephemeral: true, ttl: 300 });
```
## Atomic operations
These operations are useful for building correct distributed logic without additional coordination.
| Method | Signature | Use case |
|---|---|---|
| `setnx` | `(key, value, opts?) → boolean` | Acquire a lock or write once. Returns `true` if the key was created, `false` if it already existed. |
| `setex` | `(key, value, ttl, opts?) → void` | Shorthand for `set` with a required TTL. |
| `cas` | `(key, expected, next) → boolean` | Compare-and-swap. Only updates if the current value equals `expected`. Returns `true` if the swap happened. |
| `incr` | `(key, by?) → number` | Increment by `by` (default 1). Initialises key to `0` first if missing. |
| `decr` | `(key, by?) → number` | Decrement by `by` (default 1). Initialises key to `0` first if missing. |
| `exists` | `(key) → boolean` | Check presence without loading the value. |
### Distributed lock pattern
```typescript
// Try to acquire lock (TTL is the lock lease time)
const acquired = await ctx.kv.setnx('lock:job:42', ctx.requestId, { ttl: 30 });
if (!acquired) {
return { status: 'already_running' };
}
try {
// ... do exclusive work ...
} finally {
// Only release if we still own it
await ctx.kv.cas('lock:job:42', ctx.requestId, null);
await ctx.kv.del('lock:job:42');
}
```
### Idempotency key pattern
```typescript
// Prevent duplicate charge on retry
const created = await ctx.kv.setnx(`idem:charge:${requestId}`, true, { ttl: 86400 });
if (!created) {
return { status: 'duplicate' };
}
// proceed with charge
```
## Bulk operations
```typescript
// Read multiple keys in one call
const [session, prefs] = await ctx.kv.mget(['session:abc', 'prefs:abc']);
// Write multiple keys (parallel PUTs; all share the same TTL option)
await ctx.kv.mset(
{ 'flag:dark-mode': true, 'flag:beta-ui': false },
{ ttl: null },
);
```
## Error handling
| Error class | HTTP status | Meaning |
|---|---|---|
| `KvNotFoundError` | — | `get` returns `null`; no exception thrown |
| `KvForbiddenError` | 403 | End-user request blocked by access-control rules |
| `KvCasMismatchError` | 409 | `cas` expected value did not match (caller should retry) |
| `KvValueTooLargeError` | 413 | Value exceeds the per-key size limit |
| `KvRateLimitedError` | 429 | Too many ops/sec — back off and retry |
| `KvStorageFullError` | 507 | App has reached its total storage cap |
| `KvKeysExhaustedError` | 507 | App has reached its key count cap |
A `429` means your app is sending too many requests too quickly — add a short back-off. A `413` means the value is too large — consider storing it in [File Storage](/core-concepts/storage/) instead.
## Limits
Per-app caps apply to operations per second, maximum value size, total key count, and total storage. Exact numbers depend on your plan. See [KV API Reference](/api-reference/kv-api/) for current limits.
## Where next
- REST API reference: [/api-reference/kv-api/](/api-reference/kv-api/)
- CLI: [/sdks-and-tools/cli/](/sdks-and-tools/cli/)
- MCP tool: [manage\_kv](/api-reference/mcp-tools/#manage_kv)
---
## Core Concepts / Realtime
Butterbase provides real-time data change notifications via WebSocket connections. When enabled on a table, any INSERT, UPDATE, or DELETE is broadcast to connected clients.
## Enabling realtime
```
configure_realtime({ app_id: "app_abc123", tables: ["messages", "notifications"] })
```
This installs database triggers that capture changes and broadcast them via pg_notify.
## Connecting via WebSocket
Connect to: `wss://api.butterbase.ai/v1/{app_id}/realtime`
### Authentication
**Browser clients (recommended):** Pass token as query parameter:
```
wss://api.butterbase.ai/v1/app_abc123/realtime?token=eyJhbG...
```
**Node.js / server-side:** Use Authorization header:
```javascript
const ws = new WebSocket('wss://api.butterbase.ai/v1/app_abc123/realtime', {
headers: { Authorization: 'Bearer ' }
});
```
| Auth method | Role assigned |
|-------------|--------------|
| End-user JWT | butterbase_user (RLS enforced) |
| API key (`bb_sk_...`) | butterbase_service (sees all changes) |
| No auth | butterbase_anon |
## Client protocol
```json
// Client -> Server
{ "type": "subscribe", "table": "messages" }
{ "type": "unsubscribe", "table": "messages" }
// Server -> Client
{ "type": "connected", "app_id": "app_abc123", "role": "butterbase_user" }
{ "type": "subscribed", "table": "messages" }
{ "type": "change", "table": "messages", "op": "INSERT", "record": {...}, "old_record": null, "timestamp": "..." }
{ "type": "change", "table": "messages", "op": "UPDATE", "record": {...}, "old_record": {...}, "timestamp": "..." }
{ "type": "change", "table": "messages", "op": "DELETE", "record": null, "old_record": {...}, "timestamp": "..." }
{ "type": "heartbeat", "timestamp": "..." }
{ "type": "error", "message": "..." }
```
## Browser example
```javascript
const token = 'eyJhbG...'; // end-user JWT
const ws = new WebSocket(`wss://api.butterbase.ai/v1/app_abc123/realtime?token=${token}`);
ws.onopen = () => {
ws.send(JSON.stringify({ type: 'subscribe', table: 'messages' }));
};
ws.onmessage = (event) => {
const msg = JSON.parse(event.data);
if (msg.type === 'change') {
console.log(msg.op, msg.table, msg.record);
}
};
```
## Subscription filters
Subscribe to a subset of changes:
```json
{ "type": "subscribe", "table": "messages", "filter": { "channel_id": "abc" } }
```
Only changes where `channel_id = 'abc'` will be delivered. Filters match on exact column equality.
## Row-level security
RLS is enforced on realtime events:
- **butterbase_user** — Only receives changes for rows they can SELECT
- **butterbase_service** — Receives all changes
- **butterbase_anon** — Receives changes based on anon policies
## Presence tracking
Track who else is connected:
```json
// Opt in with metadata
{ "type": "presence_track", "metadata": { "name": "Alice", "cursor": { "x": 10, "y": 20 } } }
// Update metadata (e.g. cursor moved)
{ "type": "presence_update", "metadata": { "cursor": { "x": 50, "y": 60 } } }
```
Server broadcasts to all presence-tracking clients:
```json
{ "type": "presence_state", "clients": [{ "client_id": "...", "user_id": "...", "metadata": {...} }] }
{ "type": "presence_join", "client_id": "...", "user_id": "...", "metadata": {...} }
{ "type": "presence_update", "client_id": "...", "metadata": {...} }
{ "type": "presence_leave", "client_id": "...", "user_id": "..." }
```
Presence is in-memory only — it resets on server restart.
## WebSocket triggers
Deploy functions that fire when clients send custom events:
```
deploy_function({
name: "handle-chat",
code: "...",
trigger: { type: "websocket", config: { event: "chat_message" } }
})
```
Clients send events:
```json
{ "type": "event", "event": "chat_message", "payload": { "text": "hello" } }
```
The function response is returned:
```json
{ "type": "event_response", "event": "chat_message", "data": { "echo": { "text": "hello" } } }
```
## Limitations
- Tables must exist before enabling realtime
- The full row is sent on each change (no column filtering yet)
- Events during LISTEN reconnection may be lost — clients should re-fetch state on reconnect
## Substrate changes
This page covers realtime for your app's **database tables**. If your data lives in the [Substrate](/core-concepts/substrate/) (entities, the action ledger, decisions/commitments/learnings), it has a sibling stream — org-scoped, envelope-only frames — documented under [Substrate → Stream live updates to a UI](/core-concepts/substrate/#8-stream-live-updates-to-a-ui) and the SDK's `bb.substrate.stream`.
---
## Core Concepts / Substrate
Substrate is a per-user layer that gives your AI agents durable memory and a way to take real-world actions through a single audited surface. Instead of each agent owning its own scratchpad and side effects, all your apps share the same substrate for a given user — entities they reference, decisions they record, and actions they propose all land in one ledger you can review and govern.
It plugs into Butterbase the same way [Functions](/core-concepts/functions/) and [Storage](/core-concepts/storage/) do: you call it from inside a function via `ctx.substrate`, from the CLI with [`butterbase substrate`](/cli/substrate/), or from any client over HTTP with a substrate-scoped API key.
## What you get
| Concept | What it is |
|---|---|
| **Entities** | People, companies, projects, agents, etc. — the durable nouns your apps talk about. |
| **Action ledger** | Every action an agent or app proposed, with who proposed it, the policy verdict, and the result. |
| **Decisions, commitments, learnings, principles** | Long-form memory rows your agents can search later. |
| **Source artifacts** | Durable, FTS-indexed source material — meeting transcripts, email threads, call recordings, documents — that decisions, commitments, and learnings can link back to. Provenance for everything else in the substrate. |
| **Attention rules** | Scheduled rules that run on a snapshot of your substrate and propose actions when their conditions match. |
| **Outbox targets** | HMAC-signed webhooks that fire when actions execute (e.g. send the email draft to an external system). |
| **Settings** | Per-user toggles — `yolo_mode` for auto-approval, etc. |
| **WebSocket stream** | Live push of every entity, ledger, memory (decision / commitment / learning), rule, and firing change — so UIs update without polling. |
## How agents use it
When you run a serverless function for an app that is linked to a substrate user, the function's `ctx` gains a `substrate` object:
```typescript
export async function handler(req, ctx) {
// Propose an action. The substrate's policy engine decides whether it
// executes immediately, queues for approval, or is rejected.
const verdict = await ctx.substrate.propose('record_decision', {
title: 'Migrate billing to Stripe',
kind: 'strategic',
rationale: 'Vendor consolidation; lower switching cost than custom.',
});
// Search prior memory.
const prior = await ctx.substrate.searchMemory('billing', { kinds: ['decisions'], limit: 5 });
// Look up an entity.
const people = await ctx.substrate.findEntities({ type: 'person', limit: 10 });
return Response.json({ verdict, prior, people });
}
```
The available calls are:
| Call | Purpose |
|---|---|
| `propose(capability, payload, opts?)` | Propose an action. Returns `{ action_id, verdict, requires_approval, result? }`. |
| `getEntity(entity_id)` | Fetch one entity. |
| `findEntities({ type?, q?, limit? })` | List or search entities. |
| `searchMemory(query, { kinds?, limit? })` | Full-text search across decisions, commitments, learnings, and source artifacts. |
### Capabilities at a glance
Every proposed action either executes immediately or blocks in `proposed` state until the owner approves it. The `Default policy` column shows which behavior the platform applies out of the box. Owners can override with `dangerously_skip_approval: true` on a single call, but agents cannot.
A non-obvious asymmetry that has tripped up agent authors: **`record_decision` auto-approves, but `record_principle`, `supersede_decision`, and `retire_principle` all require human approval by default.** All three mutate the policy-enforcement layer of the substrate, so the platform conservatively gates them.
| Capability | Default policy | Reversible | Restricted | Notes |
|---|---|---|---|---|
| `record_decision` | auto | yes | no | Write a decision row. |
| `record_commitment` | auto | yes | no | Write a commitment. Accepts optional `source_artifact_id`. |
| `record_learning` | auto | yes | no | Write a retrospective learning. |
| `upsert_entity` | auto | yes | no | Create or update an entity. Dedups by id > canonical_keys > primary_email. |
| `update_entity` | auto | yes | no | Replace `attrs` wholesale on an existing entity (legacy). Prefer `patch_entity`. |
| `patch_entity` | auto | yes | no | RFC 7396 merge-patch over `attrs`. Supports `if_updated_at` optimistic lock. |
| `upsert_source_artifact` | auto | yes | no | Insert or update a source artifact. Idempotent by `(external_system, external_id)`. |
| `revert_action` | auto | no | no | Revert a single reversible ledger action. |
| `record_principle` | approval_required | no | no | Record a durable principle used by the policy engine. Requires human approval. |
| `supersede_decision` | approval_required | no | no | Mark an existing decision superseded and insert a replacement. Requires human approval. |
| `retire_principle` | approval_required | no | no | Set a principle to `status=expired`. Requires human approval. |
| `delete_entity` | approval_required | no | no | Hard-delete an entity. Not reversible. |
| `merge_entities` | approval_required | no | no | Collapse a duplicate entity into a survivor via alias. Not reversible. |
| `bulk_revert_actions` | approval_required | no | no | Revert up to 200 ledger actions in one call. Per-action failures are collected, not raised. |
| `send_email_draft` | approval_required | no | no | Record an intended email draft. Side-effecting; always requires approval for agent proposers. |
When the function runs on behalf of an app, the proposer is recorded as `kind: 'agent'` and certain side-effect capabilities require human approval even if the user has [`yolo_mode`](#yolo-mode) on.
## Entity primitives
### Upsert (`upsert_entity`)
Dedup order: **`id` > `canonical_keys` > `primary_email` > insert new**.
- If you pass `id`, it's an upsert by id (current legacy behavior).
- Else if you pass non-empty `canonical_keys`, substrate looks up an entity of the same type whose canonical_keys contain every key/value pair you sent (JSONB `@>`). On hit: update and return `was_insert: false`.
- Else if you pass `primary_email`, substrate looks up by `(type, lower(primary_email))`. On hit: update. On insert, substrate **auto-promotes** `primary_email` into `canonical_keys.email` so future calls can dedup either way.
Race-safety: primary_email lookups are protected by a partial unique index. Canonical_keys-only lookups are best-effort — two near-simultaneous identical writes can still race; clean up with `merge_entities`.
### Patch (`patch_entity`)
RFC 7396 JSON Merge Patch over `attrs`. Atomic.
```ts
await ctx.substrate.patchEntity('ent_…', { title: 'CTO', previous_title: null });
// title set to 'CTO', previous_title key deleted, all other attrs untouched.
```
Optional optimistic concurrency: pass `if_updated_at` to get an error instead of a silent clobber.
Use `patch_entity` for any partial update. `update_entity` (legacy) replaces `attrs` wholesale and is kept only for backwards compatibility.
### Merge (`merge_entities`)
Collapse a duplicate into a survivor.
```ts
await ctx.substrate.mergeEntities('ent_loser', 'ent_winner', 'duplicate by email');
```
Semantics:
- The **loser** is hard-deleted from `substrate.entities`.
- An alias row is inserted into `substrate.entity_aliases` mapping `loser_id → winner_id`.
- **No automatic FK rewriting.** If your app stores `attrs.company_id = 'ent_loser'` on other entities, those references will not be updated by `merge_entities`. Your read path must resolve old IDs through `entity_aliases`:
```sql
SELECT COALESCE(a.canonical_id, $1) AS resolved_id
FROM (VALUES ($1)) t(id)
LEFT JOIN substrate.entity_aliases a ON a.alias_id = $1;
```
- One ledger action per merge. `reversible: false` — undoing a merge means re-creating the loser, which the platform won't do for you.
### Delete (`delete_entity`)
Hard delete, not reversible. Requires approval by default.
```ts
await ctx.substrate.deleteEntity('ent_…', 'manual cleanup');
```
Prefer `merge_entities` when collapsing duplicates (preserves alias resolution). Use `delete_entity` only when the entity is genuinely garbage with no inbound references worth preserving.
For soft delete, patch the entity instead: `ctx.substrate.patchEntity(id, { deleted_at: new Date().toISOString() })` and filter on read.
### Idempotent proposals
Pass `idempotency_key` as a third argument to `propose` (or as a body field on `POST /v1/me/substrate/actions/propose`) to protect retries — network blips, lambda re-runs, or duplicate webhook deliveries — from doubling actions in the ledger:
```ts
await ctx.substrate.propose('record_decision', payload, {
idempotency_key: 'mtg_2026-06-16:record_decision',
});
```
Keys are scoped per substrate user (two users can reuse the same string without collision) and are retained forever — there is no TTL. Pick keys that are stable for the unit of work you are deduplicating; a meeting ID combined with the capability is a good pattern, while a per-call UUID defeats the purpose. When the key matches a prior action, the response returns that prior action's verdict and result unchanged, and includes `"replay": true` so callers can tell a replay apart from a fresh propose.
### Bulk revert (`bulk_revert_actions`)
Revert up to 200 ledger actions in one call. Per-action failures are collected into the response, not raised. Use after a buggy ingest run produced many bad actions:
```ts
await ctx.substrate.propose('bulk_revert_actions', {
action_ids: ['act_…', 'act_…', /* … */],
reason: 'rolling back failed ingest run 2026-06-11',
});
```
## Authentication
Three ways to reach the substrate over HTTP:
1. **Substrate-scoped API key** (`bb_sub_*`) — for CLIs, SDK clients, and headless integrations. Generate one with `butterbase keys generate --substrate`.
2. **Cognito session** (the dashboard at [docs.butterbase.ai](https://docs.butterbase.ai)) — handled for you by the web app.
3. **Inside a deployed function** — `ctx.substrate` is wired automatically when the app is linked to a substrate user; no token to manage.
## Yolo mode
By default every action goes through the policy engine and may require approval before it executes. Turn on `yolo_mode` to auto-approve any action where the proposer is a human:
```bash
butterbase substrate settings yolo on
```
Agent proposals from `ctx.substrate` are **not** affected by `yolo_mode` for side-effecting capabilities — that's a deliberate safety rail.
## The dashboard
Visit `/substrate` in your Butterbase dashboard to see the action ledger, entities, memory, attention rules, and pending approvals in a UI. The dashboard is a complete substitute for the CLI — anything you can do with `butterbase substrate` you can do in the browser.
## Walkthrough — your first substrate-aware agent
This walkthrough takes you from zero to a function that proposes a decision, an attention rule that watches your substrate on a schedule, and a webhook that fires when an action executes. ~10 minutes.
### 1. Provision your substrate
A substrate is created on first use. Either trigger it from the dashboard (click "Open Substrate") or from the CLI:
```bash
butterbase substrate settings show
```
If you see `{"yolo_mode": false, ...}`, you're provisioned. If you see a `not provisioned` error with a remediation hint, follow it.
### 2. Generate a substrate-scoped key
```bash
butterbase keys generate --substrate --name "my-laptop"
# → bb_sub_… (shown once — store it now)
export BUTTERBASE_API_KEY="bb_sub_..."
```
The key is bound to your user's substrate. It cannot read or write any *app* database; substrate routes only.
### 3. Propose your first action from the CLI
```bash
butterbase substrate propose record_decision \
--payload '{"title":"Adopt substrate","kind":"strategic","rationale":"agent memory needs a single source of truth"}'
```
Returns:
```json
{
"action_id": "act_01...",
"verdict": { "result": "auto_approved", "reason": "capability default = auto" },
"requires_approval": false,
"result": { "decision_id": "dec_01..." }
}
```
Your decision is now in `substrate.decisions`. Verify:
```bash
butterbase substrate memory "adopt substrate" --kinds decisions
```
### 4. Link an app to substrate
Substrate only injects into functions for apps that are explicitly linked to your substrate user. From the dashboard, open an app and click "Link to substrate", or use the SDK / CLI as your team's conventions dictate.
### 5. Deploy a function that uses `ctx.substrate`
```typescript
// fn-summarize-week.ts
export async function handler(req, ctx) {
const lastWeekDecisions = await ctx.substrate.searchMemory('', { kinds: ['decisions'], limit: 20 });
const verdict = await ctx.substrate.propose('record_decision', {
title: 'Weekly summary',
kind: 'operational',
rationale: `Reviewed ${lastWeekDecisions.length} decisions this week.`,
});
return Response.json({ verdict, count: lastWeekDecisions.length });
}
```
Deploy with `butterbase fn deploy` (or via MCP `deploy_function`). Invoke it once; in the action ledger you'll see the new decision attributed to `kind: 'agent'` with `source_app_id` set to your app.
### 6. Add an attention rule
Attention rules let your substrate take initiative on a schedule. They run a [JSON-Logic](https://jsonlogic.com/) predicate against your daily snapshot and, if it matches, propose actions from a template.
```json
{
"name": "weekly digest",
"trigger_cron": "0 9 * * 1",
"condition_mode": "snapshot_predicate",
"condition": { ">": [ { "var": "entity_count" }, 0 ] },
"action_capability": "send_email_draft",
"action_payload_template": {
"to": "you@example.com",
"subject": "Weekly digest",
"body": "{{entity_count}} entities tracked this week."
}
}
```
Save it and create:
```bash
butterbase substrate rules create --file rule.json
```
Preview what it would do today without scheduling it:
```bash
butterbase substrate rules preview --file rule.json
```
### 7. Send execution events to a webhook
When an action with a `send_email_draft` capability auto-executes, the substrate can POST it to your own endpoint:
```bash
butterbase substrate outbox put send_email_draft \
--webhook-url https://example.com/hooks/substrate \
--signing-secret "$(openssl rand -hex 16)"
```
Every webhook delivery is signed with `X-Butterbase-Signature: sha256=…` using the secret you provided. Retries and dead-lettering are handled for you.
### 8. Stream live updates to a UI
Every substrate write emits a change over a WebSocket, so your UI updates the instant an agent or another user changes something — no polling, no refresh. The stream carries **envelope-only** frames — `{ org, op, tbl, id }`, no row payload — and you re-fetch the affected row by `id` (the same model as [Realtime](/core-concepts/realtime/)).
What streams today: `entities`, `action_ledger`, `decisions`, `commitments`, `learnings`, `attention_rules`, and `attention_rule_firings`. The stream is **org-scoped** — a connection only receives changes for the org bound to its credential.
There are three ways to connect, depending on what credential the client holds.
**a) Server / script (has a substrate key).** Use the SDK's `bb.substrate.stream` — it handles the WebSocket, reconnects with backoff, and skips the `hello` frame for you:
```typescript
import { createClient } from '@butterbase/sdk';
const bb = createClient({ apiUrl: 'https://api.butterbase.ai', /* … */ });
const sub = bb.substrate.stream({
token: process.env.BUTTERBASE_SUBSTRATE_KEY, // bb_sub_… or bb_sk_…
onChange: (evt) => {
// evt = { org, op: 'insert' | 'update' | 'delete', tbl, id }
if (evt.tbl === 'entities') refetchEntity(evt.id);
},
onStatus: (s) => console.log('substrate stream', s), // 'connecting' | 'open' | 'closed'
});
// later
sub.unsubscribe();
```
**b) End-user app in the browser (no substrate key).** A browser must never hold a substrate key, so mint a **single-use ticket** through one of your app's functions, then open the stream with it. In the function:
```typescript
// app function: substrate-proxy
export async function handler(req, ctx) {
const { op } = await req.json();
if (op === 'ws_ticket') {
return Response.json(await ctx.substrate.wsTicket()); // { ticket, expires_in }
}
// … other ops
}
```
In the browser:
```typescript
// 1. Ask your function for a 60s single-use ticket.
const { ticket } = await bb.functions.invoke('substrate-proxy', { op: 'ws_ticket' });
// 2. Open the stream, then re-fetch on each change.
const ws = new WebSocket(`wss://api.butterbase.ai/v1/me/substrate/stream?ticket=${ticket}`);
ws.onmessage = (evt) => {
const change = JSON.parse(evt.data);
if (change.type === 'hello') return;
// change = { org, op, tbl, id } — e.g. invalidate your query cache by id
};
```
**c) Dashboard / cookie-authenticated browser.** If the browser already has a Cognito session, mint the ticket directly (no proxy function needed):
```typescript
const { ticket } = await fetch('/v1/me/substrate/ws-ticket', {
method: 'POST',
credentials: 'include',
}).then(r => r.json());
const ws = new WebSocket(`wss://api.butterbase.ai/v1/me/substrate/stream?ticket=${ticket}`);
```
In every case the server pushes a `{ type: 'hello' }` frame on connect, then one frame per change. **Tickets are single-use and expire after 60s** — mint a fresh one on each (re)connect, and reconnect with backoff (the SDK's `bb.substrate.stream` already does this).
## See also
- [CLI: `butterbase substrate`](/cli/substrate/) — every command for managing substrate from the shell.
- [Substrate API reference](/api-reference/substrate-api/) — every HTTP route, payload, and response shape.
- [Functions](/core-concepts/functions/) — how `ctx.substrate` plugs in.
- [Realtime](/core-concepts/realtime/) — the general realtime layer (substrate stream is a sibling, not a replacement).
---
## Core Concepts / Charging Your Users
This page is about taking money **from your app's end users**, into **your own Stripe account**.
For what Butterbase charges **you** — plan allowances, AI credits, spending caps, and usage — see [Plans & Usage](/core-concepts/plans-and-usage/).
Butterbase ships a complete **Stripe Connect** integration so your app can charge its own users — subscriptions, one-time products, or both. You do not write Stripe code, host a checkout page, or run a webhook server.
## What you get
- **Money goes straight to your Stripe account.** Butterbase creates a Stripe Express account owned by you; charges are made *on* that account, and Stripe pays out to your bank.
- **0% platform fee.** Butterbase takes no cut of Connect transactions — `platform_fee_cents` is always `0`. You pay Stripe's normal processing fees and nothing else.
- **Hosted checkout.** Every purchase returns a Stripe Checkout URL. PCI scope stays with Stripe.
- **Webhooks already handled.** Subscription activation, renewal, failure, cancellation, and refunds are processed for you and written to your app's tables.
- **A subscription/order model in your database.** `app_plans`, `app_products`, `app_subscriptions`, and `app_orders` are queryable from your functions and RLS policies.
- **Works everywhere.** Dashboard UI, REST API, CLI (`butterbase app-billing`), TypeScript SDK (`bb.billing.*`), and MCP.
## Before you begin
- [ ] Your app is created and its **users sign in through Butterbase Auth** — checkout needs a real row in `app_users` with an email. See [Authentication](/core-concepts/authentication/).
- [ ] You have (or can create) a Stripe account, and you can complete Stripe's identity/bank verification for your country.
- [ ] You know which model you want: recurring **plans**, one-time **products**, or both.
- [ ] You have a `successUrl` and `cancelUrl` in your frontend for Stripe to return users to.
## Step 1 — Onboard your Stripe Connect account
This creates a Stripe Express account for the app and hands you a Stripe-hosted onboarding link.
**Dashboard (recommended):** go to **App → Monetization → Stripe Connect → Connect with Stripe**. You'll be redirected to Stripe, then back to the dashboard.
**REST API:**
```
POST /v1/{app_id}/billing/connect/onboard
Authorization: Bearer {platform_api_key}
```
```json
{
"accountId": "acct_1Nv...",
"onboardingUrl": "https://connect.stripe.com/setup/e/acct_1Nv.../..."
}
```
**SDK:**
```typescript
const { data } = await bb.billing.connectOnboard();
window.location.href = data.onboardingUrl;
```
:::caution
Only the **app owner** can call the Connect and plan/product endpoints. A non-owner org member gets `403 Not authorized`.
:::
Open `onboardingUrl` and complete Stripe's flow — business details, identity verification, and a payout bank account. The link is single-use and expires; call the endpoint again to get a fresh one. It is normal for this to take a few minutes, and for some countries Stripe may hold `payouts_enabled` until it finishes reviewing your documents.
## Step 2 — Confirm you can accept payments
```
GET /v1/{app_id}/billing/connect/status
```
```json
{
"accountId": "acct_1Nv...",
"chargesEnabled": true,
"detailsSubmitted": true,
"payoutsEnabled": true
}
```
| Field | Must be `true` before… |
|-------|------------------------|
| `detailsSubmitted` | Stripe considers onboarding finished |
| `chargesEnabled` | **any checkout will work** — Butterbase refuses to create a session without it (`CONNECT_NOT_READY`) |
| `payoutsEnabled` | Stripe will actually move money to your bank |
If `chargesEnabled` is `false`, re-run Step 1 and finish whatever Stripe is still asking for.
## Step 3 — Choose your pricing model
| You want to sell | Use | Objects created |
|---|---|---|
| Monthly or yearly access | **Plans** | `app_plans` → `app_subscriptions` |
| A one-off purchase (digital goods, credits, lifetime access) | **Products** | `app_products` → `app_orders` |
| Both | Both | — |
Plans and products are independent; an app can have any number of each.
## Step 4a — Create subscription plans
```json
POST /v1/{app_id}/billing/plans
Authorization: Bearer {platform_api_key}
{
"name": "Pro",
"priceCents": 999,
"interval": "month",
"features": ["Unlimited projects", "Priority support", "Custom domain"]
}
```
| Field | Type | Notes |
|-------|------|-------|
| `name` | string, 1–100 chars | Shown on the Stripe Checkout line item |
| `priceCents` | integer ≥ 0 | **Cents.** `999` = $9.99. Subscriptions are charged in USD. |
| `interval` | `"month"` \| `"year"` | Defaults to `"month"` |
| `features` | string[] | Free-form marketing bullets — your UI decides what to do with them |
The response is the created row, including the `id` (a UUID) you'll pass to `subscribe`.
```bash
butterbase app-billing plans create --name "Pro" --price-cents 999 --interval month
butterbase app-billing plans list
```
```typescript
const { data: plan } = await bb.billing.createPlan({
name: 'Pro', priceCents: 999, interval: 'month',
features: ['Unlimited projects', 'Priority support'],
});
```
**Changing a plan:**
```json
PUT /v1/{app_id}/billing/plans/{plan_id}
{ "priceCents": 1299, "active": true }
```
You can update `name`, `priceCents`, `features`, and `active`. You cannot change `interval` — create a new plan instead. Setting `active: false` retires a plan: it stops accepting new subscribers, and existing subscriptions keep running.
:::note
Price changes apply to **new** checkouts only. Existing subscribers stay on the price they signed up at until they resubscribe.
:::
## Step 4b — Create one-time products
```json
POST /v1/{app_id}/billing/products
Authorization: Bearer {platform_api_key}
{
"name": "Premium Template Pack",
"description": "50+ premium UI templates",
"priceCents": 2999,
"metadata": { "category": "templates", "sku": "TPL-50" }
}
```
| Field | Type | Notes |
|-------|------|-------|
| `name` | string, 1–100 chars | Checkout line item |
| `description` | string, ≤ 500 chars | Optional; shown at checkout |
| `priceCents` | integer ≥ 0 | Cents |
| `metadata` | `Record` | Your own keys — comes back on the order, use it to drive fulfillment |
Currency defaults to `usd`. Update with `PUT /v1/{app_id}/billing/products/{product_id}` (`name`, `description`, `priceCents`, `active`, `metadata`).
```bash
butterbase app-billing products create --name "Template Pack" --price-cents 2999
```
## Step 5 — Show the catalog in your app
Listing plans and products is **public** — no auth needed, so you can render a pricing page to logged-out visitors.
```
GET /v1/{app_id}/billing/plans → { "plans": [...] }
GET /v1/{app_id}/billing/products → { "products": [...] }
```
```typescript
const { data: plans } = await bb.billing.listPlans();
const { data: products } = await bb.billing.listProducts();
```
Filter out rows where `active` is `false` before rendering — inactive rows are still returned so historical subscriptions can resolve their plan name.
## Step 6 — Send a user to checkout
:::danger
This is the step people get wrong. `subscribe` and `purchase` must be called **as the end user** — with the app JWT your user got from Butterbase Auth, *not* your platform API key. The user id in that token is who gets the subscription.
:::
**Subscribe:**
```json
POST /v1/{app_id}/billing/subscribe
Authorization: Bearer {end_user_app_jwt}
{
"planId": "3f9a…-uuid",
"successUrl": "https://yourapp.com/billing/success",
"cancelUrl": "https://yourapp.com/pricing"
}
```
```json
{ "sessionId": "cs_live_…", "url": "https://checkout.stripe.com/c/pay/cs_live_…" }
```
**Purchase:**
```json
POST /v1/{app_id}/billing/purchase
Authorization: Bearer {end_user_app_jwt}
{ "productId": "8b21…-uuid", "successUrl": "…", "cancelUrl": "…" }
```
```json
{ "sessionId": "cs_live_…", "url": "https://checkout.stripe.com/…", "orderId": "0c7d…-uuid" }
```
A `pending` row is written to `app_orders` **before** checkout opens, so you always have an id to correlate against.
Then redirect:
```typescript
const { data, error } = await bb.billing.subscribe({
planId: plan.id,
successUrl: `${window.location.origin}/billing/success`,
cancelUrl: `${window.location.origin}/pricing`,
});
if (error) return showError(error);
window.location.href = data.url;
```
`successUrl` / `cancelUrl` are optional but you should always set them — the defaults point at the Butterbase dashboard, not your app.
## Step 7 — Understand what happens after payment
Payment is not final when the user returns to `successUrl`. It's final when Stripe confirms it. Butterbase runs the Connect webhook handler and writes the result into your app's tables:
| Stripe event | What Butterbase does |
|-------|----------------------|
| `checkout.session.completed` | Activates the subscription, or marks the order `paid` |
| `invoice.paid` | Rolls the subscription period forward |
| `invoice.payment_failed` | Marks the subscription `past_due` |
| `customer.subscription.updated` | Syncs status and `cancel_at_period_end` |
| `customer.subscription.deleted` | Marks the subscription canceled |
| `payment_intent.payment_failed` | Marks the order `failed` |
| `charge.refunded` | Marks the order `refunded`, stamps `refunded_at` |
Events are deduplicated by Stripe event id, so retries are safe.
**On Butterbase Cloud there is nothing to configure.** Your Express account's events flow to the platform endpoint automatically. Write your app to read state from `GET /billing/subscription` and `GET /billing/orders` — do not try to grant access from the `successUrl` redirect alone, because the webhook may land a moment later.
:::note[Self-hosting only]
If you run your own control API, register a Stripe webhook endpoint at `https:///webhooks/stripe/connect`, enable **"Listen to events on Connected accounts"** (Connect events carry an `account` field, and the handler skips any event without one), subscribe to the events above, and set the signing secret as `STRIPE_CONNECT_WEBHOOK_SECRET` in the control API environment.
:::
## Step 8 — Gate access on subscription status
```
GET /v1/{app_id}/billing/subscription
Authorization: Bearer {end_user_app_jwt}
```
```json
{
"subscription": {
"id": "…", "plan_id": "…", "status": "active",
"current_period_start": "2026-08-01T00:00:00Z",
"current_period_end": "2026-09-01T00:00:00Z",
"cancel_at_period_end": false,
"plan_name": "Pro", "price_cents": 999, "interval": "month",
"features": ["Unlimited projects"]
}
}
```
Returns `{ "subscription": null }` when the user has none. Only `active`, `trialing`, and `past_due` subscriptions are returned — a canceled or expired one reads as `null`, which is exactly the check you want:
```typescript
const { data: sub } = await bb.billing.getSubscription();
const isPro = sub !== null && sub.status === 'active';
```
**Enforce it on the server, not just in the UI.** The reliable pattern is a [serverless function](/core-concepts/functions/) that queries `app_subscriptions` for the caller before doing paid work:
```sql
SELECT 1 FROM app_subscriptions
WHERE app_id = $1 AND user_id = $2
AND status IN ('active', 'trialing')
AND current_period_end > now();
```
You can also drive [row-level security](/core-concepts/row-level-security/) policies from the same table so premium rows are unreadable without a live subscription.
## Step 9 — Cancellation
```
POST /v1/{app_id}/billing/cancel
Authorization: Bearer {end_user_app_jwt}
```
Sets `cancel_at_period_end = true`. The user keeps access until `current_period_end`, then Stripe emits `customer.subscription.deleted` and the subscription stops being returned. Returns `404` if there's no active subscription.
There is no "resume" endpoint — a user who changes their mind subscribes again.
## Step 10 — Fulfilling one-time purchases
```
GET /v1/{app_id}/billing/orders → { "orders": [...] }
GET /v1/{app_id}/billing/orders/{order_id} → one order
```
Both are end-user scoped: a user only ever sees their own orders.
| Status | Meaning |
|--------|---------|
| `pending` | Checkout session created, payment not completed |
| `paid` | Payment succeeded — **fulfill here** |
| `failed` | Payment failed |
| `refunded` | Refunded; `refunded_at` is set |
Never grant access on `pending`. Poll for `paid` from your success page, or read the order inside a function before serving the purchased asset. The product's `metadata` comes back on the order — use it to decide what to deliver.
## Testing before you launch
1. Put your Stripe account in **test mode** and complete Connect onboarding with Stripe's test business details.
2. Create a cheap plan and product.
3. Sign in to your app as a real end user and hit `subscribe` / `purchase`.
4. Pay with `4242 4242 4242 4242`, any future expiry, any CVC. Use `4000 0000 0000 0341` to test a failed payment.
5. Confirm the webhook fired: `GET /billing/subscription` flips to `active`, or the order flips to `paid`.
6. Test the cancel path and the refund path (refund the charge in Stripe, confirm the order flips to `refunded`).
## Going-live checklist
- [ ] `connect/status` shows `chargesEnabled` **and** `payoutsEnabled`
- [ ] Every plan/product you don't want sold is `active: false`
- [ ] `successUrl` / `cancelUrl` point at your domain, not the dashboard
- [ ] Access is enforced server-side, not only in the frontend
- [ ] You have terms of service and a refund policy — Stripe requires them for Connect accounts
## Troubleshooting
| Error code | HTTP | Cause | Fix |
|---|---|---|---|
| `CONNECT_NOT_CONFIGURED` | 400 | No Stripe account attached to this app | Run Step 1 |
| `CONNECT_NOT_READY` | 400 | `charges_enabled` is false on the Stripe account | Finish Stripe onboarding; re-check Step 2 |
| `PLAN_NOT_FOUND` | 404 | Bad `planId`, wrong app, or the plan is `active: false` | Re-list plans and check the UUID |
| `PRODUCT_NOT_FOUND` | 404 | Same, for products | — |
| `USER_NOT_FOUND` | 404 | No `app_users` row for the token's user id | The caller must be a real Butterbase-Auth user of *this* app |
| `403 Not authorized` | 403 | Non-owner calling a developer endpoint | Use the app owner's credentials |
| `401` on `subscribe`/`purchase`/`orders` | 401 | Sent a token that isn't an end-user app JWT or a platform token | See Step 6 |
| Nothing activates after payment | — | You granted access from the redirect instead of the recorded state, or (self-hosted) the webhook isn't wired | Re-read `GET /billing/subscription` or the order; self-hosted, check Step 7 and Stripe's delivery log |
## Endpoint reference
**Developer endpoints — platform auth, owner only:**
| Method | Path | Purpose |
|--------|------|---------|
| POST | `/v1/{app_id}/billing/connect/onboard` | Create/refresh the Stripe Connect account link |
| GET | `/v1/{app_id}/billing/connect/status` | Onboarding + charges + payouts status |
| POST | `/v1/{app_id}/billing/plans` | Create a subscription plan |
| PUT | `/v1/{app_id}/billing/plans/{plan_id}` | Update a plan |
| POST | `/v1/{app_id}/billing/products` | Create a product |
| PUT | `/v1/{app_id}/billing/products/{product_id}` | Update a product |
**Public:**
| Method | Path | Purpose |
|--------|------|---------|
| GET | `/v1/{app_id}/billing/plans` | Plan catalog |
| GET | `/v1/{app_id}/billing/products` | Product catalog |
**End-user endpoints — app JWT:**
| Method | Path | Purpose |
|--------|------|---------|
| POST | `/v1/{app_id}/billing/subscribe` | Start a subscription checkout |
| GET | `/v1/{app_id}/billing/subscription` | Current subscription |
| POST | `/v1/{app_id}/billing/cancel` | Cancel at period end |
| POST | `/v1/{app_id}/billing/purchase` | Buy a product |
| GET | `/v1/{app_id}/billing/orders` | Order history |
| GET | `/v1/{app_id}/billing/orders/{order_id}` | Single order |
## Data model
| Table | Holds |
|-------|-------|
| `app_plans` | Your subscription plans (`name`, `price_cents`, `interval`, `features`, `active`) |
| `app_products` | Your one-time products (`name`, `description`, `price_cents`, `currency`, `metadata`, `active`) |
| `app_subscriptions` | One row per user per subscription (`status`, period bounds, `cancel_at_period_end`) |
| `app_orders` | One row per purchase attempt (`amount_cents`, `platform_fee_cents`, `status`, `refunded_at`) |
These live in your app's runtime database, so functions and RLS policies can read them directly.
## Not using Connect?
You can skip all of this and call Stripe (or any other processor) yourself from a [serverless function](/core-concepts/functions/), storing purchase state in your own tables. You lose the hosted webhook handling and the built-in subscription model, and you take on PCI and key management. The [Monetization guide](/guides/monetization/) has a compact end-to-end walkthrough of the Connect path.
---
## Core Concepts / Plans & Usage
This page is about what **Butterbase charges you** for running your backend.
For charging **your own end users**, see [Charging Your Users](/core-concepts/billing/).
## Plans
There are four, and each one is the one before it plus more:
| | |
|---|---|
| **Playground** | Free. Build something and find out whether it works. No card needed. |
| **Launch** | Everything in Playground, plus the things you need to put a real app in front of real users: more room, [custom domains](/core-concepts/custom-domains/), and [preview deployments](/core-concepts/preview-deployments/). |
| **Certified** | Everything in Launch, plus room to grow, a bigger AI allowance, and priority support. |
| **Enterprise** | Everything in Certified, plus SSO, a SOC 2 report, a HIPAA add-on, an uptime guarantee, and a dedicated contact. Priced with you. |
You pay per **organization**, not per app, and every account starts on Playground.
The exact prices and allowances live in two places, on purpose — they're not copied here, because they change and this page would go stale:
- **[butterbase.ai/pricing](https://butterbase.ai/pricing)** — the side-by-side comparison
- **[Your dashboard Billing page](https://dashboard.butterbase.ai/billing)** — what *your* organization is actually on, with live usage against each limit
```bash
butterbase billing status
```
Playground projects are paused after a week with nothing happening on them. Nothing is deleted — resume them from the dashboard whenever you come back.
## Usage meters
| Meter | What it measures |
|-------|-----------------|
| `ai_credits` | AI model usage cost, in dollars |
| `storage_bytes` | Total file storage across all apps in the org |
| `lambda_invocations` | Total function executions |
| `bandwidth_bytes` | Data transferred out |
## Credits, top-ups, and spending caps
AI usage draws down a single credit balance per organization, in this order:
1. **Monthly allowance** — a per-tier credit grant, refilled on each successful subscription invoice.
2. **Top-up balance** — pay-as-you-go credit you buy in advance; never expires.
When both run out, AI calls stop. Buy a top-up or upgrade to carry on — nothing keeps running up a bill in the background.
**Buy a top-up:**
```
POST /dashboard/billing/topup
{ "amount": 25 }
```
```bash
butterbase billing topup 25
```
**Spending cap** — an org-level ceiling on AI spend, shown on the dashboard Billing page and adjustable per org.
```bash
butterbase billing cap get
butterbase billing cap raise --raise-by 50
```
**Auto-refill** — optionally top up automatically when the balance drops below a threshold. Configure it on the dashboard Billing page.
## Checking your usage
```
GET /dashboard/billing
```
Returns current plan, limits, usage percentages, credit balance, and spending cap.
```
GET /dashboard/usage?startDate=2026-01-01&endDate=2026-01-31&meterType=ai_credits
```
Returns daily usage over a date range.
```bash
butterbase billing status
butterbase billing usage --start 2026-01-01 --end 2026-01-31 --meter ai_credits
```
## Upgrading your plan
```json
POST /dashboard/billing/checkout
{ "planId": "" }
```
Returns a Stripe Checkout `url`. Limits update immediately after payment succeeds.
## Managing your subscription
```
POST /dashboard/billing/portal
```
Returns a URL to the Stripe self-service portal — update payment methods, download invoices, cancel.
```bash
butterbase billing portal
```
## What happens when you exceed a limit
**Free tier:** the org is soft-locked. Reads still work; writes are blocked until usage drops or you upgrade.
**Paid plans:** when your AI credit balance runs out, AI calls stop until you top up or upgrade. Other limits — storage, for instance — are enforced as plan caps. If a payment fails, a grace period begins; after it expires the org is suspended.
## Account statuses
| Status | Meaning |
|--------|---------|
| `active` | Normal operation |
| `soft_locked` | Free-tier limits exceeded |
| `suspended` | Payment failure past the grace period |
---
---
## Core Concepts / Integrations
Integrations let your app's users connect their external accounts (Gmail, Slack, GitHub, etc.) and grant your app permission to act on their behalf. Butterbase manages the OAuth flow for you — no OAuth server, no token storage, no refresh logic.
## How it works
1. **Configure** — You (the app developer) enable a toolkit for your app. Butterbase creates an OAuth configuration on your behalf.
2. **Connect** — Your end-user clicks a connect button. Your app calls the connect endpoint, gets a redirect URL, and sends the user there. The OAuth handshake is handled for you.
3. **Execute** — Once connected, your app calls the execute endpoint with a tool name and parameters. Butterbase forwards the call using the user's stored credentials.
## Curated integrations
These toolkits have first-class support and are pre-verified:
| Toolkit | Slug | Use cases |
|---------|------|-----------|
| Gmail | `gmail` | Send emails, read inbox, manage labels |
| Google Calendar | `google-calendar` | Create events, list upcoming meetings |
| Slack | `slack` | Send messages, create channels, manage users |
| Google Sheets | `google-sheets` | Read and write spreadsheet data |
| Notion | `notion` | Create pages, search, update databases |
| GitHub | `github` | Create issues, open PRs, read repos |
| HubSpot | `hubspot` | Manage contacts, deals, companies |
| Outlook | `outlook` | Send emails, manage calendar |
| Google Drive | `google-drive` | Upload, download, list files |
| Discord | `discord` | Send messages, manage servers |
You can also search the full integration catalog (1000+ toolkits) via `GET /v1/:appId/integrations/available?search=`.
## Configuring an integration (admin)
Enable a toolkit for your app. Requires an API key:
```json
POST /v1/:appId/integrations/configure
{
"toolkit": "gmail",
"displayName": "Gmail",
"scopes": []
}
```
Response:
```json
{
"id": "uuid",
"app_id": "app_abc123",
"toolkit_slug": "gmail",
"enabled": true
}
```
To disable: `DELETE /v1/:appId/integrations/configure/:toolkit`
## Connecting an end-user account
Your app calls the connect endpoint with a redirect URL. The user is sent to the OAuth authorization page:
```json
POST /v1/:appId/integrations/connect
Authorization: Bearer
{
"toolkit": "gmail",
"redirectUrl": "https://yourapp.com/settings?tab=integrations"
}
```
Response:
```json
{
"authUrl": "https://accounts.google.com/...",
"connectionRequestId": "ca_xxx"
}
```
Redirect the user to `authUrl`. After they authorize, they are redirected back to your `redirectUrl` with `?status=connected&toolkit=gmail`.
:::note
The OAuth callback is handled entirely by Butterbase. You do not need to set up a callback route in your application.
:::
## Executing tools
Once a user has connected their account, you can execute any tool for that toolkit:
```json
POST /v1/:appId/integrations/execute
Authorization: Bearer
{
"toolName": "GMAIL_SEND_EMAIL",
"params": {
"to": "user@example.com",
"subject": "Hello from my app",
"body": "This was sent via Butterbase integrations."
}
}
```
Response:
```json
{
"successful": true,
"data": { "messageId": "msg_xxx" }
}
```
To list available tools for a toolkit:
```
GET /v1/:appId/integrations/tools?toolkit=gmail
```
## Using integrations in functions
The `ctx.integrations` object is injected into every Butterbase function:
```typescript
export default async function handler(ctx) {
// Execute a tool on behalf of the calling user
const result = await ctx.integrations.execute('GMAIL_SEND_EMAIL', {
to: ctx.body.email,
subject: 'Welcome!',
body: 'Thanks for signing up.',
});
// Execute as a specific user (e.g. in a cron job)
const events = await ctx.integrations.asUser(userId).execute(
'GOOGLECALENDAR_EVENTS_LIST',
{ timeMin: new Date().toISOString() }
);
return { ok: true };
}
```
**Authentication.** `ctx.integrations` is auto-wired with a per-app function key.
It can only call `/integrations/execute` for the app it was injected into, and
it always runs as a service caller — so `.asUser(userId)` is required when you
need an end-user's connection (cron jobs, scheduled syncs, webhook handlers).
The bare `ctx.integrations.execute(...)` form only works when the function was
invoked with an end-user JWT, because it relies on the request's auth context
to resolve the connection.
## SDK
```typescript
import { Butterbase } from '@butterbase/sdk';
const bb = new Butterbase({ appId: 'app_xxx', apiKey: 'bb_sk_...' });
// Admin: configure a toolkit
await bb.integrations.configure('slack');
// Get configured integrations
const { data } = await bb.integrations.getConfig();
// User: generate OAuth connect URL
const { data: result } = await bb.integrations.connect('slack', {
redirectUrl: 'https://yourapp.com/connected',
});
window.location.href = result.authUrl;
// Execute a tool (JWT auth)
const { data } = await bb.integrations.execute('SLACK_SEND_MESSAGE', {
channel: '#general',
text: 'Hello from my app',
});
// Service-level execution on behalf of a user
const { data } = await bb.integrations.asUser(userId).execute(
'GMAIL_SEND_EMAIL',
{ to: 'user@example.com', subject: 'Hi', body: 'Hello' }
);
```
## Managing connections
```
GET /v1/:appId/integrations/connections — list connected accounts
DELETE /v1/:appId/integrations/connections/:id — disconnect an account
```
Users only see their own connections. API key callers see all connections for the app.
---
## Templates / Overview
A **template** is a public Butterbase app that anyone can clone. Cloning gives you a brand-new app you own outright — schema, security policies, functions, Durable Objects, and source files already in place, running on a live backend in the region you pick.
This is not a starter repo. There is no "now wire up your database" step. The clone comes up provisioned, migrated, and deployable.
Two first-party templates are published today — a full AI-native CRM and an AI support desk. See **[Available Templates](/templates/available/)**.
## Why start from a template
**You skip the boring 80%.** Auth wiring, table design, RLS policies, function scaffolding, storage buckets, CORS — the parts every app needs and nobody enjoys writing — arrive already done and already working together.
**You start from something that ran.** A template isn't a snapshot of someone's aspirations. It's a copy of an app that was actually deployed, with the schema that actually served traffic.
**You own it completely.** The clone is your app, in your organization, on your plan, in your region. There is no upstream dependency, no license check, no phone-home. The publisher can delete their app tomorrow and yours keeps running.
**Nothing of the publisher's leaks to you, and nothing of yours leaks to them.** Secrets are the hard line: API keys, OAuth client secrets, and BYOK credentials never cross. You see the *names* of the environment variables a template needs so you know exactly what to fill in — never the values.
**The tedious bits get filled in for you.** Butterbase resolves `BUTTERBASE_API_URL` and `BUTTERBASE_APP_ID` to your new app automatically, and can mint a fresh scoped API key for `BUTTERBASE_API_KEY` so the cloned functions can talk to their own backend on the first invocation.
**You know what you're signing up for before you clone.** A preflight call lists every environment variable the template's functions and Durable Objects expect, and marks each one as auto-filled or "you must supply this."
**It works from wherever you work.** The dashboard, the CLI, the REST API, and any MCP-connected AI agent all drive the same clone pipeline.
## What you get in a clone
| Copied | Not copied |
|---|---|
| Database schema — tables, columns, indexes | End-user accounts and sessions |
| Row-level security policies | OAuth **client secrets** |
| Serverless function code | Function environment variable **values** |
| Durable Object classes | BYOK AI provider keys |
| Repo files (latest pushed snapshot) | [Custom domains](/core-concepts/custom-domains/) |
| The published frontend, re-pointed at your app | — |
| Non-secret config — storage settings, CORS, OAuth providers and redirect URLs, AI model defaults | Billing and Stripe Connect setup |
| App-level environment variables | Invocation history and audit logs |
| Rows in tables the publisher marked `_seed: true` | Invocation history and audit logs |
Full detail in [Configuring Your Clone](/templates/configure/).
## How a clone runs
Cloning is asynchronous. You get a `job_id` back immediately and poll it. The job walks these stages, so a status read tells you exactly where it is:
`pending` → `processing` → `replaying_schema` → `replaying_rls` → `replaying_durable_objects` → `replaying_functions` → `replaying_config` → `copying_repo` → `seeding_data` → `completed`
A failed job reports `error_message` and can be retried. A successful job can still return `warnings[]` — soft failures worth reading, like an auth hook that couldn't be rebound.
## Limits
| Limit | Value |
|---|---|
| Clones started per user | 5 per hour |
| Concurrent in-flight clones per user | 3 |
| Source requirements | `visibility: public` **and** at least one `butterbase repo push` |
| Quota | Each clone is a new app and counts against your plan's project limit |
| Name uniqueness | App names are globally unique — a taken name returns `409` |
## Where to go next
- **[Available Templates](/templates/available/)** — the live catalog, with a page for each template
- **[Cloning a Template](/templates/cloning/)** — find one and clone it, from the dashboard, CLI, MCP, or API
- **[Configuring Your Clone](/templates/configure/)** — the post-clone checklist that takes it from "cloned" to "live"
- **[Publishing a Template](/templates/publishing/)** — turn one of your apps into a template others can clone
---
## Templates / Available Templates
Two first-party templates are published and listed today. Both are complete, production-shaped applications, not demos: they're the apps Butterbase itself uses.
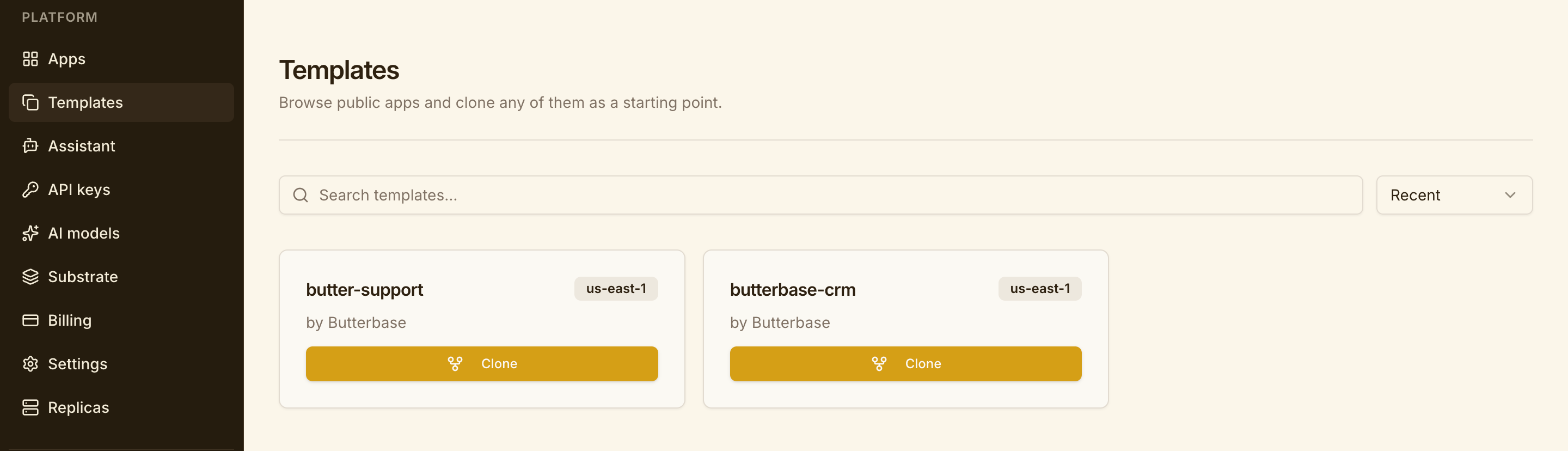
## The catalog
| Template | What it is | Functions | Clones | Region | Setup effort |
|---|---|---|---|---|---|
| **[Butterbase CRM](/templates/butterbase-crm/)** | A full AI-native CRM — contacts, companies, deals, Gmail/Calendar sync, meeting notetaker, campaigns, social publishing, lead search | 56 | 33 | `us-east-1` | **None.** Every environment variable auto-fills at clone time. |
| **[Butter Support](/templates/butter-support/)** | An AI support desk — embeddable widget, RAG over your docs, agent-drafted replies with human approval, escalation, policy learning | 30 | 19 | `us-east-1` | 2 function keys + 6 Durable Object keys |
Browse the live catalog any time:
```bash
butterbase templates --sort popular
```
```
manage_app action: "find_templates", sort: "popular"
```
Or open **Templates** in the [dashboard](https://dashboard.butterbase.ai).
:::note
The catalog is anyone's to add to. Any public app with a pushed repo snapshot is clonable, and setting `listed: true` puts it in this browser. See [Publishing a Template](/templates/publishing/).
:::
## Picking one
**Start from Butterbase CRM if** you're building anything that tracks people and organisations over time — a sales CRM, an investor tracker, a recruiting pipeline, a partnerships desk. It's the larger of the two and the easier to stand up, because nothing needs a third-party secret to boot.
**Start from Butter Support if** you're building anything where an AI answers from your own content and a human approves before it goes out — a support desk, an internal helpdesk, a docs assistant, a triage queue. It's the better demonstration of RAG, Durable Objects, and the approval-gated agent pattern.
**Start from neither if** your domain is genuinely different. Both templates carry a lot of opinion. A smaller app you build from [Quickstart](/getting-started/quickstart/) may be faster than deleting 40 functions you don't want.
## What both give you
- A provisioned database with schema and row-level security already applied
- Dozens of deployed serverless functions, including cron-triggered background jobs
- Auth wired up, with an app-level user model
- AI gateway usage already integrated — no key wrangling to get a first response
- A repo snapshot you can pull locally and edit
- Substrate integration, if you want agent memory across sessions
## Before you clone either
Both are **large**. Cloning is not instant — the pipeline replays schema, RLS, Durable Objects, functions, config, repo, and seed data in sequence, and 56 functions take time to redeploy. Expect minutes, not seconds, and poll the job rather than watching a spinner.
Both also count as one app against your plan's project limit. Playground allows one project total, so if you're on Playground you'll need to be starting fresh or [upgrade](/core-concepts/plans-and-usage/) first.
---
## Templates / Butterbase CRM
**App ID:** `app_44zjayftl7b3` · **Region:** `us-east-1` · **56 functions** · **33 clones**
An AI-native CRM. Contacts and companies enrich themselves, Gmail and Calendar sync in on a schedule, meetings get recorded and summarised by a notetaker bot, and an agent proposes deals off the activity it sees. Campaigns and social publishing are built in.
This is the largest template in the catalog and the easiest to stand up: **every environment variable it needs is filled in automatically at clone time.** There is no third-party API key you must obtain before it will boot.
## What's in it
### Contacts, companies, and enrichment
`enrich-person` · `enrich-company` · `summarize-company` · `find-duplicates` · `trigger-enrichment` · `crm-record-activity`
Records enrich from public sources on demand or on write. Duplicate detection runs across the contact set, and companies get an AI-written summary.
### Google sync
`ingest-gmail` · `ingest-calendar` · `auto-sync-google` *(cron)* · `upsert-sync-settings`
Mail and calendar pull into the activity timeline on a schedule. Per-user sync settings decide what's ingested.
### Meetings and notetaking
`start-meeting-bot` · `cancel-meeting-bot` · `notetaker-webhook` · `ingest-meeting-transcript` · `get-meeting-notes` · `crm-upsert-meeting` · `migrate-meetings-to-substrate`
A bot joins the call, transcribes it, and writes structured notes back onto the meeting record. The webhook secret for this is **minted for you** during the clone.
### AI
`agent-chat` · `ai-search` · `ai-suggest-filters`
Natural-language chat over the CRM, semantic search across records, and AI-generated list filters.
### Deals
`propose-deals` · `accept-deal-proposal` · `agent-proposals-expire` *(cron)*
An agent proposes deals from observed activity; a human accepts. Unaccepted proposals expire on a schedule.
### Lead generation
`lead-search` · `lead-save` · `lead-cost-preview` · `list-lead-lists`
Search for leads, preview the credit cost before committing, and save results into lists.
### Campaigns
`create-campaign-list` · `start-campaign` · `pause-campaign` · `process-campaign-sends` *(cron)* · `resolve-pending-emails` *(cron)* · `reply-to-inbox-item`
Build a list, start a sequence, and let the cron workers handle sending and reply resolution.
### Social publishing
`create-social-post` · `edit-social-post` · `clone-social-post` · `publish-social-post` · `send-social-post` · `delete-social-post-from-platform` · `process-scheduled-social-posts` *(cron)* · `comment-on-social-post` · `discover-comment-targets` · `run-comment-discovery` *(cron)* · `execute-comment-campaign` · `fetch-post-replies` *(cron)* · `get-subreddit-flairs` · `configure-social-toolkit`
Draft, schedule, and publish posts across platforms, plus a comment-campaign engine that finds targets and engages on a schedule.
### Integrations, team, and substrate
`register-integration` · `unregister-integration` · `list-workspace-integrations` · `cleanup-orphan-integrations` *(cron)* · `invite-member` · `accept-invite` · `check-allowlist` · `substrate-proxy` · `list-substrate-entities`
## Cloning it
### Dashboard
1. Open **Templates** in the [dashboard](https://dashboard.butterbase.ai).
2. Click **butterbase-crm**, then **Clone**.
3. Name your app. The region is fixed to the template's (`us-east-1`) in the dashboard.
4. The env-vars step says **"Nothing to enter"** — every key this app needs is platform-provided. Click straight through.
5. Click **Start clone** and wait. 56 functions take a few minutes to redeploy.
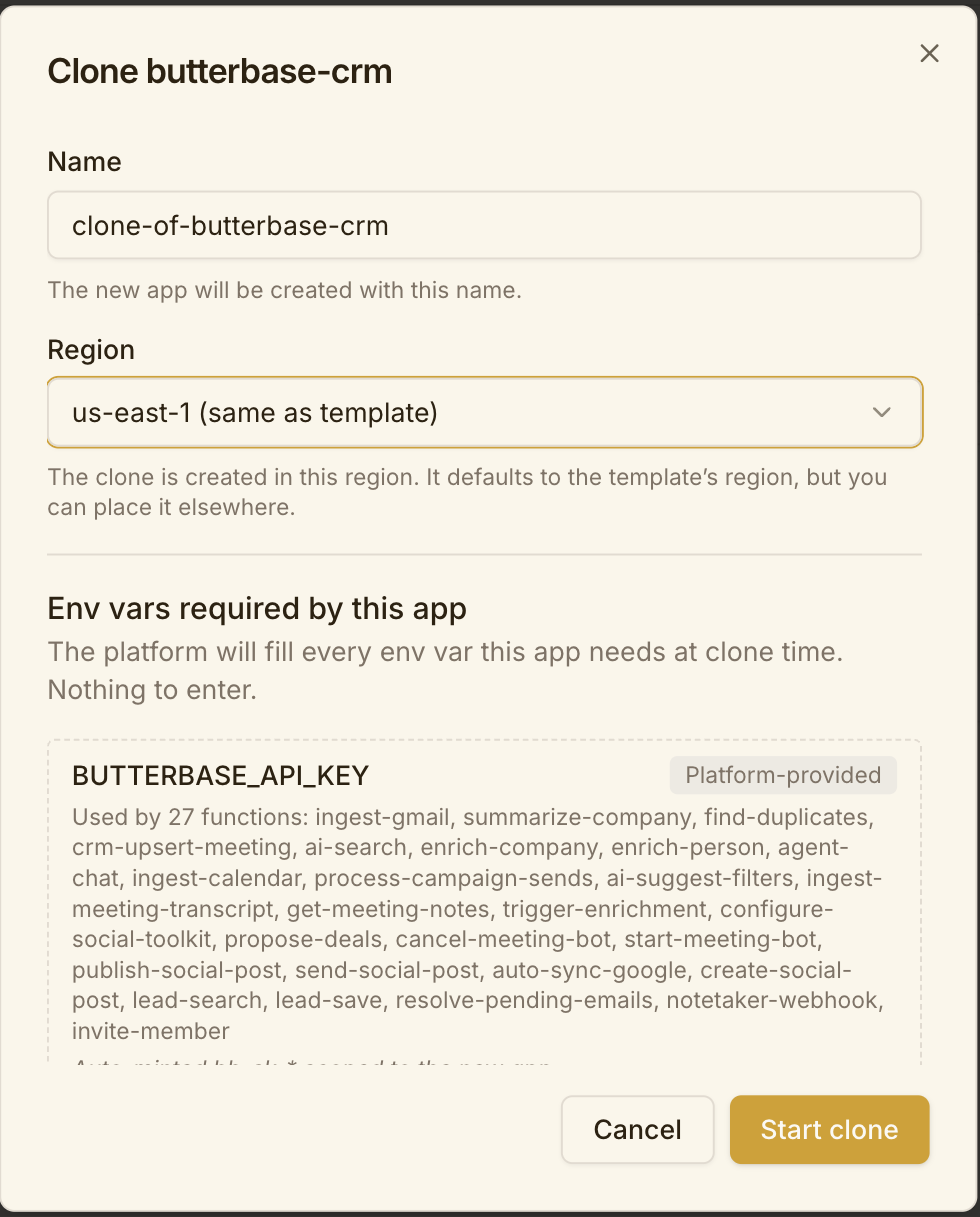
### CLI
```bash
butterbase clone app_44zjayftl7b3 ./my-crm --name "My CRM" --region us-east-1
```
### MCP
```
manage_app action: "clone"
source_app_id: "app_44zjayftl7b3"
name: "My CRM"
region: "us-east-1"
```
Then poll:
```
manage_app action: "get_clone_job", job_id: ""
```
### REST
```json
POST /v1/templates/app_44zjayftl7b3/clone
{ "name": "My CRM", "region": "us-east-1" }
```
## Setting it up after the clone
### 1. Read the clone warnings
```
manage_app action: "get_clone_job", job_id: ""
```
If the meetings webhook was rebuilt, a warning contains a freshly minted `wsec_*` **shown exactly once**. Capture it — it's already wired into `notetaker-webhook`, but you'll want it on record.
### 2. Confirm the auto-filled keys landed
Every function in this template uses only platform-convention keys:
| Key | Used by | Filled with |
|---|---|---|
| `BUTTERBASE_API_KEY` | 27 functions | A fresh `bb_sk_*` scoped to your new app |
| `BUTTERBASE_API_URL` | `ai-suggest-filters`, `lead-search`, `lead-save` | Your control API URL |
| `BUTTERBASE_APP_ID` | `ai-suggest-filters`, `lead-search`, `lead-save`, `configure-social-toolkit` | Your new app id |
| `NOTETAKER_WEBHOOK_SECRET` | `notetaker-webhook` | A minted `wsec_*` |
| `BB_SUBSTRATE_KEY` | `substrate-proxy` | A minted `bb_sk_*` |
Spot-check one:
```
manage_function action: "get", app_id: "", function_name: "agent-chat"
```
### 3. Add Google OAuth credentials
Gmail and Calendar ingest need **your** Google client id and secret — the source's did not transfer.
```
manage_oauth action: "configure"
app_id: ""
provider: "google"
client_id: "..."
client_secret: "..."
redirect_uris: ["https://api.butterbase.ai/auth//oauth/google/callback"]
```
Enable the Gmail and Calendar scopes on the Google side. Until this is done, `ingest-gmail`, `ingest-calendar`, and `auto-sync-google` will run and find nothing.
### 4. Connect the integrations you actually want
Social publishing and comment campaigns run through [Integrations](/core-concepts/integrations/). Register only the platforms you'll use:
```
manage_integrations action: "list_available" # what you can connect
manage_integrations action: "list_connected" # what this app already has
```
The cron jobs (`process-scheduled-social-posts`, `run-comment-discovery`, `fetch-post-replies`) are harmless with nothing connected — they'll no-op.
### 5. Decide about the meetings notetaker
`start-meeting-bot` dispatches a bot into calls. Confirm you're happy with that before pointing it at real meetings, and check the recording-consent rules that apply where you and your participants are.
### 6. Point CORS at your frontend
```
manage_app action: "update_cors"
app_id: ""
allowed_origins: ["https://mycrm.com", "http://localhost:5173"]
```
### 7. Check the frontend
The clone comes up with the CRM frontend **already live**, re-pointed at your app — the overview page shows the URL. Open it and confirm it loads before doing anything else.
To edit it, pull the source locally:
```bash
butterbase repo init
butterbase repo pull
cd && npm install && npm run build
```
Then redeploy — see [Frontend Deployment](/core-concepts/frontend-deployment/). The frontend's `VITE_*` variables are separate from function env vars and are not inherited.
### 8. Review the security posture
56 functions is a large surface. Before real data goes in:
- `manage_app action: "get_config"` — check the access mode.
- Read the RLS policies that came across; see [Row-Level Security](/core-concepts/row-level-security/).
- Note which functions are `http` triggered and reachable, and lock down anything you aren't using.
## Verifying it works
1. `manage_schema action: "get"` — schema is present.
2. `invoke_function` on `ai-search` — a `500` almost always means a missing env var.
3. Sign up a test user through your auth config.
4. Connect one Google account and run `ingest-gmail`.
5. Load the frontend and click through contacts.
## Cost note
This template is AI-heavy — enrichment, summarisation, chat, and search all draw AI credits, and several cron jobs run unattended. Set a [spending cap](/core-concepts/plans-and-usage/#credits-top-ups-and-spending-caps) before you leave it running.
---
## Templates / Butter Support
**App ID:** `app_0ycj4ad7odud` · **Region:** `us-east-1` · **30 functions + a Durable Object** · **19 clones**
An AI support desk. An embeddable widget takes questions, RAG answers them from your own documentation, and an agent handles replies — either drafting for human approval or resolving on its own, depending on how you set its autonomy. Approved patterns get promoted into policies, so the system gets more autonomous as you teach it.
:::danger
**A fresh clone ships at the highest autonomy setting.** Default mode is `AUTO-RESOLVE` — the agent replies and closes tickets on its own judgement, with no human in the loop. Only a few classified issue types (`account_deletion`, `billing`, `cancellation`) are overridden to `ALWAYS ESCALATE`. Read step 5 before you point the widget at real customers.
:::
This is the better of the two templates for seeing [RAG](/core-concepts/rag/), [Durable Objects](/core-concepts/durable-objects/), and [Substrate](/core-concepts/substrate/) working together. It needs a little more configuration than [Butterbase CRM](/templates/butterbase-crm/) — two function keys and six Durable Object keys.
## What's in it
### The embeddable widget
`widget-ingest` · `widget-followup` · `widget-fetch-history` · `rotate-widget-secret`
A drop-in widget for your own site. Questions arrive, follow-ups thread onto the same conversation, and history is retrievable. The widget secret can be rotated without a redeploy.
### Docs ingestion and RAG
`ingest-docs` · `refresh-docs` *(cron)* · `delete-docs-source` · `request-doc-upload-url` · `ai-rag-query`
Point it at your documentation, upload files through a presigned URL, and it chunks and embeds them into a RAG collection. `refresh-docs` re-crawls on a schedule so answers don't go stale.
### AI answering
`ai-chat-completion` · `ask-support-overview`
Chat completion over a ticket's context, plus a whole-queue overview question ("what are people struggling with this week?").
### Agent proposals with human approval
`do-substrate-propose` · `approve-proposal` · `reject-proposal` · `expire-agent-proposals` *(cron)* · `admin-autonomy`
The agent never acts unilaterally. It proposes; a human approves or rejects; stale proposals expire. `admin-autonomy` is the dial that decides how much the agent may do on its own.
### Replies and escalation
`auto-reply-worker` · `send-draft-reply` · `execute-escalation`
Approved drafts go out through the reply worker. Anything the agent can't handle escalates on a defined path.
### Learning from what humans did
`convert-to-policy` · `mark-as-commitment` · `sweep-pattern-signals` *(cron)*
A good resolution can be promoted into a reusable policy. Commitments made to a customer are tracked. The cron sweeper looks for repeated patterns worth codifying.
### Substrate, team, and ops
`substrate-proxy` · `substrate-read-internal` · `sync-ticket-artifact` · `auth-bootstrap-hook` · `invite-teammate` · `remove-teammate` · `fetch-ai-usage` · `cleanup-idempotency-keys` *(cron)*
## Cloning it
### Dashboard
1. Open **Templates** in the [dashboard](https://dashboard.butterbase.ai).
2. Click **butter-support**, then **Clone**.
3. Name your app. The region is fixed to the template's (`us-east-1`) in the dashboard.
4. **The env-vars step asks you for two values** — `SUBSTRATE_OUTBOX_SECRET` and `RAG_COLLECTION`. Fill them now, or leave blank and set them in the function editor later.
5. Click **Start clone**.
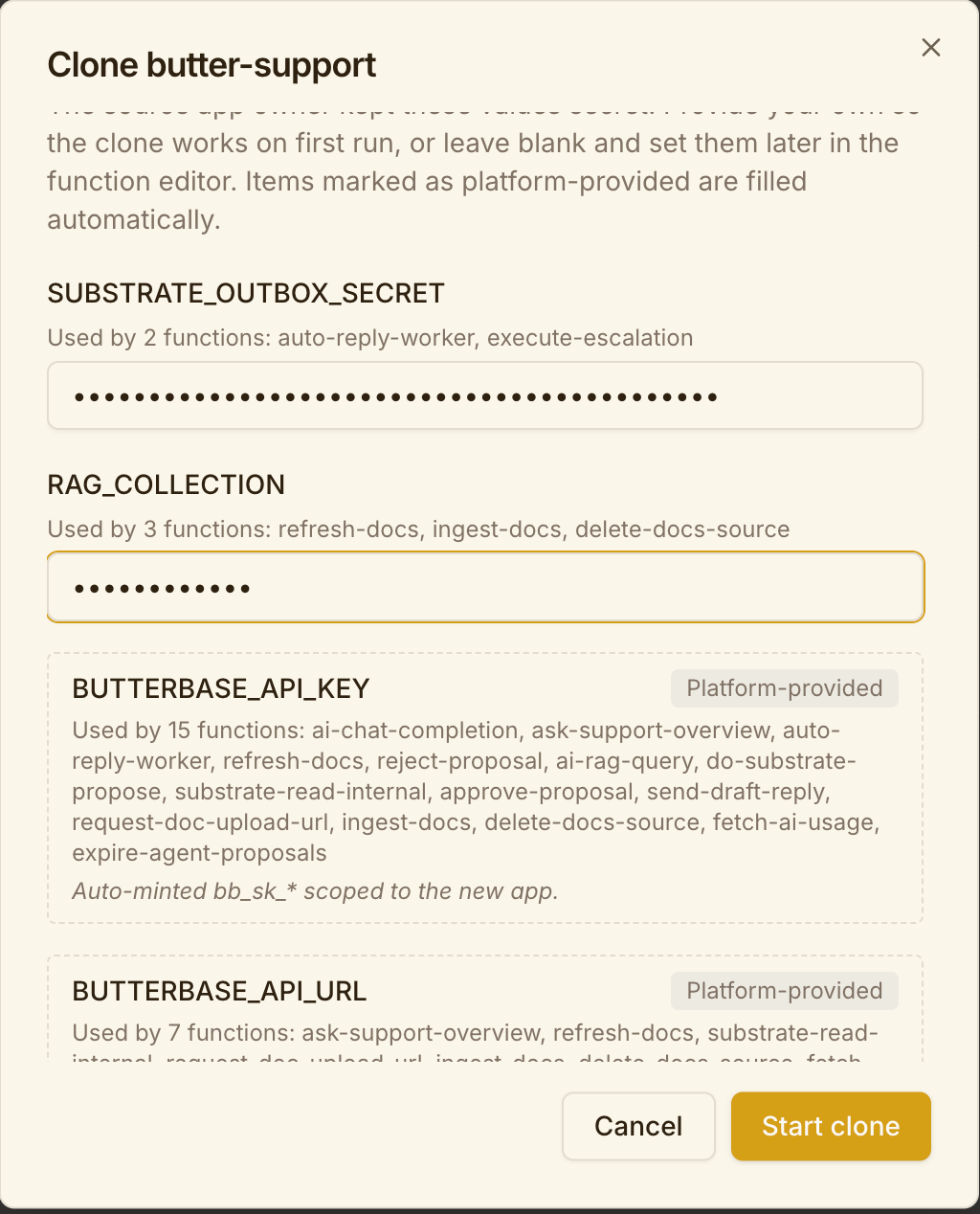
### CLI
```bash
butterbase clone app_0ycj4ad7odud ./my-support --name "My Support Desk"
```
### MCP
Supply the two required keys inline so the functions boot working:
```
manage_app action: "clone"
source_app_id: "app_0ycj4ad7odud"
name: "My Support Desk"
env_var_values: {
"auto-reply-worker": { "SUBSTRATE_OUTBOX_SECRET": "" },
"execute-escalation": { "SUBSTRATE_OUTBOX_SECRET": "" },
"refresh-docs": { "RAG_COLLECTION": "support-docs" },
"ingest-docs": { "RAG_COLLECTION": "support-docs" },
"delete-docs-source": { "RAG_COLLECTION": "support-docs" }
}
```
Check what's still outstanding in the returned `pending_env_vars`.
## Setting it up after the clone
### 1. Fill the two required function keys
Everything else auto-fills. These two do not:
| Key | Functions | What to set it to |
|---|---|---|
| `SUBSTRATE_OUTBOX_SECRET` | `auto-reply-worker`, `execute-escalation` | A strong random secret you generate. **Use the same value in both** — they're two halves of one outbox flow. |
| `RAG_COLLECTION` | `refresh-docs`, `ingest-docs`, `delete-docs-source` | The name of the RAG collection you'll create in step 3. **Must match exactly across all three.** |
```
manage_function action: "update_env"
app_id: ""
function_name: "auto-reply-worker"
env: { "SUBSTRATE_OUTBOX_SECRET": "..." }
```
:::caution
A mismatched `RAG_COLLECTION` across those three functions is the most common way to break this template. Ingest writes to one collection, query reads from another, and answers silently come back empty.
:::
### 2. Re-set the Durable Object environment
The clone arrives with **four of the seven** Durable Object env keys already set. Three are missing and you must add them:
| Key | After the clone | What to set it to |
|---|---|---|
| `BUTTERBASE_API_KEY` | ✅ Present | — |
| `DEFAULT_MODEL` | ✅ Present | — (verify the value suits you) |
| `HAIKU_MODEL` | ✅ Present | — (verify the value suits you) |
| `SUBSTRATE_OUTBOX_SECRET` | ✅ Present | — |
| `BUTTERBASE_API_URL` | ❌ **Missing** | Your control API URL, e.g. `https://api.butterbase.ai` |
| `BUTTERBASE_APP_ID` | ❌ **Missing** | Your new app id |
| `RAG_COLLECTION` | ❌ **Missing** | The same collection name as step 1 |
The three that go missing are exactly the ones that would be *wrong* if copied — two point at the source app, and the third names a RAG collection that doesn't exist in your clone yet.
:::caution
Filling `RAG_COLLECTION` in the clone modal sets it on the **functions**, not on the Durable Objects. You must set the DO copy separately, and it must match. Verified on a real clone: the value supplied at clone time appeared in function env but not in `list_env` for the DOs.
Preflight over-reports here — `preview_clone_env_vars` marks `DEFAULT_MODEL`, `HAIKU_MODEL` and `SUBSTRATE_OUTBOX_SECRET` as `user_required` for Durable Objects, but all three carry across in practice. Trust `list_env` on the finished clone over the preflight.
:::
Check what you actually have before setting anything:
```
manage_durable_objects action: "list_env", app_id: ""
```
One key per call — DO env vars are app-wide, not per-class, so no `name` is needed:
```
manage_durable_objects action: "set_env"
app_id: ""
key: "BUTTERBASE_APP_ID"
value: ""
```
Changing an env var auto-redeploys the active classes. Confirm with `action: "list_env"`.
:::caution
Model ids must be catalog-verified and prefixed. A bare `claude-sonnet-4-5` is not routable — list what's available with `manage_ai action: "list_models"` and copy an id exactly.
:::
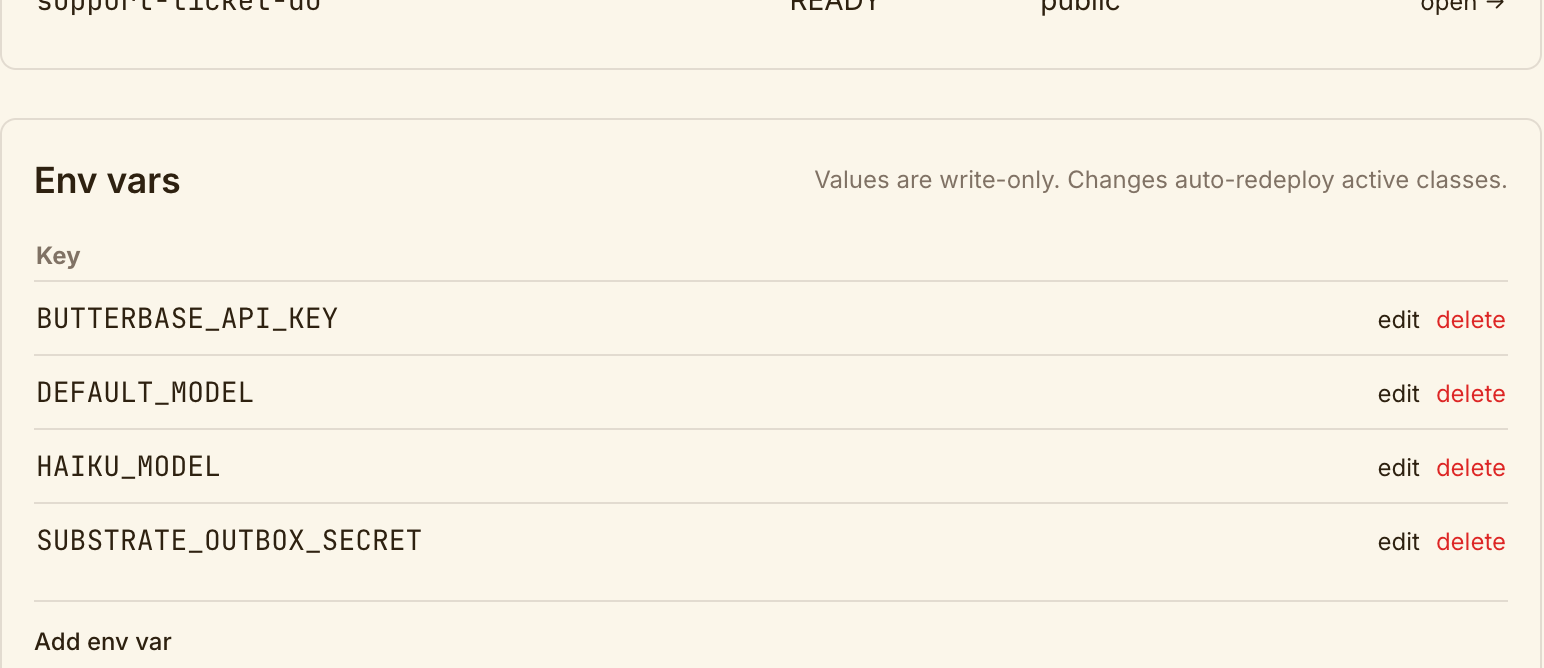
### 3. Create the RAG collection and ingest your docs
```
manage_rag_content action: "create_collection"
app_id: ""
name: "support-docs"
```
The name must match the `RAG_COLLECTION` value from steps 1 and 2. Then point `ingest-docs` at your documentation, or upload files via `request-doc-upload-url`. See [RAG](/core-concepts/rag/).
Until the collection has content, the widget will answer from the model's general knowledge rather than your docs — which looks like it's working but isn't.
### 4. Rebind the auth hook if a warning said so
This template ships `auth-bootstrap-hook`, which runs after login. If the clone couldn't rebind it, the warning will say so:
```
manage_auth_config action: "configure_auth_hook"
app_id: ""
post_auth_function: "auth-bootstrap-hook"
```
### 5. Set the autonomy level deliberately
**Console → Autonomy.** This is the most consequential setting in the template and it does not ship conservative.
| | What the clone arrives with |
|---|---|
| **Default mode** | `AUTO-RESOLVE` — the agent replies and closes tickets when it judges the issue resolved. Highest autonomy, no human in the loop. |
| **Per-issue overrides** | `account_deletion`, `billing`, `cancellation` → `ALWAYS ESCALATE`. These never get an agent reply; they go straight to your escalation target. |
Other modes available per issue type include **Draft for approval**, which is the approval-gated behaviour most people assume is the default. It isn't.
Decide deliberately before any real traffic arrives:
- Set the default to **Draft for approval** while you watch the queue, then raise it once you trust the replies; or
- Keep `AUTO-RESOLVE` and add overrides for every issue type where a wrong answer is expensive.
The override list is driven by the classifier's `issue_type`, so it only protects categories you have actually enumerated. Anything the classifier labels with a type you have not overridden falls through to the default mode.
### 6. Rotate the widget secret
```
invoke_function app_id: "", function_name: "rotate-widget-secret"
```
Do this before embedding the widget anywhere public, so you aren't running on a value derived from the source app.
### 7. Point CORS at the sites hosting the widget
```
manage_app action: "update_cors"
app_id: ""
allowed_origins: ["https://mysite.com", "https://docs.mysite.com"]
```
The widget is cross-origin by design — if CORS is wrong, it silently fails to load.
### 8. Check the frontend
The clone should come up with the Support frontend **already live**, re-pointed at your app. Confirm it loads, then pull the source locally if you want to change it:
```bash
butterbase repo init
butterbase repo pull
```
Redeploy per [Frontend Deployment](/core-concepts/frontend-deployment/).
## Verifying it works
1. `manage_durable_objects action: "list_env"` — all seven keys present.
2. `manage_rag_content action: "list_collections"` — your collection exists and has documents.
3. `invoke_function` on `ai-rag-query` with a question your docs answer — check the response cites your content, not generic knowledge.
4. Submit a question through the widget and confirm a ticket appears in the Inbox. **A fresh clone's inbox is empty** — no seed tickets come across, so the widget is the only way to put something in it.
5. Approve it and confirm the reply actually sends.
## Cost note
RAG ingestion embeds every chunk, `refresh-docs` re-crawls on a cron, and every widget question is a model call. Set a [spending cap](/core-concepts/plans-and-usage/#credits-top-ups-and-spending-caps) and point `HAIKU_MODEL` at something cheap before you open the widget to real traffic.
---
## Templates / Cloning a Template
Cloning has three moves: **find** a template, **preflight** it so you know what it needs, then **clone** and poll until it's done.
## Step 1 — Find a template
### Dashboard
1. Go to [dashboard.butterbase.ai](https://dashboard.butterbase.ai) and open **Templates**.
2. Search by name, or sort by **Recent** / **Popular** (popularity is the clone count).
3. Each card shows the app name, its owner, and its region. The card's only action is **Clone** — the dashboard has no template detail view, so use `GET /v1/templates/{app_id}` (or `find_templates`) if you want the table and function inventory before committing.
### CLI
```bash
butterbase templates
butterbase templates --q blog --sort popular --limit 20
butterbase templates --region us-west-2 --json
```
### MCP
```
manage_app action: "find_templates"
q: "blog"
sort: "popular" # "recent" (default) or "popular"
limit: 10
offset: 0
```
Returns `{ items: [...], total, limit, offset }`.
### REST
```
GET /v1/templates?q=blog&sort=popular&limit=20&offset=0
GET /v1/templates/{app_id}
```
Discovery is anonymous — no credentials needed to browse. The detail endpoint returns the template's table and function inventory, with platform-internal tables filtered out.
:::note
Only apps that are **public** *and* **listed** appear here. A public-but-unlisted app is still clonable if you know its id — that's how publishers share a template privately.
:::
## Step 2 — Preflight
Before you clone, ask the template what it will need from you. This costs nothing and requires no auth for public apps.
```
GET /v1/templates/{source_app_id}/clone-preflight
```
```
manage_app action: "preview_clone_env_vars"
source_app_id: ""
```
```json
{
"functions": [
{
"fn_name": "send-invite",
"keys": ["BUTTERBASE_API_URL", "BUTTERBASE_API_KEY", "RESEND_API_KEY"],
"key_meta": [
{ "key": "BUTTERBASE_API_URL", "status": "auto_filled", "reason": "Platform-resolved at clone time." },
{ "key": "BUTTERBASE_API_KEY", "status": "auto_filled", "reason": "Auto-minted bb_sk_* scoped to the new app." },
{ "key": "RESEND_API_KEY", "status": "user_required" }
]
}
],
"durable_objects": { "env_keys": ["OPENAI_API_KEY"], "key_meta": [ … ] },
"app_env": { "keys": ["FEATURE_FLAGS"], "note": "These app-level env vars are copied to the clone." }
}
```
**Only key names are ever returned. Values never leave the source app.**
| `status` | What it means for you |
|---|---|
| `auto_filled` | Butterbase supplies it. `BUTTERBASE_API_URL` and `BUTTERBASE_APP_ID` are resolved to your new app; `BUTTERBASE_API_KEY` is minted as a fresh `bb_sk_*` scoped to your clone; a meetings webhook secret is minted and wired in if the source had one. |
| `user_required` | A third-party secret you must provide — at clone time via `env_var_values`, or afterwards. |
`durable_objects.env_keys` are **never** carried across, convention keys aside. Plan to re-set them after the clone with `manage_durable_objects action: "set_env"`.
## Step 3 — Clone
### Dashboard
Click **Clone** on the template. The modal asks for a name, runs the preflight, and shows an env-vars step where you can fill in each `user_required` key before starting. Progress is shown live; you land on the new app's overview when it completes.
:::note
The dashboard pins the clone to the **template's own region** and disables the field. To place a clone in a different region, use the CLI, MCP, or REST paths below — they accept `dest_region`.
:::
### CLI
```bash
butterbase clone ./my-clone --name "My App" --region us-west-2
```
This creates the app, pulls the source's latest repo snapshot into `./my-clone/`, and rewrites `.butterbase/config.json` with the new app id. Both `--name` and `--region` are optional; omit the region and the clone inherits the source's.
### MCP
```
manage_app action: "clone"
source_app_id: ""
name: "My App"
region: "us-west-2"
env_var_values: { "send-invite": { "RESEND_API_KEY": "re_..." } }
auto_mint_api_key: [ { "fn_name": "send-invite", "key": "BUTTERBASE_API_KEY" } ]
```
Returns `{ job_id, status, pending_env_vars }`. `pending_env_vars` is the per-function map of keys still needing values — an empty object means you're fully configured.
:::note
If your requested region was closed and the clone got redirected, the **POST response** carries `dest_region`, `dest_region_redirected_from`, and a ready-made `notice` string. These are **not** on the clone job — `GET /v1/clone-jobs/{job_id}` returns no region fields at all, so capture them when you start the clone, not while polling.
:::
### REST
```json
POST /v1/templates/{source_app_id}/clone
Authorization: Bearer {token}
{
"name": "My App",
"region": "us-west-2",
"organization_id": "",
"env_var_values": { "send-invite": { "RESEND_API_KEY": "re_..." } },
"auto_mint_api_key": [ { "fn_name": "send-invite", "key": "BUTTERBASE_API_KEY" } ]
}
```
| Field | Notes |
|---|---|
| `name` | Optional. Globally unique across Butterbase — a collision returns `409`. Omit it and you get `Clone of {source}`. |
| `dest_region` | Optional (`region` is accepted as a legacy alias). Defaults to the source's region. If the region you ask for is temporarily closed to new apps, the clone is **redirected to an open one** rather than failing. See [Regions](/core-concepts/regions/). |
| `organization_id` | Optional. Must be an org you belong to. Defaults to the org bound to your credentials, then your personal org. |
| `env_var_values` | `{ fn_name: { KEY: "value" } }`. Values are stored encrypted against the new app. |
| `auto_mint_api_key` | `[{ fn_name, key }]` — mint a scoped `bb_sk_*` for that key instead of supplying one. |
## Step 4 — Poll the job
```
GET /v1/clone-jobs/{job_id}
```
```
manage_app action: "get_clone_job", job_id: ""
```
```json
{
"job_id": "…",
"status": "replaying_functions",
"source_app_id": "app_src",
"dest_app_id": null,
"retry_count": 0,
"error_message": null,
"warnings": [],
"unfilled_env_vars": { "send-invite": ["RESEND_API_KEY"] },
"created_at": "…",
"completed_at": null
}
```
`status` walks through `pending` → `processing` → `replaying_schema` → `replaying_rls` → `replaying_durable_objects` → `replaying_functions` → `replaying_config` → `copying_repo` → `seeding_data` → `completed`.
`dest_app_id` is populated once the app exists. Only the requester can read their own job.
**If it fails:**
```
POST /v1/clone-jobs/{job_id}/retry
```
Read `error_message` first — a retry re-runs the same pipeline, so a genuine configuration problem will fail the same way twice.
## Step 5 — Read the warnings
A `completed` job can still carry `warnings[]`. These are soft failures the pipeline worked around rather than aborted on. Common ones:
- The source's `auth_hook_function` pointed at a function that couldn't be replayed — the binding is left `NULL`.
- A config value referenced a secret that belongs to the source owner and wasn't copied.
- A meetings webhook secret was minted — the warning contains the `wsec_*` **once**, so capture it.
**The dashboard does not show warnings.** Its clone flow drops you on the new app's overview with no warnings panel, even with `?cloneJob=` in the URL — so a dashboard-only clone can silently lose a one-time secret. Read them over the API or MCP instead:
```
manage_app action: "get_clone_job", job_id: ""
```
```
GET /v1/clone-jobs/{job_id}
```
Do this after every dashboard clone, not just failed ones.
## Errors
| Code | HTTP | Meaning | Fix |
|---|---|---|---|
| `RESOURCE_NOT_FOUND` | 404 | Source doesn't exist or isn't public | Check the app id; ask the owner to make it public |
| `VALIDATION_INVALID_SCHEMA` | 400 | Source has no repo snapshot | The owner must run `butterbase repo push` at least once |
| `VALIDATION_INVALID_SCHEMA` | 409 | App name already taken | Pick a different `name` |
| `CLONE_LIMIT_INFLIGHT` | 429 | 3 clones already in progress | Wait for one to finish |
| rate limited | 429 | More than 5 clones started this hour | Wait |
| project limit | 403 | Destination org is at its app quota | Delete an app or upgrade — see [Plans & Usage](/core-concepts/plans-and-usage/) |
## Next
Your clone is running but it isn't finished. Work through **[Configuring Your Clone](/templates/configure/)**.
---
## Templates / Configuring Your Clone
A finished clone is a working backend, not a finished product. Everything the source owner held as a secret, and everything tied to their identity or billing, stopped at the boundary. This page is the list of what you now have to supply.
## What transferred
| | |
|---|---|
| **Schema** | Tables, columns, types, indexes |
| **Security** | Row-level security policies, access mode |
| **Functions** | Function code, deployed to your app |
| **Durable Objects** | Class definitions, redeployed on your namespace |
| **Repo** | The source's latest pushed snapshot |
| **Config** | Storage settings, CORS allowed origins, OAuth provider list and redirect URLs, AI model defaults |
| **App env vars** | App-level environment variables, values included |
| **Seed data** | Rows in tables the publisher marked `_seed: true` |
| **Frontend** | The source's most recent published frontend, with the source app id rewritten to yours so it calls your backend |
## What did not transfer
| | Why |
|---|---|
| End-user accounts and sessions | They belong to the source app's users |
| OAuth **client secrets** | The source owner's credentials |
| Function environment variable **values** | Secrets — you got the key names, not the values |
| Durable Object env values | App-scoped secrets; never copied |
| BYOK AI provider keys | The source owner's billing |
| [Custom domains](/core-concepts/custom-domains/) | Tied to DNS you don't control |
| Stripe Connect / plans / products | The source owner's Stripe account |
| Invocation history, audit logs | Not yours |
## The checklist
### 1. Read the clone job's warnings
```
manage_app action: "get_clone_job", job_id: ""
```
Do this first. Warnings tell you what the pipeline couldn't reproduce — most importantly a **broken auth hook binding** (left `NULL`) and any **minted webhook secret**, which is shown exactly once.
### 2. Fill in the remaining function env vars
Preflight told you which keys were `user_required`. Anything you didn't pass at clone time is still empty, and the function will fail at runtime rather than at deploy time.
```
manage_function action: "update_env"
app_id: ""
function_name: "send-invite"
env: { "RESEND_API_KEY": "re_..." }
```
You can also set them in **App → Functions → *function* → Environment** in the dashboard.
Check what's still missing with `unfilled_env_vars` on the clone job, or with `manage_function action: "get"` on each function.
### 3. Re-set Durable Object env vars
DO environment values are never carried across a clone. Every non-convention key must be re-set:
```
manage_durable_objects action: "set_env"
app_id: ""
name: ""
key: "OPENAI_API_KEY"
value: "sk-..."
```
One key per call — repeat for each. `action: "list_env"` shows which keys exist.
### 4. Add your own OAuth client credentials
The provider *list* and redirect URLs copied; the client id/secret pairs did not. For each provider the template used, register an app with that provider and configure it:
```
manage_oauth action: "configure"
app_id: ""
provider: "google"
client_id: "..."
client_secret: "..."
redirect_uris: ["https://api.butterbase.ai/auth//oauth/google/callback"]
```
Update the redirect URLs to point at **your** domains — the copied ones point at the source app's. See [Authentication](/core-concepts/authentication/).
### 5. Rebind the auth hook if the warning said so
If a warning reported the auth hook couldn't be bound, set it once the function exists:
```
manage_auth_config action: "configure_auth_hook", app_id: "", post_auth_function: ""
```
### 6. Add AI keys, if the template uses AI
The clone inherits the source's model defaults but not their BYOK keys. Either let it run on your Butterbase AI credits, or add your own keys:
```
manage_ai action: "update_config", app_id: "", config: { byokKey: "sk-ant-..." }
```
See [AI Integration](/core-concepts/ai-integration/).
### 7. Update CORS for your frontend
The copied `allowed_origins` list points at the source's domains. Replace it:
```
manage_app action: "update_cors"
app_id: ""
allowed_origins: ["https://myapp.com", "http://localhost:5173"]
```
### 8. Check the frontend
Clones usually come up with a **live frontend already serving**. Step 7 of the clone pipeline republishes the source's most recent frontend artifact and rewrites the source app id inside it to yours, so it talks to your backend rather than the template's. Your app overview shows the URL.
Two cases need your attention:
- **No frontend deployed.** The source never published one, or the replay failed — replay is best-effort and logs a warning rather than failing the clone. Build and deploy your own; see [Frontend Deployment](/core-concepts/frontend-deployment/).
- **A warning says the artifact had no occurrences of the source app id.** The rewrite couldn't find anything to change, so the cloned frontend **may still be pointed at the source app**. Redeploy from your own build before putting any data in.
Frontend build env vars (`VITE_*` / `NEXT_PUBLIC_*`) are separate from function env vars and are not inherited — set them on your app and redeploy if the frontend needs them.
### 9. Add a custom domain
Optional, and only on Launch or above. See [Custom Domains](/core-concepts/custom-domains/).
### 10. Set up charging, if you're selling
Stripe Connect does not transfer. If the template ships a paywall, plans, or products, you need your own Connect account and your own plan/product rows. See [Charging Your Users](/core-concepts/billing/).
### 11. Review the security posture before you go live
Never assume an inherited configuration is safe for your use case.
- Check the app's access mode: `manage_app action: "get_config"`.
- Read every RLS policy that came across — [Row-Level Security](/core-concepts/row-level-security/) has a debugging guide.
- Confirm no seed row contains data you don't want to ship.
- If the template was built for a demo, it may be deliberately permissive.
### 12. Bind your local checkout
If you cloned from the dashboard or MCP and want the files locally:
```bash
butterbase repo init
butterbase repo pull
```
The CLI's `butterbase clone` already did this for you.
## Verifying the clone works
1. `manage_schema action: "get"` — the expected tables exist.
2. `select_rows` on a seeded table — seed data landed.
3. `invoke_function` on each function — a `500` here is almost always a missing env var.
4. Sign up a test end user through your auth config.
5. Deploy the frontend and click through the primary flow.
:::caution
A function's `status` field can read `error` from a deploy attempt that has since been superseded. Invoke the function before you trust the status.
:::
---
## Templates / Publishing a Template
Any app you own becomes a template the moment you make it public and push a repo snapshot. There's no submission, no review queue, and no separate template object — the app *is* the template.
## Why publish
- **Distribution.** Listed templates show up in the dashboard's Templates browser and in `find_templates` for every AI agent connected to Butterbase.
- **A clone counter.** Every clone increments your app's `fork_count`, which is what "Popular" sorts on.
- **Onboarding that actually works.** Instead of a README telling someone to create eight resources by hand, they click Clone and have a running copy.
- **A hook into the moment someone clones.** Fire a webhook on every completed clone — greet the new owner, count adoption, trigger provisioning on your side.
## Requirements
| Requirement | Why |
|---|---|
| `visibility: public` | Clone refuses non-public sources with a `404` |
| At least one `butterbase repo push` | Clone refuses a source with no repo snapshot — that snapshot *is* the code that gets copied |
| `listed: true` (optional) | Controls discoverability, not clonability — see below |
| App is fully provisioned | Un-provisioned apps are filtered out of discovery |
## Step 1 — Prepare the app for other people
Do this before you flip visibility. Once the app is public, its schema, function code, repo files, and env var **key names** are readable by anyone.
- **Audit what's in your tables.** Only tables marked `_seed: true` get their rows copied, but the *schema* of every table is public. Don't ship column names that leak anything.
- **Audit your repo snapshot.** Whatever `butterbase repo push` uploaded is what people download. Check for committed `.env` files, fixture data with real customer records, hardcoded keys in source. Use the ignore rules — see [`butterbase repo`](/cli/repo/).
- **Audit your env var names.** Values never leave, but names are part of the public surface. `ACME_CORP_INTERNAL_TOKEN` tells a story.
- **Audit your RLS policies.** They copy verbatim. If your app is permissive because it's a demo, every clone inherits that. Consider tightening first — see [Row-Level Security](/core-concepts/row-level-security/).
- **Make sure it works from cold.** Clone your own app into a scratch app and run through it. That is the experience you're shipping.
## Step 2 — Add seed data
An empty app is a bad first impression. Mark a table with `_seed: true` in your schema and its rows travel with the clone:
```json
{
"tables": {
"categories": {
"_seed": true,
"id": "uuid primary key",
"name": "text not null"
}
}
}
```
Tables without `_seed: true` clone with their schema only. Use this for reference data, example content, and demo rows — not for anything user-specific. See [Database & Schema](/core-concepts/database/#marking-tables-as-seed-data).
## Step 3 — Push your repo snapshot
```bash
butterbase repo init # once, binds the folder
butterbase repo push --message "Template release"
```
Pushes are content-addressed, so re-pushing is cheap. The **latest** snapshot is what clones copy — push again whenever you want new cloners to get updated code. Existing clones are unaffected; they took a copy.
## Step 4 — Make it public
**CLI:**
```bash
butterbase visibility public --listed
butterbase visibility public --unlisted
butterbase visibility private
```
**MCP:**
```
manage_app action: "set_visibility"
app_id: ""
visibility: "public"
listed: true
```
**REST:**
```json
PATCH /v1/{app_id}/config/visibility
{ "visibility": "public", "listed": true }
```
**Dashboard:** **App → Settings → Visibility.**
### `public` vs `listed`
| `visibility` | `listed` | Result |
|---|---|---|
| `private` | — | Not clonable at all |
| `public` | `true` | Clonable, **and** appears in the Templates browser and `find_templates` |
| `public` | `false` | Clonable by anyone who has the app id, but **not** discoverable |
`public` + `listed: false` is the "share this with my team / my course / my client" mode: send the app id to whoever needs it and nobody else can find it.
:::caution
Public means public. There is no per-user allowlist — an unlisted app id is a secret URL, not an access control.
:::
## Step 5 — Set a clone webhook (optional)
Get an HTTP callback whenever someone finishes cloning your app.
**MCP:**
```
manage_app action: "set_clone_webhook"
app_id: ""
webhook_url: "https://example.com/hooks/butterbase-clone"
webhook_secret: "<16-256 chars>"
```
**REST:**
```json
PATCH /v1/{app_id}/config/clone-webhook
{ "webhook_url": "https://example.com/hooks/clone", "webhook_secret": "…" }
```
Clear it with `{ "clear": true }`, or `clear_webhook: true` over MCP.
**The delivery:**
```
POST https://example.com/hooks/clone
Content-Type: application/json
X-Butterbase-Event: clone_completed
X-Butterbase-Signature: sha256=
{
"event": "clone_completed",
"job_id": "…",
"source_app_id": "app_yours",
"dest_app_id": "app_theirs",
"dest_region": "us-west-2",
"completed_at": "2026-08-26T12:00:00.000Z"
}
```
**Verify the signature.** It's HMAC-SHA256 of the raw request body, keyed with your secret, formatted `sha256=`:
```typescript
import { createHmac, timingSafeEqual } from 'node:crypto';
function verify(rawBody: string, header: string, secret: string) {
const expected = `sha256=${createHmac('sha256', secret).update(rawBody).digest('hex')}`;
const a = Buffer.from(expected), b = Buffer.from(header);
return a.length === b.length && timingSafeEqual(a, b);
}
```
Compute it over the **raw** body, not a re-serialized object. Return a `2xx` — non-2xx responses are retried with backoff and then dropped.
## Maintaining a template
**Publishing an update:** push a new repo snapshot and apply any schema migration to your app. New clones pick up the current state; existing clones don't change. There is no upgrade path from a template to its clones — a clone is a fork, not a subscription.
**Unpublishing:** set `visibility: private`. Existing clones keep working; they've been independent since the moment they completed.
**Versioning:** if you need a v1 and a v2 that both stay clonable, keep them as two apps. `repo` retains only the five most recent snapshots, and clones always take the latest.
## Checklist before you flip the switch
- [ ] No secrets, real customer data, or `.env` files in the repo snapshot
- [ ] Env var names give nothing away
- [ ] RLS policies are safe as a default for someone else's app
- [ ] Seed data is representative and contains nothing private
- [ ] You cloned it yourself and the clone actually runs
- [ ] A README in the repo explains what to configure post-clone
- [ ] `listed` set the way you want — discoverable, or id-only
---
## SDKs & Tools / TypeScript SDK
The official TypeScript SDK for Butterbase. Works in browser, Node.js, and Deno environments.
## Installation
```bash
npm install @butterbase/sdk
```
## Quick start
```typescript
import { createClient } from '@butterbase/sdk';
const butterbase = createClient({
appId: 'app_abc123',
apiUrl: 'https://api.butterbase.ai',
anonKey: 'your-anon-key' // Optional, for public access
});
```
The `apiUrl` is the same regardless of which [region](/core-concepts/regions/) your app lives in. Requests are routed to the right region for you, so you don't need to change anything when you move an app.
## Data operations
### Query
```typescript
const { data, error } = await butterbase
.from('posts')
.select('*')
.eq('status', 'published')
.order('created_at', { ascending: false })
.limit(10);
```
### Insert
```typescript
const { data, error } = await butterbase
.from('posts')
.insert({ title: 'Hello World', content: 'My first post' });
```
### Update
```typescript
const { data, error } = await butterbase
.from('posts')
.update({ status: 'archived' })
.eq('id', '123');
```
### Delete
```typescript
const { data, error } = await butterbase
.from('posts')
.delete()
.eq('id', '123');
```
## Query operators
| Method | SQL Equivalent |
|--------|---------------|
| `eq(column, value)` | `=` |
| `neq(column, value)` | `!=` |
| `gt(column, value)` | `>` |
| `gte(column, value)` | `>=` |
| `lt(column, value)` | `<` |
| `lte(column, value)` | `<=` |
| `like(column, pattern)` | `LIKE` (case-sensitive) |
| `ilike(column, pattern)` | `ILIKE` (case-insensitive) |
| `in(column, values)` | `IN (...)` |
| `is(column, value)` | `IS NULL / TRUE / FALSE` |
## Query modifiers
| Method | Description |
|--------|-------------|
| `select(columns)` | Select specific columns |
| `order(column, options)` | Order results |
| `limit(count)` | Limit results |
| `offset(count)` | Skip results |
## Authentication
Sessions are automatically persisted to `localStorage` and restored on page refresh. Access tokens are automatically refreshed before they expire.
```typescript
// Sign up
const { data, error } = await butterbase.auth.signUp({
email: 'user@example.com',
password: 'secure123'
});
// Sign in
const { data, error } = await butterbase.auth.signIn({
email: 'user@example.com',
password: 'secure123'
});
// Get current user
const { data: user } = await butterbase.auth.getUser();
// Sign out
await butterbase.auth.signOut();
// Refresh session manually
const { data } = await butterbase.auth.refreshSession();
// OAuth
const { url } = butterbase.auth.signInWithOAuth({
provider: 'google',
redirectTo: 'http://localhost:3000/callback'
});
window.location.href = url;
```
### Magic-link sign-in
```typescript
// Send a 6-digit code by email. Same response whether or not the email exists.
await butterbase.auth.sendMagicLink('user@example.com');
// Exchange the code for tokens. New users are auto-created on first verify.
const { data, error } = await butterbase.auth.verifyMagicLink('user@example.com', '123456');
if (data) {
// data.access_token, data.refresh_token, data.user
}
```
Codes are 6 digits, expire after 15 minutes, and are single-use. See the [magic-link concept page](/core-concepts/authentication#magic-link-sign-in) for behavior details.
## Auth state changes
```typescript
const { unsubscribe } = butterbase.onAuthStateChange((event, session) => {
// event: 'SIGNED_IN' | 'SIGNED_OUT' | 'TOKEN_REFRESHED' | 'SESSION_RESTORED'
console.log(event, session?.user);
});
```
## Custom session storage
```typescript
// Disable persistence
const butterbase = createClient({
appId: 'app_abc123',
apiUrl: 'https://api.butterbase.ai',
persistSession: false,
});
// Custom adapter (e.g. React Native)
const butterbase = createClient({
appId: 'app_abc123',
apiUrl: 'https://api.butterbase.ai',
sessionStorage: myCustomStorage, // implements { getItem, setItem, removeItem }
});
```
## Storage
```typescript
const { data, error } = await butterbase.storage.upload(file);
const { data } = await butterbase.storage.getDownloadUrl(objectId);
const { data: objects } = await butterbase.storage.list();
await butterbase.storage.delete(objectId);
```
## Functions
```typescript
const { data, error } = await butterbase.functions.invoke('my-function', {
body: { key: 'value' },
method: 'POST'
});
```
## Substrate stream
Subscribe to live [substrate](/core-concepts/substrate/) changes over a WebSocket. `bb.substrate.stream` opens the connection, reconnects with backoff, and delivers one callback per change. Frames are envelope-only (`{ org, op, tbl, id }`) — re-fetch the affected row by `id`.
```typescript
const sub = butterbase.substrate.stream({
token: process.env.BUTTERBASE_SUBSTRATE_KEY, // bb_sub_… or bb_sk_…
onChange: (evt) => {
// evt: { org, op: 'insert' | 'update' | 'delete', tbl, id }
if (evt.tbl === 'entities') refetchEntity(evt.id);
},
onStatus: (s) => console.log(s), // 'connecting' | 'open' | 'closed'
});
// stop listening
sub.unsubscribe();
```
Provide **either** `token` (a substrate-scoped key, for server/script clients) **or** `ticket` (a one-shot `wst_…` minted for a browser — see [Stream live updates to a UI](/core-concepts/substrate/#8-stream-live-updates-to-a-ui)). The stream is org-scoped to the credential.
## Integrations
Connect end-user accounts (Gmail, Slack, GitHub, etc.) and execute tools on their behalf. See the [integrations concept page](/core-concepts/integrations) for the platform model.
```typescript
// Admin: enable a toolkit for the app (requires API key)
await butterbase.integrations.configure('gmail');
// Browse the catalog
const { data: list } = await butterbase.integrations.listAvailable({ search: 'crm' });
// End-user: generate the OAuth connect URL, then redirect the user
const { data: connect } = await butterbase.integrations.connect('gmail', {
redirectUrl: 'https://app.example.com/integrations/callback',
});
window.location.href = connect.authUrl;
// End-user: list their connected accounts
const { data: connections } = await butterbase.integrations.listConnections();
// Execute a tool with the calling user's credentials
const { data: result } = await butterbase.integrations.execute('GMAIL_SEND_EMAIL', {
to: 'user@example.com',
subject: 'Hi',
body: 'Hello',
});
// Service-level execution on behalf of a specific user (API key required)
await butterbase.integrations.asUser(userId).execute('GMAIL_SEND_EMAIL', {
to: 'user@example.com', subject: 'Hi', body: 'Hello'
});
```
## Admin client
`butterbase.admin` exposes platform-management surfaces normally driven from the dashboard, MCP tools, or CLI. Methods on `admin.*` require an API key (`bb_sk_...`).
| Subclient | Manages |
|-----------|---------|
| `admin.schema` | Get/apply/dry-run schema, list migrations |
| `admin.rls` | Enable RLS, create policies, user-isolation shortcut |
| `admin.oauth` | OAuth provider configuration (Google, GitHub, etc.) |
| `admin.config` | App config (CORS, JWT TTL, storage public-read) |
| `admin.functions` | Deploy / list / inspect / log / env-update / delete functions |
| `admin.frontend` | Frontend deployments and build env vars |
| `admin.realtime` | Toggle realtime on tables |
| `admin.domains` | Custom domains lifecycle |
| `admin.apiKeys` | Generate / list / revoke keys |
| `admin.auditLogs` | Query auth/audit events |
### Custom domains
```typescript
// Add a domain — response includes the CNAME target you have to set up
const { data: result } = await butterbase.admin.domains.add('app.example.com');
// result.cname_target → set as a CNAME at your DNS provider (DNS-only if Cloudflare)
// Poll status until ssl_status === 'active'
const { data: status } = await butterbase.admin.domains.getStatus(result.domain.id);
// Re-trigger verification after fixing DNS
await butterbase.admin.domains.verify(result.domain.id);
// Remove
await butterbase.admin.domains.remove(result.domain.id);
```
### App config
```typescript
const { data: cfg } = await butterbase.admin.config.get();
await butterbase.admin.config.updateCors({
allowed_origins: ['https://app.example.com'],
});
await butterbase.admin.config.updateJwt({ token_ttl: 3600 });
// Make all storage objects publicly readable across the app
await butterbase.admin.config.updateStorage({ publicReadEnabled: true });
```
### RLS
```typescript
await butterbase.admin.rls.enable('posts');
await butterbase.admin.rls.createUserIsolation('posts', 'author_id');
await butterbase.admin.rls.createPolicy({
table_name: 'posts',
policy_name: 'public_read_published',
command: 'SELECT',
role: 'anon',
using_expression: 'is_published = true',
});
```
## TypeScript support
All methods return `ButterbaseResponse` with proper type inference:
```typescript
interface Post {
id: string;
title: string;
content: string;
status: 'draft' | 'published';
}
const { data, error } = await butterbase
.from('posts')
.select('*')
.eq('status', 'published');
// data is typed as Post[] | null
```
## Deno usage
```typescript
import { createClient } from 'npm:@butterbase/sdk';
const butterbase = createClient({
appId: Deno.env.get('BUTTERBASE_APP_ID')!,
apiUrl: Deno.env.get('BUTTERBASE_API_URL')!,
});
```
## KV (ctx.kv)
Access the KV store from functions and client-side code. All methods are asynchronous.
| Method | Signature | Description |
|--------|-----------|-------------|
| `get` | `get(key: string, opts?: { touch?: boolean }): Promise` | Retrieve a value by key; returns null if not found |
| `set` | `set(key: string, value: unknown, opts?: { ttl?: number \| null; ephemeral?: boolean }): Promise` | Set a key to a value with optional TTL (seconds) |
| `del` | `del(key: string): Promise` | Delete a key; returns number of keys deleted |
| `incr` | `incr(key: string, by?: number): Promise` | Increment a numeric value (default by 1) |
| `decr` | `decr(key: string, by?: number): Promise` | Decrement a numeric value (default by 1) |
| `setnx` | `setnx(key: string, value: unknown, opts?: { ttl?: number \| null; ephemeral?: boolean }): Promise` | Set only if key does not exist; returns true if set |
| `setex` | `setex(key: string, value: unknown, ttl: number, opts?: { ephemeral?: boolean }): Promise` | Set a value with explicit TTL (shorthand for set + ttl) |
| `cas` | `cas(key: string, expected: unknown, next: unknown): Promise` | Compare-and-swap: atomically set next only if current equals expected |
| `exists` | `exists(key: string): Promise` | Check if a key exists |
| `ttl` | `ttl(key: string): Promise` | Get remaining TTL in seconds; null means no expiry, undefined means key not found |
| `expire` | `expire(key: string, ttl: number \| null): Promise` | Set or clear TTL on an existing key |
| `mget` | `mget(keys: string[]): Promise<(T \| null)[]>` | Get multiple keys at once; returns array with nulls for missing keys |
| `mset` | `mset(entries: Record, opts?: { ttl?: number \| null }): Promise` | Set multiple key-value pairs (applies ttl to all) |
| `expose` | `expose(pattern: string, opts: { read: Role; write: Role }): Promise` | Configure role-based access to a key pattern |
| `unexpose` | `unexpose(pattern: string): Promise` | Remove an exposure rule; returns number of rules deleted |
| `listRules` | `listRules(): Promise>` | List all active exposure rules |
### Client-side example
```typescript
const { data } = await butterbase.from('users').select('id').eq('id', userId);
const userId = data?.[0]?.id;
// Increment a counter in KV
const count = await butterbase.kv.incr(`user_clicks:${userId}`);
console.log(`User has clicked ${count} times`);
// Set with TTL
await butterbase.kv.set(`session:${sessionId}`, sessionData, { ttl: 3600 });
```
### Function example
```typescript
export async function handler(req: Request, ctx: FunctionContext) {
const key = 'request_count';
const count = await ctx.kv.incr(key);
// Set up role-based access (admin only)
if (ctx.user?.role === 'admin') {
await ctx.kv.expose('secret:*', { read: 'owner', write: 'owner' });
}
return new Response(JSON.stringify({ count }));
}
```
**Read with sliding TTL refresh:**
```ts
// Each read refreshes the TTL back to the original window
const session = await ctx.kv.get(`session:${id}`, { touch: true });
```
**Batch reads and writes:**
```ts
await ctx.kv.mset({
'feature:new-checkout': 'on',
'feature:new-pricing': 'off',
});
const flags = await ctx.kv.mget(['feature:new-checkout', 'feature:new-pricing']);
// flags === ['on', 'off'] (null for any missing key)
```
**Ephemeral cache write (smaller, faster, not durable across regional restarts):**
```ts
await ctx.kv.set(`cache:user:${id}`, payload, { ttl: 60, ephemeral: true });
```
## Migration from 0.x to 1.0
The `authUrl` parameter has been removed. All auth endpoints now run on the same URL as the API — just use `apiUrl`.
---
## SDKs & Tools / CLI
The `@butterbase/cli` provides a command-line interface for managing your Butterbase apps, schemas, functions, storage, and deployments.
## Installation
```bash
npm install -g @butterbase/cli
```
## Quick start
```bash
# Login with your API key
butterbase login
# Create a new app
butterbase apps create my-app
# Set as current app
butterbase apps use app_abc123
# Get current schema
butterbase schema get --output schema.json
# Apply schema changes
butterbase schema apply schema.json
# Deploy a function
butterbase functions deploy ./functions/hello.ts
# Upload a file
butterbase storage upload ./image.png
```
## Project init
```bash
# Scaffold a new project (prompts for name, template, optional app ID)
butterbase init
# Specify the template directly
butterbase init react-vite
```
The current supported template is `react-vite`. The command writes the project, copies a `.env` if a template `.env.example` exists, and prints follow-up steps (`cd`, `npm install`, `npm run dev`) plus MCP / agent setup instructions.
## Authentication
```bash
butterbase login
butterbase logout
```
## Configuration
```bash
# Show current config
butterbase config get
# Set endpoint
butterbase config set endpoint https://api.butterbase.ai
# Set API key
butterbase config set apiKey bb_sk_...
```
Configuration is stored in `~/.butterbase/config.json`. Project-level config in `.butterbase/config.json` takes precedence.
## Apps
```bash
butterbase apps list
butterbase apps create my-app
butterbase apps use app_abc123
butterbase apps delete app_abc123
```
Region selection at app creation and app moves are currently available via [MCP](/getting-started/mcp-setup/) tools (`init_app`, `list_regions`, `manage_app` with action `"move"` or `"move_status"`) and the [REST API](/api-reference/platform-api/#apps--regions). See [Regions](/core-concepts/regions/) for guidance.
## Schema
```bash
# Get current schema
butterbase schema get
# Save to file
butterbase schema get --output schema.json
# Preview changes (dry-run)
butterbase schema apply schema.json --dry-run
# Apply changes
butterbase schema apply schema.json
# Apply with custom migration name
butterbase schema apply schema.json --name "add_users_table"
# Use specific app
butterbase schema get --app app_abc123
```
## Functions
```bash
# List deployed functions (also prints trigger types and 🤖 marker if exposed as agent tool)
butterbase functions list
# Deploy function
butterbase functions deploy ./functions/hello.ts
# Deploy with custom name
butterbase functions deploy ./functions/hello.ts --name my-function
# Deploy cron function
butterbase functions deploy ./functions/cleanup.ts \
--trigger cron \
--trigger-config '{"schedule":"*/5 * * * *"}'
# Expose a function to agents as a tool
butterbase functions deploy ./functions/lookup_account.ts \
--agent-tool \
--agent-tool-description "Look up a customer by email." \
--agent-tool-mode read_only \
--agent-tool-exposed-to developer_only
# View logs
butterbase functions logs my-function
# Error logs only
butterbase functions logs my-function --level error
# Limit log count
butterbase functions logs my-function --limit 50
```
Log output shows timestamp, method, status code, duration, and errors for each invocation. If the function used `console.log/info/warn/error/debug`, the captured output appears indented under each log entry.
**Trigger types**: `http` (default), `cron`, `s3_upload`, `webhook`, `websocket`. Multi-trigger functions are deployable via the dashboard or by POSTing a `triggers: [...]` array to the REST API; the CLI's `--trigger` flag covers the single-trigger case.
**Agent tool flags**: `--agent-tool-mode` accepts `read_only` (default, no approval needed) or `read_write` (each call pauses the agent run for human approval). `--agent-tool-exposed-to` accepts `developer_only` (default) or `end_user`.
## Agents
```bash
# List agents
butterbase agents list
# Show one agent
butterbase agents get my-agent
# Create an agent from a graph_spec.json file
butterbase agents create \
--name my-agent \
--display-name "My agent" \
--default-model anthropic/claude-3.5-sonnet \
--spec ./agent-spec.json
# Update fields (status, default_model, graph_spec)
butterbase agents update my-agent --status disabled
butterbase agents update my-agent --spec ./agent-spec.json
# Delete an agent
butterbase agents delete my-agent
```
See [Agents](/core-concepts/agents/) for graph_spec authoring and the [Agents quickstart](/getting-started/agents-quickstart/) for an end-to-end walkthrough.
## Storage
```bash
butterbase storage list
butterbase storage upload ./image.png
butterbase storage delete obj_abc123
```
## Realtime
```bash
# Enable realtime broadcasts on one or more tables
butterbase realtime enable posts comments
# Show realtime configuration (URL, active connection, table list)
butterbase realtime config
butterbase realtime config --json
# Disable realtime on a single table
butterbase realtime disable posts
```
## Frontend env vars
These environment variables are baked into your frontend build, not your functions. For function env vars, see the Functions section above and the [functions concept page](/core-concepts/functions).
```bash
# Set one or more KEY=VALUE pairs
butterbase env set VITE_API_URL=https://api.example.com DEBUG=true
# List current keys (values are not shown)
butterbase env list
butterbase env list --json
# Load from a .env file
butterbase env set-file .env.production
```
## API keys
```bash
# Generate a new key (shown once)
butterbase keys generate "deploy-bot"
# List keys (key prefix only — full values are not retrievable)
butterbase keys list
# Revoke a key (prompts for confirmation)
butterbase keys revoke key_abc123
```
## Integrations
Manage third-party tool integrations (Gmail, Slack, GitHub, etc.). See the [integrations concept page](/core-concepts/integrations) for the higher-level model.
```bash
# List the curated catalog (or search the full catalog)
butterbase integrations list
butterbase integrations list --search salesforce
# Show toolkits configured for the current app
butterbase integrations config
# Enable a toolkit for the app
butterbase integrations configure gmail
butterbase integrations configure slack --display-name "Workspace bot"
# Disable a toolkit
butterbase integrations disable slack
# Generate an OAuth URL for an end-user to connect their account
butterbase integrations connect gmail \
--redirect-url https://app.example.com/integrations/callback
# List all end-user connections
butterbase integrations connections
# Disconnect a single user's account
butterbase integrations disconnect ca_xxx
# List tools available for a connected toolkit
butterbase integrations tools gmail
# Execute a tool (e.g., as a smoke test)
butterbase integrations execute GMAIL_SEND_EMAIL \
--data '{"to":"user@example.com","subject":"hi","body":"hello"}'
```
Most subcommands accept `--app ` to target a specific app and `--user-id ` when calling on behalf of a specific end-user.
## Custom domains
Manage custom hostnames for frontend deployments. Requires the Launch plan or above. See [Custom Domains](/core-concepts/custom-domains/).
```bash
# List domains for the current app
butterbase domains list
# Add a new custom hostname (returns the CNAME target + setup instructions)
butterbase domains add app.example.com
# Poll verification status
butterbase domains status dom_abc123
# Re-trigger verification after fixing DNS
butterbase domains verify dom_abc123
# Remove a domain (prompts; pass --yes to skip)
butterbase domains delete dom_abc123 --yes
```
## Plugin
```bash
# Set up Claude Code / MCP integration for this project
butterbase plugin setup
```
This generates a `.mcp.json` file in your current directory that configures the Butterbase MCP server connection. If `.mcp.json` already exists, the command skips to avoid overwriting.
For Butterbase Skills with guided skills, install separately:
```bash
claude plugin marketplace add https://github.com/butterbase-ai/butterbase-skills
claude plugin install butterbase
```
## Data
```bash
butterbase data list # List tables
butterbase data query posts # Query rows from a table
```
## Deployments
```bash
butterbase deploy ./dist # Deploy frontend from a directory
```
## Project status
```bash
# Print app summary: name, region, tables, deployments, env keys, functions, CORS
butterbase status
butterbase status --json
```
## Open in browser
```bash
# Open the live frontend URL
butterbase open
# Open the API base URL instead
butterbase open --api
```
If no active deployment exists, `butterbase open` exits with an error.
## Global options
Most commands support `--app` to target a specific app:
```bash
butterbase schema get --app app_abc123
butterbase functions list --app app_abc123
butterbase storage list --app app_abc123
```
If `--app` is not provided, the CLI uses the current app set with `butterbase apps use`.
## KV
```bash
# Get a value
butterbase kv get mykey
# Set a value with optional TTL
butterbase kv set mykey '{"a":1}' --ttl 3600
# Delete a key
butterbase kv del mykey
# List keys by prefix
butterbase kv ls --prefix user: --limit 50
# Show KV store statistics
butterbase kv stats
# Flush all keys (requires confirmation)
butterbase kv flush --confirm
# List all exposure rules
butterbase kv rules
# Expose a key pattern with role-based access
butterbase kv expose "user:*" --read authed --write owner
# Unexpose a key pattern
butterbase kv unexpose "user:*"
# Apply exposure rules from a config file
butterbase kv apply ./kv.config.ts --dry-run
```
### Common KV workflows
**Deploy expose rules from a config file:**
```bash
# kv.config.ts in your project root, then:
butterbase kv apply kv.config.ts
```
The config declares which key patterns are reachable from frontend code. The CLI diffs against the live rules and applies only the deltas — safe to re-run.
**Browse keys in production:**
```bash
butterbase kv ls --prefix session:
# 142 keys under session:*
butterbase kv stats
# {
# "keys_total": 1284,
# "bytes_used": 2202112,
# "max_keys": 100000,
# "max_storage_bytes": 104857600,
# "max_ops_per_sec": 500,
# "max_value_bytes": 65536
# }
```
**Read/write a single key during an incident:**
```bash
butterbase kv get rate-limit:user_42 # peek a counter
butterbase kv set feature:new-checkout off # flip a flag without redeploying
```
## Environment variables
| Variable | Description |
|----------|-------------|
| `BUTTERBASE_API_KEY` | API key |
| `BUTTERBASE_ENDPOINT` | API endpoint URL |
---
## SDKs & Tools / CLI: bb repo
# `butterbase repo`
`butterbase repo` syncs a folder to your app's repo snapshots. Pushes are content-addressed: unchanged files aren't re-uploaded. The five most recent snapshots are retained.
Repo storage is **not** the same as `butterbase storage` (user-uploaded files). It's a dedicated, reserved area for your app's *source code*. Limits: 10 MB per file, 100 MB per snapshot.
## Bind a folder to an app
```bash
butterbase repo init
```
Writes `.butterbase/config.json` with `currentApp` set, and seeds a `.butterbaseignore` if none exists. Use `--force` to overwrite an existing `.butterbase/config.json` (the `pinned_snapshot_id` and other fields are preserved). Use `--no-ignore` to skip the `.butterbaseignore` seed.
## Push
```bash
butterbase repo push [--message ""] [--dry-run] [--json]
```
Walks the folder, hashes each file, calls the server's `prepare` endpoint, uploads any blobs the server doesn't already have, and commits. On success, updates `.butterbase/config.json` with the new `pinned_snapshot_id`.
`--dry-run` prints the manifest summary (sha + size + path per file) without contacting the API. Useful for inspecting what would be pushed.
## Pull
```bash
butterbase repo pull [--force] [--json]
```
Three-way reconcile against the pinned snapshot:
- Files in the remote `latest` that don't match local → fetched and overwritten.
- Files locally that aren't in `latest`:
- If their content matches the pinned snapshot (you haven't touched them), deleted silently.
- Otherwise flagged as a conflict; exits with code 1 unless `--force` is passed.
If the pinned snapshot has been pruned server-side, untracked-local deletions always require `--force`.
## Status
```bash
butterbase repo status [--json]
```
`git status`-style summary:
- `M` modified locally vs the pinned snapshot
- `?` untracked (not in pinned)
- `D` deleted (in pinned, missing locally)
- `N` new on remote (in `latest` but not in pinned and not locally — pull would bring it in)
## History and wipe
```bash
butterbase repo log [--json] # snapshot history newest-first
butterbase repo wipe # destructive — name-confirm prompt
```
## Ignore rules
Three layers, highest-precedence wins:
1. `.butterbaseignore` (negates a default with `!path`)
2. `.gitignore`
3. Hardcoded defaults: `.git/`, `node_modules/`, `dist/`, `.next/`, `.turbo/`, `.DS_Store`, `.butterbase/`
## App visibility
```bash
butterbase visibility [--listed|--unlisted] [--app ]
```
Marks the app public or private. When public, `--unlisted` hides it from the templates browse listing (`/v1/templates`, the dashboard Templates page, and `butterbase templates`) while still allowing clone by direct app id.
## Clone a public app
```bash
butterbase clone [target_dir] [--name ""] [--region ] [--json]
```
Creates a fresh, owned app cloned from a public template. The CLI:
1. Calls the clone endpoint to start a job.
2. Polls until the job completes (max 5 minutes).
3. `butterbase repo init ` + `butterbase repo pull` in `` (defaults to a dir named after the new app id).
Clones receive the source's schema, RLS policies, function code, non-secret config, repo files, and rows from `_seed: true` tables. End-user accounts, secrets, env vars, BYOK AI keys, custom domains, and audit logs stay with the source. See [What a clone copies](/core-concepts/database#what-a-clone-copies) for the full breakdown.
The `butterbase clone` command prints any warnings returned by the clone job — for example, if the source's `auth_hook_function` references a function that didn't replay onto the destination, the binding is left NULL and a warning is printed.
If the clone fails, the error is printed and exit code is 1. Failed jobs can be retried via the HTTP API directly (`POST /v1/clone-jobs//retry`).
---
## SDKs & Tools / CLI: bb substrate
# `butterbase substrate`
The `butterbase substrate` command group gives you scriptable access to the Butterbase substrate: the per-user memory + action coordination plane that backs your AI agents.
It uses your active Butterbase API key. The key must be **substrate-scoped** — generate one with:
```bash
butterbase keys generate --substrate
export BUTTERBASE_API_KEY="bb_sk_..."
```
All commands accept `--json` to emit the raw API response (suitable for piping to `jq`).
## Action ledger
### `butterbase substrate ledger`
List actions in the substrate ledger.
```bash
butterbase substrate ledger --status executed --capability send_email_draft --limit 25
butterbase substrate ledger --before 2026-05-28T00:00:00Z --json | jq '.actions[].id'
```
### `butterbase substrate propose `
Propose a new action.
```bash
echo '{"to":"hello@example.com","subject":"hi","body":"hi"}' > payload.json
butterbase substrate propose send_email_draft --payload @payload.json --idempotency-key my-key-1
```
### `butterbase substrate approve ` / `butterbase substrate reject [--reason]`
Approve or reject a pending action.
```bash
butterbase substrate approve act_01H...
butterbase substrate reject act_01H... --reason "policy mismatch"
```
## Entities
```bash
butterbase substrate entities list --type person
butterbase substrate entities get ent_01H...
echo '{"display_name":"Renamed"}' > patch.json
butterbase substrate entities update ent_01H... --patch @patch.json
```
## Artifacts
List and fetch source artifacts — meeting transcripts, email threads, call recordings, documents — that the substrate has extracted into durable memory.
### `butterbase substrate artifacts list`
```bash
butterbase substrate artifacts list --kind meeting_transcript --limit 25
butterbase substrate artifacts list --q "billing migration" --json | jq '.artifacts[].id'
```
| Option | Type | Default |
|---|---|---|
| `--kind ` | string | _all_ |
| `--q ` | string (FTS over title+summary+content) | _none_ |
| `--limit ` | int (1–200) | 50 |
| `--json` | flag | _table output_ |
### `butterbase substrate artifacts get `
Fetch a single artifact, including its full `content`.
```bash
butterbase substrate artifacts get art_01H...
butterbase substrate artifacts get art_01H... --json | jq -r '.content'
```
## Memory
Full-text search across decisions, commitments, learnings, and source artifacts.
`` is optional. When omitted, the command returns the most recent items across the selected kinds ordered by recency, capped by `--limit`.
```bash
# search with a query
butterbase substrate memory "OKR planning Q3" --limit 10
# list most recent items (no query)
butterbase substrate memory --limit 20
# require all words (default)
butterbase substrate memory "billing migration" --match and
# match any word
butterbase substrate memory "billing migration" --match or
# require adjacent words (phrase search)
butterbase substrate memory "billing migration" --match phrase
```
| Option | Type | Default |
|---|---|---|
| `` | string (FTS query; omit to list all) | _none_ |
| `--match ` | `and` \| `or` \| `phrase` | `and` |
| `--kinds ` | comma-separated: `decisions`, `commitments`, `learnings`, `source_artifacts` | _all_ |
| `--limit ` | int (1–200) | 20 |
| `--json` | flag | _table output_ |
Each result row includes `id`, `kind`, `title`, `body_text`, `rank` (null when no query), `updated_at`, `source_artifact_id`, `supersedes`, and `status`.
```json
{
"results": [
{
"id": "dec_01…",
"kind": "decision",
"title": "Adopt substrate",
"body_text": "agents need shared memory",
"rank": 0.18,
"updated_at": "2026-05-31T…",
"source_artifact_id": null,
"supersedes": null,
"status": "active"
}
]
}
```
## Memory list (chronological browse)
Chronological browse across decisions, commitments, learnings, and source artifacts with structural filters. Results are ordered by `updated_at DESC`. There is no relevance ranking.
```bash
butterbase substrate memory-list --source-artifact-id art_01H... --kinds decisions,commitments,learnings --superseded false --limit 50
```
| Flag | Type | Default |
|---|---|---|
| `--kinds ` | comma-separated: `decisions`, `commitments`, `learnings`, `source_artifacts` | _all_ |
| `--source-artifact-id ` | string — restrict to rows linked to this source artifact (source_artifact rows excluded when set) | _none_ |
| `--superseded ` | `true` \| `false` — when `false`, excludes superseded decisions and expired commitments | _include all_ |
| `--before ` | ISO timestamp keyset cursor (paste `next_before` from a previous response) | _none_ |
| `--limit ` | int (1–100) | 25 |
| `--json` | flag | _table output_ |
## Outbox
```bash
butterbase substrate outbox list --state pending
butterbase substrate outbox cancel ob_01H...
butterbase substrate outbox retry ob_01H...
```
## Attention rules
```bash
butterbase substrate rules list --enabled
butterbase substrate rules get rule_01H...
echo '{
"name": "weekly digest",
"trigger_cron": "0 9 * * 1",
"condition_mode": "snapshot_predicate",
"condition": { ">": [{ "var": "entity_count" }, 0] },
"action_capability": "send_email_draft",
"action_payload_template": {
"to": "me@example.com",
"subject": "Weekly digest",
"body": "{{entity_count}} entities."
}
}' > rule.json
butterbase substrate rules create --file @rule.json
butterbase substrate rules enable rule_01H...
butterbase substrate rules disable rule_01H...
butterbase substrate rules firings rule_01H... --limit 50
butterbase substrate rules delete rule_01H...
```
## Snapshots
Daily state snapshots used by attention-rule conditions.
```bash
butterbase substrate snapshots --days 7
```
## Settings
```bash
butterbase substrate settings show
butterbase substrate settings yolo on
butterbase substrate settings yolo off
```
## Output formats
- Default: compact, human-readable table where applicable.
- `--json`: raw HTTP response body. Useful for scripting.
## Authentication errors
If a command returns `your active key is app-scoped`, generate a substrate-scoped key:
```bash
butterbase keys generate --substrate
```
---
## SDKs & Tools / Claude Code Plugin
**Butterbase Skills** is a Claude Code plugin that auto-configures the Butterbase MCP server and provides guided skills for common workflows.
## Installation
```bash
# Add the Butterbase marketplace
claude plugin marketplace add https://github.com/butterbase-ai/butterbase-skills
# Install the plugin
claude plugin install butterbase
```
Set your API key:
```bash
export BUTTERBASE_API_KEY=bb_sk_your_key_here
```
## What's included
### MCP Server Auto-Configuration
The plugin includes a `.mcp.json` that automatically configures the Butterbase MCP server connection. All 43 tools and 1 prompt are available immediately — no manual configuration needed.
### Always-On Context (CLAUDE.md)
The plugin provides Claude with always-on context about Butterbase:
- Environment variables (`BUTTERBASE_API_KEY`, `VITE_API_URL`, etc.)
- Core workflow (init → schema → RLS → auth → deploy)
- Important patterns (storage objectId, function Response objects, RLS roles)
- Documentation reference (all `butterbase_docs` topics)
### Skills
6 guided skills for common Butterbase workflows:
| Skill | Slash command | Description |
|-------|--------------|-------------|
| Build App | `/butterbase-skills:build-app` | End-to-end guide: create app, design schema, set up RLS, configure auth, deploy functions, deploy frontend |
| Schema Design | `/butterbase-skills:schema` | Database schema DSL reference with column types, indexes, and 4 complete data model patterns |
| Deploy Frontend | `/butterbase-skills:deploy` | 7-step deployment workflow for React, Next.js, and static HTML frontends |
| Debug RLS | `/butterbase-skills:debug-rls` | Systematic Row-Level Security debugging with role simulation |
| Function Dev | `/butterbase-skills:function` | Serverless function development with handler signatures, triggers, and working examples |
| Contributing | `/butterbase-skills:contributing` | Contributor guide for the Butterbase monorepo |
## Alternative: CLI Setup
If you only need the MCP connection (without skills), use the CLI:
```bash
butterbase plugin setup
```
Or during project initialization:
```bash
butterbase init react-vite
```
Both generate a `.mcp.json` file that configures the MCP server connection.
## Local Development
When running the Butterbase monorepo locally, the MCP server URL defaults to `http://localhost:4000/mcp`. Set this in your environment:
```bash
export CONTROL_API_URL=http://localhost:4000
```
## Testing locally
Load the plugin from a local directory for development:
```bash
claude --plugin-dir /path/to/butterbase-plugin
```
## Source
- **GitHub**: [Butterbase Skills](https://github.com/butterbase-ai/butterbase-skills)
- **License**: MIT
---
## SDKs & Tools / REST API
Once you create tables through the schema tools, a full REST API is automatically available. No code generation or route setup needed.
**Placeholders:**
- `{app_id}` — Your app's identifier
- `{table}` — A table name in your schema
- `{id}` — A row's primary key value
## Data API
| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/\{app_id}/\{table} | List rows with filtering, sorting, pagination |
| GET | /v1/\{app_id}/\{table}/\{id} | Read a single row by primary key |
| POST | /v1/\{app_id}/\{table} | Create a row |
| PATCH | /v1/\{app_id}/\{table}/\{id} | Update a row (partial) |
| DELETE | /v1/\{app_id}/\{table}/\{id} | Delete a row |
## Filtering
Add query parameters in the format `column=operator.value`:
| Operator | Example | Meaning |
|----------|---------|---------|
| `eq` | `status=eq.published` | Equals |
| `neq` | `status=neq.draft` | Not equals |
| `gt` | `age=gt.18` | Greater than |
| `gte` | `age=gte.18` | Greater than or equal |
| `lt` | `price=lt.100` | Less than |
| `lte` | `price=lte.100` | Less than or equal |
| `like` | `title=like.%hello%` | Pattern match (case-sensitive) |
| `ilike` | `title=ilike.%hello%` | Pattern match (case-insensitive) |
| `is` | `deleted_at=is.null` | IS NULL, IS TRUE, IS FALSE |
| `in` | `id=in.(1,2,3)` | In a list of values |
| `fts` | `title=fts.hello world` | Full-text search (English, with stemming) |
## Sorting
Use the `order` parameter:
```
?order=created_at.desc
?order=name.asc,created_at.desc
```
## Pagination
Use `limit` and `offset`:
```
?limit=20&offset=40
```
Returns rows 41-60.
## Column selection
Use the `select` parameter:
```
?select=id,title,created_at
```
## Example
```
GET /v1/{app_id}/posts?select=id,title,author_id&status=eq.published&order=created_at.desc&limit=20
```
## Authentication
The role is determined automatically by the Authorization header:
| Request type | Authorization header | Role |
|---|---|---|
| No auth header | (none) | butterbase_anon |
| End-user JWT | `Bearer {jwt}` | butterbase_user |
| Platform API key | `Bearer {api_key}` | butterbase_service |
See [Row-Level Security](/core-concepts/row-level-security) for how these roles interact with data access policies.
## Schema endpoints
| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/\{app_id}/schema | Read current schema |
| POST | /v1/\{app_id}/schema/apply | Apply a schema update |
| GET | /v1/\{app_id}/migrations | List applied migrations |
## App management
| Method | Path | Purpose |
|--------|------|---------|
| GET | /apps | List your apps |
| POST | /init | Create a new app (accepts optional `region`) |
| DELETE | /apps/\{app_id} | Delete an app |
| GET | /v1/regions | List supported regions (public, no auth) |
| POST | /v1/apps/\{app_id}/move | Move an app to another region |
| GET | /v1/apps/\{app_id}/migrations/\{migration_id} | Check move progress |
See [Regions](/core-concepts/regions/) and the [Platform API reference](/api-reference/platform-api/#apps--regions) for request and response shapes.
## Health checks
| Method | Path | Purpose |
|--------|------|---------|
| GET | /health | Liveness check |
| GET | /health/ready | Readiness check (verifies database) |
## Error responses
Errors include structured objects with `code`, `message`, and `remediation` fields:
```json
{
"error": {
"code": "RESOURCE_NOT_FOUND",
"message": "Table 'nonexistent' does not exist",
"remediation": "Check the table name and ensure it exists in your schema"
}
}
```
For complete endpoint references, see the [API Reference](/api-reference/data-api) section.
---
## Guides / React
Build React applications with Butterbase using the TypeScript SDK.
## Setup
```bash
npm create vite@latest my-app -- --template react-ts
cd my-app && npm install
npm install @butterbase/sdk
```
Create client:
```typescript
// src/lib/butterbase.ts
import { createClient } from '@butterbase/sdk';
export const butterbase = createClient({
appId: import.meta.env.VITE_BUTTERBASE_APP_ID,
apiUrl: import.meta.env.VITE_BUTTERBASE_API_URL,
});
```
Environment variables (`.env.local`):
```
VITE_BUTTERBASE_APP_ID=app_abc123
VITE_BUTTERBASE_API_URL=https://api.butterbase.ai
```
## Authentication component
```tsx
const handleSignIn = async () => {
const { data, error } = await butterbase.auth.signIn({ email, password });
};
```
## Data fetching
```tsx
const { data: posts } = await butterbase
.from('posts')
.select('*')
.order('created_at', { ascending: false })
.limit(20);
```
## Auth state changes
```tsx
const { unsubscribe } = butterbase.onAuthStateChange((event, session) => {
setUser(session?.user ?? null);
});
return () => unsubscribe();
```
## OAuth
```tsx
const { url } = await butterbase.auth.signInWithOAuth({
provider: 'google',
redirectTo: window.location.origin + '/auth/callback',
});
window.location.href = url;
```
## File uploads
```tsx
const { data, error } = await butterbase.storage.upload(file);
// Save data.objectId in your database
```
## Deploy
```bash
npm run build
cd dist && zip -r ../frontend.zip .
```
Use `create_frontend_deployment` and `start_frontend_deployment` MCP tools to deploy.
---
## Guides / Next.js
Build Next.js applications with Butterbase using the TypeScript SDK.
## Setup
```bash
npx create-next-app@latest my-app --typescript --app
cd my-app
npm install @butterbase/sdk
```
Create client:
```typescript
// src/lib/butterbase.ts
import { createClient } from '@butterbase/sdk';
export const butterbase = createClient({
appId: process.env.NEXT_PUBLIC_BUTTERBASE_APP_ID!,
apiUrl: process.env.NEXT_PUBLIC_BUTTERBASE_API_URL!,
});
```
Environment variables (`.env.local`):
```
NEXT_PUBLIC_BUTTERBASE_APP_ID=app_abc123
NEXT_PUBLIC_BUTTERBASE_API_URL=https://api.butterbase.ai
```
## Static export for deployment
Add to `next.config.js`:
```js
/** @type {import('next').NextConfig} */
const nextConfig = {
output: 'export',
};
module.exports = nextConfig;
```
Build and deploy:
```bash
npm run build
cd out && zip -r ../frontend.zip .
```
Deploy with `framework: "nextjs-static"`.
---
## Guides / Monetization
Butterbase includes built-in Stripe Connect support so you can sell subscriptions and one-time products to your app's end users. This is separate from your own Butterbase subscription — it's for monetizing the product you build.
:::note
This guide is the condensed API tour. For the full step-by-step setup — Connect onboarding, webhook configuration, gating access, testing, going live, and troubleshooting — see [Charging Your Users](/core-concepts/billing/).
:::
## How it works
1. Onboard a Stripe Connect account for your app
2. Define subscription plans or products with pricing
3. Your end users subscribe or purchase through Checkout sessions managed by the platform
## Setting up Stripe Connect
### Step 1: Onboard your Connect account
```
POST /v1/{app_id}/billing/connect/onboard
```
Returns `accountId` and `onboardingUrl`. Complete the setup in Stripe.
### Step 2: Check onboarding status
```
GET /v1/{app_id}/billing/connect/status
```
Returns whether Connect onboarding is complete and payouts are ready.
## Subscriptions
### Developer endpoints (platform auth)
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/billing/plans | Create a subscription plan |
| GET | /v1/\{app_id}/billing/plans | List plans (public catalog) |
| PUT | /v1/\{app_id}/billing/plans/\{plan_id} | Update plan fields |
**Create a plan:**
```json
POST /v1/{app_id}/billing/plans
{
"name": "Pro Plan",
"priceCents": 999,
"interval": "month",
"features": ["Unlimited projects", "Priority support", "Custom domain"]
}
```
### End user endpoints (app JWT)
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/billing/subscribe | Start a subscription |
| GET | /v1/\{app_id}/billing/subscription | Current subscription |
| POST | /v1/\{app_id}/billing/cancel | Cancel at period end |
**Subscribe:**
```json
POST /v1/{app_id}/billing/subscribe
{
"planId": "uuid-of-plan",
"successUrl": "https://yourapp.com/billing/success",
"cancelUrl": "https://yourapp.com/billing/cancel"
}
```
Returns a Stripe Checkout `url` for the user to complete payment.
## One-time purchases
For selling digital products, physical goods, or one-time access.
### Developer endpoints
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/billing/products | Create a product |
| GET | /v1/\{app_id}/billing/products | List products (public catalog) |
| PUT | /v1/\{app_id}/billing/products/\{product_id} | Update product |
**Create a product:**
```json
POST /v1/{app_id}/billing/products
{
"name": "Premium Template Pack",
"priceCents": 2999,
"description": "50+ premium UI templates",
"metadata": { "category": "templates" }
}
```
### End user endpoints
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/billing/purchase | Purchase a product |
| GET | /v1/\{app_id}/billing/orders | List all orders |
| GET | /v1/\{app_id}/billing/orders/{order_id} | Get order details |
### Order statuses
| Status | Meaning |
|--------|---------|
| `pending` | Checkout session created, payment not yet completed |
| `paid` | Payment successful |
| `failed` | Payment failed |
| `refunded` | Payment was refunded |
## Webhooks
Stripe sends Connect events to `POST /webhooks/stripe/connect`. On Butterbase Cloud this is already wired — you don't configure anything. Self-hosting, register the endpoint on your Stripe platform account with **"events on Connected accounts"** enabled and set `STRIPE_CONNECT_WEBHOOK_SECRET` in the control API environment.
The platform handles:
- `checkout.session.completed` (subscriptions and payments)
- `customer.subscription.updated` / `deleted`
- `invoice.payment_succeeded` / `failed`
- `payment_intent.payment_failed`
- `charge.refunded`
## Example flow (subscriptions)
1. Developer creates plan: `POST /v1/{app_id}/billing/plans`
2. End user subscribes: `POST /v1/{app_id}/billing/subscribe`
3. User completes payment in Stripe Checkout
4. Webhook fires, subscription activates
5. User can check status: `GET /v1/{app_id}/billing/subscription`
## Alternative approach
If you don't need Connect, you can build checkout flows yourself using Stripe directly in a [serverless function](/core-concepts/functions) and store purchase state in your app tables.
---
## Guides / KV Recipes
KV is a natural fit for data that is short-lived, accessed by key, and does not need relational queries. Each recipe below is self-contained — pick the one that matches your use case, paste it into a [serverless function](/core-concepts/functions/), and adjust the key names and TTLs for your app.
All examples use `ctx.kv` inside a function handler. See [Key-Value Store](/core-concepts/kv/) for a full method reference.
## Session store
When you need per-user state that lives for a bounded time — auth sessions, shopping carts, wizard progress — KV is the simplest choice. Values are stored as JSON, scoped to your app, and expire automatically so you do not need a cleanup job.
```typescript
export default async function handler(req, ctx) {
// Read an existing session
const sessionId = req.headers.get('x-session-id');
const session = await ctx.kv.get<{ userId: string; role: string }>(
`session:${sessionId}`,
);
if (!session) {
return new Response('Unauthorized', { status: 401 });
}
// session.userId and session.role are available here
return Response.json({ userId: session.userId });
}
// On login — write a session with a 24-hour TTL
async function createSession(ctx, sessionId: string, userId: string, role: string) {
await ctx.kv.set(
`session:${sessionId}`,
{ userId, role },
{ ttl: 60 * 60 * 24 },
);
}
// On logout — delete immediately rather than waiting for expiry
async function destroySession(ctx, sessionId: string) {
await ctx.kv.del(`session:${sessionId}`);
}
```
TTL is fixed at write time and does not slide automatically. If you want sliding sessions (i.e., reset the clock on every request), call `ctx.kv.expire(key, seconds)` after a successful `get` to push the expiry forward. Keep session blobs small — store a user ID and role, not the full user record. For large payloads consider [File Storage](/core-concepts/storage/).
```bash
# Inspect a live session; force sign-out a specific user without waiting for TTL
butterbase kv get session:
butterbase kv del session:
```
## Distributed lock
Use a distributed lock when two workers must not run the same job simultaneously — for example, processing a webhook, sending an email, or charging a card. `setnx` sets the key only if it does not already exist and returns `true` when the lock is acquired.
```typescript
export default async function handler(req, ctx) {
const { orderId } = await req.json();
const lockKey = `lock:order:${orderId}`;
// Attempt to acquire — lock expires in 30 s if the worker crashes
const acquired = await ctx.kv.setnx(lockKey, ctx.requestId, { ttl: 30 });
if (!acquired) {
return Response.json({ error: 'already_processing' }, { status: 409 });
}
try {
// ... do the exclusive work here ...
return Response.json({ status: 'done' });
} finally {
// Release only if we still own the lock (guards against TTL expiry race)
const swapped = await ctx.kv.cas(lockKey, ctx.requestId, null);
if (swapped) {
await ctx.kv.del(lockKey);
}
}
}
```
The TTL is a safety net, not a hard deadline — if your worker crashes before the `finally` block, the lock releases automatically when the TTL elapses. Keep your work duration well under the TTL. If work could legitimately take longer than 30 seconds, increase the TTL or implement lock renewal with `ctx.kv.expire`. Do not use this pattern for human-facing critical sections where the user needs immediate feedback on contention — design around idempotency (see below) instead.
```bash
# Inspect who holds the lock; force-release if a worker crashed without TTL covering it
butterbase kv get lock:order:
butterbase kv del lock:order:
```
## Rate limiter
A fixed-window counter is the simplest way to cap actions per user per time period. The key includes a timestamp bucket so it resets automatically when the window rolls over.
```typescript
export default async function handler(req, ctx) {
const userId = req.headers.get('x-user-id') ?? 'anonymous';
const windowMinute = Math.floor(Date.now() / 60_000);
const key = `ratelimit:${userId}:${windowMinute}`;
const count = await ctx.kv.incr(key);
// Set the TTL on the first increment so the key expires after the window
if (count === 1) {
await ctx.kv.expire(key, 60);
}
if (count > 100) {
return new Response('Rate limit exceeded', { status: 429 });
}
// ... handle the request ...
return Response.json({ remaining: 100 - count });
}
```
If you want frontend code to call a rate-limiter endpoint directly, you can open the keyspace with `expose()`:
```typescript
// Call once during app setup or in a migration function
await ctx.kv.expose('ratelimit:{user.id}:*', { read: 'owner', write: 'owner' });
```
`expose()` is the only KV method that controls client-side access. See [Access control](/core-concepts/kv/#access-control) for the full role model and pattern syntax rather than repeating it here.
Fixed-window counters are simple but allow a burst of up to 2× the limit at window boundaries (requests at the tail of one window plus the head of the next). For most APIs this is acceptable. If you need smoother enforcement, use a sliding-window approach with a sorted-set or store a small list of timestamps — or just halve your limit.
```bash
# Inspect the running request count for a user in the current time window
butterbase kv get ratelimit::
```
## Idempotency keys
When a client retries a request (network timeout, duplicate submit), you need to ensure the work happens exactly once and the second call returns the same result as the first. `setnx` claims ownership of a request ID atomically, so only one execution proceeds.
```typescript
export default async function handler(req, ctx) {
const requestId = req.headers.get('x-idempotency-key');
if (!requestId) {
return new Response('Missing X-Idempotency-Key header', { status: 400 });
}
const idemKey = `idempotent:${requestId}`;
// Try to claim this request ID
const claimed = await ctx.kv.setnx(idemKey, 'pending', { ttl: 60 * 60 * 24 });
if (!claimed) {
// Already processed (or in progress) — return cached result
const cached = await ctx.kv.get(idemKey);
if (cached && cached !== 'pending') {
return new Response(cached, {
status: 200,
headers: { 'content-type': 'application/json' },
});
}
// Still pending — tell client to retry shortly
return new Response('Request in progress', { status: 409 });
}
// We own it — do the work
const result = await doTheWork();
// Store the serialised result so duplicates can return it
await ctx.kv.set(idemKey, JSON.stringify(result), { ttl: 60 * 60 * 24 });
return Response.json(result);
}
async function doTheWork() {
// your business logic here
return { charged: true, amount: 4900 };
}
```
The TTL controls how long duplicate detection lasts — make it longer than your client's retry window. If your work function throws, the key stays set to `'pending'` indefinitely; add error handling that either stores the error response or deletes the key so the client can retry cleanly.
```bash
# Verify whether a specific request ID has already been claimed
butterbase kv get idempotent:
```
## Feature flags
Store a flag value in KV and read it at request time. Changes take effect on the next request without a redeployment.
```typescript
export default async function handler(req, ctx) {
// Read flag — default to 'off' if key is missing
const flagValue = await ctx.kv.get('feature:new-checkout');
const newCheckoutEnabled = flagValue === 'on';
if (newCheckoutEnabled) {
// new checkout path
return Response.json({ checkout: 'v2' });
} else {
// legacy path
return Response.json({ checkout: 'v1' });
}
}
```
Flip the flag without touching code:
```bash
# CLI
butterbase kv set feature:new-checkout on
butterbase kv set feature:new-checkout off
```
Or via MCP (`manage_kv` with `action: 'set'`), or directly in the Butterbase dashboard under **KV** → your app.
For a percentage rollout, store a threshold (e.g., `'30'` for 30 %) and check it against a deterministic hash of the user ID:
```typescript
const threshold = parseInt((await ctx.kv.get('rollout:new-checkout')) ?? '0', 10);
const bucket = hashUserId(userId) % 100; // your own stable hash function
const enabled = bucket < threshold;
```
This gives a stable assignment per user — the same user always sees the same variant — and you can gradually raise the threshold to roll out to a wider audience.
```bash
# Flip a flag instantly without redeploying; read back to confirm the new value
butterbase kv set feature: on
butterbase kv get feature:
```
---
## API Reference / Agents API
The Agents API is split into three groups:
1. **Agent management** — create, list, update, delete, and validate agents. Owner-only.
2. **Runs (authenticated)** — start, fetch, stream, cancel, and resume runs by an authenticated app user or the app owner.
3. **Runs (public)** — start runs anonymously for agents marked `visibility: "public"`.
A separate group of routes manages **MCP servers** the app's agents can call.
For an overview of the agent model (graph spec, nodes, tools, events) see the [Agents concept page](/core-concepts/agents/).
## Agent management
| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/\{app_id}/agents | List agents in the app |
| POST | /v1/\{app_id}/agents | Create an agent |
| GET | /v1/\{app_id}/agents/\{name} | Fetch a single agent |
| PATCH | /v1/\{app_id}/agents/\{name} | Update fields (status, graph_spec, access controls) |
| DELETE | /v1/\{app_id}/agents/\{name} | Soft-delete an agent |
| POST | /v1/\{app_id}/agents/\{name}/validate | Type-check a draft graph spec without saving |
### Create an agent
```http
POST /v1/{app_id}/agents
Authorization: Bearer {token}
{
"name": "billing-triage",
"display_name": "Billing triage",
"description": "Classifies billing questions and answers them.",
"default_model": "anthropic/claude-3.5-haiku",
"graph_spec": { ... see graph_spec schema below ... },
"visibility": "private",
"max_runs_per_user_per_hour": 60,
"daily_budget_usd": 5.0,
"max_concurrent_runs": 4,
"safety_acknowledged": false
}
```
**Required fields:** `name` (slug, 1-100 chars), `graph_spec`.
**Default access:** `visibility: "private"`, no rate limits, no budget. Public agents require `safety_acknowledged: true`.
### graph_spec v1 schema
```json
{
"spec_version": "1",
"entry": "",
"nodes": {
"": {
"type": "llm" | "tool" | "end",
"...": "type-specific fields, see below"
}
},
"edges": [{ "from": "", "to": "" }],
"tools": {
"builtin": ["select_rows", "..."],
"mcp_servers": [
{ "server_id": "uuid", "tools": ["search"], "tool_overrides": {} }
],
"functions": ["lookup_account"]
},
"limits": {
"max_steps": 1..200,
"max_tool_calls": 0..500,
"max_parallel_tools": 1..16,
"timeout_seconds": 5..3600,
"human_timeout_seconds": 60..604800
}
}
```
#### `llm` node
```json
{
"type": "llm",
"model": "anthropic/claude-3.5-sonnet",
"system_prompt": "You are a {{ state.category }} agent.",
"input_template": "{{ input.message }}",
"output_key": "reply",
"tools": [
{ "source": "builtin", "name": "select_rows" },
{ "source": "function", "name": "lookup_account" },
{ "source": "mcp", "server_id": "uuid", "name": "search" }
],
"temperature": 0.7,
"max_tokens": 1024
}
```
#### `tool` node
```json
{
"type": "tool",
"tool_ref": { "source": "function", "name": "preprocess" },
"args_template": { "raw": "{{ input.body }}" },
"output_key": "preprocessed"
}
```
#### `end` node
```json
{ "type": "end", "output_template": "{{ state.reply }}" }
```
### Tool references and overrides
Every `toolRef` accepts two optional override fields:
- `mode_override`: `"read_only" | "read_write"` — narrow or widen the tool's mode for this agent.
- `exposed_to_override`: `"developer_only" | "end_user"` — narrow or widen exposure.
You can only **narrow** access (read_write→read_only, end_user→developer_only), never widen past the function/MCP tool's stored value.
### Validate (without saving)
```http
POST /v1/{app_id}/agents/{name}/validate
{ "graph_spec": { ... } }
200 { "valid": true }
200 { "valid": false, "issues": [{ "path": ["nodes","x","model"], "message": "..." }] }
```
## Runs (authenticated)
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/agents/\{name}/runs | Start a run |
| GET | /v1/\{app_id}/agents/\{name}/runs | List recent runs |
| GET | /v1/\{app_id}/agents/\{name}/runs/\{id} | Fetch one run |
| POST | /v1/\{app_id}/agents/\{name}/runs/\{id}/cancel | Cancel a queued / running run |
| POST | /v1/\{app_id}/agents/\{name}/runs/\{id}/resume | Resume a paused run with approval payload |
| GET | /v1/\{app_id}/agents/\{name}/runs/\{id}/events.json | Replay events as a single JSON array |
| GET | /v1/\{app_id}/agents/\{name}/runs/\{id}/events | Live SSE stream of events |
### Start a run
```http
POST /v1/{app_id}/agents/billing-triage/runs
Authorization: Bearer {token}
{ "input": { "message": "Why was I charged twice?" } }
201 { "run_id": "run_...", "status": "queued" }
200 { "run_id": "run_...", "status": "running" } // idempotent replay
409 { "error": "conflict", "existing_run_id": "run_..." }
```
The request body is hashed and stored as an implicit idempotency key — re-posting the same body within the dedupe window returns the existing run (`200`). Submitting a different body for the same agent within the window returns `409`.
### SSE stream
```http
GET /v1/{app_id}/agents/billing-triage/runs/run_abc/events
Authorization: Bearer {token}
Accept: text/event-stream
id: 1
event: run_start
data: {"input": {...}}
id: 2
event: node_start
data: {"node_id": "triage", "step": 1}
...
event: run_end
data: {"output": "Hi! I found your account..."}
```
Event types: `run_start`, `node_start`, `node_end`, `tool_call_start`, `tool_call_end`, `llm_token_usage`, `run_paused`, `run_cancelled`, `run_failed`, `run_end`.
The stream supports resume via the `Last-Event-ID` header — reconnecting with the last `id` you received replays the missing tail.
### Pause / resume (HITL)
When a `read_write` tool fires, the runtime emits:
```
event: run_paused
data: { "payload": { "tool_name": "delete_account", "args": {...}, "approval_token": "..." } }
```
Resume with the same approval token and an explicit decision:
```http
POST /v1/{app_id}/agents/{name}/runs/{id}/resume
{ "approval_token": "...", "approved": true }
```
Denying the approval (`approved: false`) terminates the run with `run_failed` and a `reason: "approval_denied"`.
## Public runs
If the agent's `visibility` is `public`, anonymous callers can use the public endpoints with the app's public anon key:
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/public/agents/\{name}/runs | Start a public run |
| GET | /v1/\{app_id}/public/runs/\{id} | Fetch a public run |
| POST | /v1/\{app_id}/public/runs/\{id}/cancel | Cancel a public run |
| POST | /v1/\{app_id}/public/runs/\{id}/resume | Resume a paused public run |
| GET | /v1/\{app_id}/public/runs/\{id}/events.json | JSON event array |
| POST | /v1/\{app_id}/public/runs/\{id}/stream-token | Mint a one-time token for the SSE/WebSocket stream |
| GET | /v1/\{app_id}/public/runs/\{id}/events | SSE stream (requires `?token=` from above) |
| GET | /v1/\{app_id}/public/runs/\{id}/ws | WebSocket stream (requires `?token=` from above) |
Public runs respect the agent's per-IP rate limits, daily budget, and max concurrent runs.
## MCP servers
| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/\{app_id}/mcp-servers | List registered MCP servers |
| POST | /v1/\{app_id}/mcp-servers | Register a new MCP server |
| DELETE | /v1/\{app_id}/mcp-servers/\{id} | Remove an MCP server |
| POST | /v1/\{app_id}/mcp-servers/\{id}/probe | Refresh the server's advertised tool list |
```http
POST /v1/{app_id}/mcp-servers
{
"name": "Stripe docs",
"url": "https://mcp.stripe.com",
"auth": { "type": "bearer", "token": "sk_..." }
}
```
Once registered, an agent can reference any of the server's advertised tools by listing them in `graph_spec.tools.mcp_servers`.
## Errors
| Code | Meaning |
|---|---|
| 400 | Invalid graph spec, missing required field, or budget would be exceeded. |
| 401 | Missing or invalid token. |
| 403 | Caller lacks owner role on the app, or agent is `private` and caller is not the owner. |
| 404 | Agent or run not found. |
| 409 | Idempotency conflict, or `safety_acknowledged: false` on a `public` agent. |
| 422 | Validation error from `POST /validate`. |
| 429 | Rate limit (per-user, per-IP, or per-app) exceeded. |
| 503 | Agent runtime overloaded; retry with backoff. |
---
## API Reference / AI API
Butterbase exposes an OpenAI-compatible API for chat completions, embeddings, and model listing. There are two ways to call it:
- **App-scoped** — calls go through `/v1/{app_id}/...`, are billed to the app's owner, and inherit the app's AI configuration (default model, allowed models).
- **Gateway mode** — calls go through `/v1/...` (no `app_id`), authenticated with a platform JWT or a personal API key. Use this when you want a generic OpenAI-compatible gateway and don't need an app.
## App-scoped endpoints
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/chat/completions | Chat completion (OpenAI-compatible) |
| POST | /v1/\{app_id}/embeddings | Generate embeddings |
| GET | /v1/\{app_id}/ai/config | Get AI configuration |
| PUT | /v1/\{app_id}/ai/config | Update AI configuration |
| GET | /v1/\{app_id}/ai/usage | Get AI usage statistics |
## Gateway endpoints (no app required)
| Method | Path | Purpose | Auth |
|--------|------|---------|------|
| POST | /v1/chat/completions | Chat completion | Required |
| POST | /v1/embeddings | Generate embeddings | Required |
| GET | /v1/models | List available models (OpenAI-shape) | Required |
| GET | /v1/public/models | Public model catalog with pricing | None |
Drop-in compatible with the OpenAI SDK: point `baseURL` at `https://api.butterbase.ai/v1` and use a personal API key as the bearer token. The request and response shapes are identical to the app-scoped variants — only the path differs.
### Chat completions (gateway)
```json
POST /v1/chat/completions
Authorization: Bearer bb_sk_...
{
"model": "anthropic/claude-3.5-sonnet",
"messages": [
{ "role": "user", "content": "Hello!" }
],
"max_tokens": 500,
"temperature": 0.7,
"stream": false
}
```
Set `"stream": true` for server-sent events.
### Embeddings (gateway)
```json
POST /v1/embeddings
Authorization: Bearer bb_sk_...
{
"model": "openai/text-embedding-3-small",
"input": "What is Butterbase?",
"encoding_format": "float"
}
```
### List models
```json
GET /v1/models
Authorization: Bearer bb_sk_...
```
Response:
```json
{
"object": "list",
"data": [
{ "id": "anthropic/claude-3.5-sonnet", "object": "model", "display_name": "Claude 3.5 Sonnet" },
{ "id": "openai/gpt-4o", "object": "model", "display_name": "GPT-4o" }
]
}
```
### Public model catalog
A separate **unauthenticated** endpoint returns the full catalog with pricing and context window — useful for documentation pages, model pickers, and tooling that needs to enumerate models before the user has signed in.
```
GET /v1/public/models
```
No authorization header required.
Response:
```json
{
"models": [
{
"id": "anthropic/claude-sonnet-4.6",
"name": "Claude Sonnet 4.6",
"inputPricePerMTokens": 3.6,
"outputPricePerMTokens": 18.0,
"contextWindow": 200000
},
{
"id": "openai/gpt-4o",
"name": "GPT-4o",
"inputPricePerMTokens": 3.0,
"outputPricePerMTokens": 12.0,
"contextWindow": 128000
}
]
}
```
Prices are per 1 million tokens and reflect what your account is charged when you call the model. `contextWindow` may be `null` for models that don't report it.
### Authentication
Authenticate with either your platform JWT (for session-based clients like the dashboard) or a personal API key. Personal keys must have the `ai:gateway` scope to access these endpoints. See [Personal API keys](#personal-api-keys) below.
### Errors
Errors are returned in OpenAI-compatible shape:
```json
{ "error": { "message": "...", "type": "...", "code": "..." } }
```
| Status | `error.type` | `error.code` | When |
|---|---|---|---|
| 401 | `authentication_error` | `missing_credentials` | No `Authorization` header. |
| 401 | `authentication_error` | `invalid_api_key` | Token is unknown, revoked, or expired. |
| 403 | `permission_error` | `insufficient_scope` | API key is missing the `ai:gateway` scope. |
| 402 | `billing_error` | `insufficient_credits` | Account balance is too low for the requested call. |
| 404 | `invalid_request_error` | `model_not_found` | Requested model id isn't available. |
| 400 | `invalid_request_error` | `invalid_request` | Request body failed validation. |
| 5xx | `api_error` | (varies) | Temporary upstream issue. Retry with backoff. |
## Chat completions
```json
POST /v1/{app_id}/chat/completions
Authorization: Bearer {token}
{
"model": "anthropic/claude-3.5-sonnet",
"messages": [
{ "role": "system", "content": "You are a helpful assistant." },
{ "role": "user", "content": "Hello!" }
],
"max_tokens": 500,
"temperature": 0.7,
"stream": false
}
```
Standard OpenAI-compatible response format. Set `"stream": true` for server-sent events.
## Embeddings
```json
POST /v1/{app_id}/embeddings
Authorization: Bearer {token}
{
"model": "openai/text-embedding-3-small",
"input": "What is Butterbase?",
"encoding_format": "float"
}
```
| Parameter | Description |
|-----------|-------------|
| `model` | Embedding model ID (required) |
| `input` | String or array of strings (required) |
| `encoding_format` | `"float"` (default) or `"base64"` |
### Available embedding models
| Model | ID | Dimensions |
|-------|-----|------------|
| Text Embedding 3 Small | `openai/text-embedding-3-small` | 1536 |
| Text Embedding 3 Large | `openai/text-embedding-3-large` | 3072 |
| Text Embedding Ada 002 | `openai/text-embedding-ada-002` | 1536 |
## Video generation
Video generation is **asynchronous**. You submit a job, poll for status, then download the bytes when it's done. A single video typically takes 30 seconds to several minutes depending on model and length.
### Endpoints
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/videos/completions | Submit a generation job |
| GET | /v1/\{app_id}/videos/completions/\{job_id} | Poll job status (also downloads when terminal) |
| GET | /v1/\{app_id}/videos/completions/\{job_id}/content?index=N | Stream the rendered MP4 |
### Choosing a model
The video models in your gateway appear in `GET /v1/{app_id}/ai/models` alongside chat and embedding models. Look for the ones whose IDs begin with provider prefixes for video families (e.g. `bytedance/seedance-…`, `kwaivgi/kling-…`, `pixverse/…`, `google/veo-…`). If you POST a video model to `/chat/completions`, Butterbase returns `400 USE_VIDEO_ENDPOINT` with the correct URL in the message.
### 1. Submit a job
**curl:**
```bash
curl -X POST "https://api.butterbase.ai/v1/$APP_ID/videos/completions" \
-H "Authorization: Bearer $BUTTERBASE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "bytedance/seedance-2.0-fast",
"prompt": "A golden retriever running through sunflowers at sunset, cinematic",
"duration": 4,
"resolution": "720p",
"aspect_ratio": "16:9"
}'
```
**TypeScript (fetch):**
```typescript
const res = await fetch(`${BUTTERBASE_API_URL}/v1/${APP_ID}/videos/completions`, {
method: 'POST',
headers: {
'Authorization': `Bearer ${apiKey}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
model: 'bytedance/seedance-2.0-fast',
prompt: 'A golden retriever running through sunflowers at sunset, cinematic',
duration: 4,
resolution: '720p',
aspect_ratio: '16:9',
}),
});
const job = await res.json();
// { job_id, status: 'pending', polling_url }
```
**Python (requests):**
```python
import os, requests
res = requests.post(
f"{os.environ['BUTTERBASE_API_URL']}/v1/{APP_ID}/videos/completions",
headers={"Authorization": f"Bearer {os.environ['BUTTERBASE_API_KEY']}"},
json={
"model": "bytedance/seedance-2.0-fast",
"prompt": "A golden retriever running through sunflowers at sunset, cinematic",
"duration": 4,
"resolution": "720p",
"aspect_ratio": "16:9",
},
)
job = res.json()
# {"job_id": "...", "status": "pending", "polling_url": "..."}
```
**Response (202 Accepted):**
```json
{
"job_id": "5cd4be3e-c65e-4524-97cf-4595a76e2096",
"status": "pending",
"polling_url": "https://api.butterbase.ai/v1/{app_id}/videos/completions/5cd4be3e-c65e-4524-97cf-4595a76e2096"
}
```
**Request fields:**
| Field | Required | Description |
|-------|----------|-------------|
| `model` | yes | Video model ID (see "Choosing a model" above). |
| `prompt` | yes | Text description of the video to generate. |
| `duration` | no | Length in seconds. Model-specific (commonly 4, 6, 8). |
| `resolution` | no | e.g. `720p`, `1080p`. Model-specific. |
| `aspect_ratio` | no | e.g. `16:9`, `9:16`, `1:1`. Model-specific. |
| `generate_audio` | no | Boolean. Some models can render audio alongside video. |
| `seed` | no | Integer for deterministic generation (not all providers honor this). |
| `input_images` | no | Array of HTTPS image URLs for image-to-video / first-frame guidance. |
### 2. Poll for status
Poll the URL from `polling_url` every 30 seconds until `status` is terminal (`completed`, `failed`, `cancelled`, or `expired`).
**curl:**
```bash
curl "https://api.butterbase.ai/v1/$APP_ID/videos/completions/$JOB_ID" \
-H "Authorization: Bearer $BUTTERBASE_API_KEY"
```
**TypeScript:**
```typescript
async function poll(jobUrl: string, apiKey: string) {
while (true) {
const res = await fetch(jobUrl, { headers: { Authorization: `Bearer ${apiKey}` } });
const job = await res.json();
if (['completed', 'failed', 'cancelled', 'expired'].includes(job.status)) return job;
await new Promise(r => setTimeout(r, 30_000));
}
}
```
**Python:**
```python
import time, requests
def poll(job_url, api_key):
while True:
job = requests.get(job_url, headers={"Authorization": f"Bearer {api_key}"}).json()
if job["status"] in {"completed", "failed", "cancelled", "expired"}:
return job
time.sleep(30)
```
**Response (when `completed`):**
```json
{
"job_id": "5cd4be3e-c65e-4524-97cf-4595a76e2096",
"status": "completed",
"model": "bytedance/seedance-2.0-fast",
"polling_url": "https://api.butterbase.ai/v1/{app_id}/videos/completions/5cd4be3e-...",
"content_urls": [
"https://api.butterbase.ai/v1/{app_id}/videos/completions/5cd4be3e-.../content?index=0"
],
"error": null,
"created_at": "2026-05-24T09:59:10.738Z",
"charged_credits_usd": 0.72576,
"settled_at": "2026-05-24T10:00:56.769Z"
}
```
- `content_urls` is an array because some models render multiple variants. Use `?index=N` to pick one.
- `charged_credits_usd` is populated once the job settles (first terminal poll). It's `null` while pending or in progress.
- For `status: "failed"`, `error` carries the upstream message.
### 3. Download the video
The URLs in `content_urls` are absolute and require the same `Bearer` API key. They stream `video/mp4` bytes.
**curl:**
```bash
curl -L "$CONTENT_URL" \
-H "Authorization: Bearer $BUTTERBASE_API_KEY" \
--output video.mp4
```
**TypeScript:**
```typescript
const mp4 = await fetch(job.content_urls[0], { headers: { Authorization: `Bearer ${apiKey}` } });
const buf = Buffer.from(await mp4.arrayBuffer());
fs.writeFileSync('video.mp4', buf);
```
**Python:**
```python
import requests
with requests.get(job["content_urls"][0],
headers={"Authorization": f"Bearer {api_key}"}, stream=True) as r:
with open("video.mp4", "wb") as f:
for chunk in r.iter_content(8192):
f.write(chunk)
```
### Error codes
| Status | Code | Meaning |
|--------|------|---------|
| 400 | `USE_VIDEO_ENDPOINT` | You sent a video model to `/chat/completions`; use `/videos/completions` instead. |
| 400 | `INVALID_INDEX` | `?index=` was not a non-negative integer. |
| 402 | `INSUFFICIENT_CREDITS` | Your credit balance is below the organization's credit floor, so no new job is admitted. Response includes `balance_usd` (your combined monthly allowance + top-up balance), `credit_floor_usd` (the lowest balance at which calls are still accepted — `0` unless credit has been extended to you), and your auto-refill state. |
| 403 | `FORBIDDEN` | You're not the submitter of this job. |
| 404 | `MODEL_NOT_FOUND` | Unknown model ID. |
| 404 | `JOB_NOT_FOUND` | Unknown job ID, or the job belongs to a different app. |
| 409 | `JOB_NOT_COMPLETED` | You requested `/content` but the job hasn't reached `completed`. |
| 502 | `MODEL_UNAVAILABLE` | Upstream temporarily unavailable. Retry. |
### Jobs survive across polls
Each job is persisted. You can poll from any client / process — there's no in-memory state. Lost the `polling_url`? It's `https://api.butterbase.ai/v1/{app_id}/videos/completions/{job_id}`.
If you stop polling before the job completes, the credit reservation is automatically released after a few minutes and any upstream charge that occurred is on us. Just don't expect to retrieve the video later — re-submit.
## Image generation
Image generation follows the same async submit → poll → download shape as video. Most models complete in 5–30 seconds. Unlike `/chat/completions`, the image endpoint accepts image-native parameters (`size`, `aspect_ratio`, `seed`, `n`, reference images, masks) which the chat surface can't express.
### Endpoints
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/images/completions | Submit a generation job |
| GET | /v1/\{app_id}/images/completions/\{job_id} | Poll job status |
| GET | /v1/\{app_id}/images/completions/\{job_id}/content?index=N | Stream the rendered PNG/JPEG |
### Choosing a model
Image models appear in `GET /v1/{app_id}/ai/models` alongside chat and video. Available at launch:
| Family | Model IDs |
|--------|-----------|
| OpenAI | `openai/gpt-image-2`, `openai/gpt-image-1`, `openai/gpt-image-1-mini` |
| Google (Nano Banana) | `google/gemini-3-pro-image-preview`, `google/gemini-3.1-flash-image-preview`, `google/gemini-2.5-flash-image` |
| ByteDance Seedream | `bytedance/seedream-5-pro`, `bytedance/seedream-5-lite`, `bytedance/seedream-4-5` |
| Alibaba Wan | `alibaba/wan-2.7-image-pro`, `alibaba/wan-2.7-image`, `alibaba/wan-2.6-t2i`, `alibaba/wan-2.6-image` |
| PrunaAI | `prunaai/p-image`, `prunaai/p-image-edit` |
Each model exposes a **different subset** of parameters. Submitting an unsupported param returns `400 UNSUPPORTED_PARAM` with the full whitelist of what that model does accept — no silent drops.
### 1. Submit a job
**curl:**
```bash
curl -X POST "https://api.butterbase.ai/v1/$APP_ID/images/completions" \
-H "Authorization: Bearer $BUTTERBASE_API_KEY" \
-H "Content-Type: application/json" \
-d '{
"model": "openai/gpt-image-2",
"prompt": "A serene mountain lake at sunset, photorealistic",
"size": "1024x1024",
"n": 1
}'
```
**TypeScript (fetch):**
```typescript
const res = await fetch(`${BUTTERBASE_API_URL}/v1/${APP_ID}/images/completions`, {
method: 'POST',
headers: {
'Authorization': `Bearer ${apiKey}`,
'Content-Type': 'application/json',
},
body: JSON.stringify({
model: 'google/gemini-3-pro-image-preview',
prompt: 'A serene mountain lake at sunset, photorealistic',
aspect_ratio: '16:9',
}),
});
const job = await res.json();
// { job_id, status: 'pending', polling_url }
```
**Python (requests):**
```python
import os, requests
res = requests.post(
f"{os.environ['BUTTERBASE_API_URL']}/v1/{APP_ID}/images/completions",
headers={"Authorization": f"Bearer {os.environ['BUTTERBASE_API_KEY']}"},
json={
"model": "alibaba/wan-2.7-image-pro",
"prompt": "A cat wearing a spacesuit",
"size": "2K",
"seed": 42,
},
)
job = res.json()
# {"job_id": "...", "status": "pending", "polling_url": "..."}
```
**Response (202 Accepted):**
```json
{
"job_id": "0776b4a1-aef9-4fbc-8ac6-18255aa18614",
"status": "pending",
"polling_url": "https://api.butterbase.ai/v1/{app_id}/images/completions/0776b4a1-aef9-4fbc-8ac6-18255aa18614"
}
```
**Request fields:**
| Field | Required | Description |
|-------|----------|-------------|
| `model` | yes | Image model ID (see table above). |
| `prompt` | yes | Text description of the image to generate. |
| `size` | no | e.g. `1024x1024`, `1536x1024`, or symbolic like `1K` / `2K` / `4K`. Model-specific. |
| `aspect_ratio` | no | e.g. `16:9`, `1:1`. Gemini and Pruna families only. |
| `n` | no | Number of images to generate. GPT Image 2 / 1 / 1-mini only. |
| `seed` | no | Integer for deterministic generation. Wan, Pruna, GPT Image 2, and a few OpenRouter models. |
| `input_images` | no | Array of HTTPS image URLs for image-to-image or reference guidance (up to 14 refs on most models). |
| `mask` | no | HTTPS URL of an alpha mask for edit mode. GPT Image 2 only. |
| `negative_prompt` | no | Text description of what to avoid. Wan 2.6 only. |
| `provider` | no | Object of model-specific params (e.g. Wan's `bbox_list` / `color_palette`, GPT's `quality` / `background`, Seedream's `optimize_prompt_options`). Validated against the model's provider-param whitelist. |
**Image URL aliases:** For convenience, top-level keys `image`, `image_url`, `image_uri`, `reference_image`, `input_image`, and `starting_image` are folded into `input_images[]` before validation. Only `mask` remains a distinct top-level field.
### 2. Poll for status
Poll the URL from `polling_url` every 2–5 seconds until `status` is terminal (`completed`, `failed`, `cancelled`, or `expired`).
**curl:**
```bash
curl "https://api.butterbase.ai/v1/$APP_ID/images/completions/$JOB_ID" \
-H "Authorization: Bearer $BUTTERBASE_API_KEY"
```
**TypeScript:**
```typescript
async function poll(jobUrl: string, apiKey: string) {
while (true) {
const res = await fetch(jobUrl, { headers: { Authorization: `Bearer ${apiKey}` } });
const job = await res.json();
if (['completed', 'failed', 'cancelled', 'expired'].includes(job.status)) return job;
await new Promise(r => setTimeout(r, 2_000));
}
}
```
**Python:**
```python
import time, requests
def poll(job_url, api_key):
while True:
job = requests.get(job_url, headers={"Authorization": f"Bearer {api_key}"}).json()
if job["status"] in {"completed", "failed", "cancelled", "expired"}:
return job
time.sleep(2)
```
**Response (when `completed`):**
```json
{
"job_id": "0776b4a1-aef9-4fbc-8ac6-18255aa18614",
"status": "completed",
"model": "openai/gpt-image-2",
"polling_url": "https://api.butterbase.ai/v1/{app_id}/images/completions/0776b4a1-...",
"content_urls": [
"https://api.butterbase.ai/v1/{app_id}/images/completions/0776b4a1-.../content?index=0"
],
"error": null,
"created_at": "2026-07-15T02:57:44.271Z",
"charged_credits_usd": 0.010168,
"settled_at": "2026-07-15T02:58:04.512Z"
}
```
- `content_urls` is an array — with `n > 1` on GPT Image, one entry per generated image.
- `charged_credits_usd` is populated once the job settles (first terminal poll). It's `null` while pending or in progress.
- For `status: "failed"`, `error` carries the upstream message.
### 3. Download the image
The URLs in `content_urls` are absolute and require the same `Bearer` API key. They stream PNG or JPEG bytes (see the `Content-Type` header — varies per model / request).
**curl:**
```bash
curl -L "$CONTENT_URL" \
-H "Authorization: Bearer $BUTTERBASE_API_KEY" \
--output image.png
```
**TypeScript:**
```typescript
const img = await fetch(job.content_urls[0], { headers: { Authorization: `Bearer ${apiKey}` } });
const buf = Buffer.from(await img.arrayBuffer());
// Content-Type header tells you the format: image/png, image/jpeg, image/webp
```
### Errors
Same taxonomy as video generation, plus one image-specific code:
| Status | Code | Meaning |
|--------|------|---------|
| 400 | `UNSUPPORTED_PARAM` | Request included a param the target model doesn't accept. Response body lists `supported_top_level` and `supported_provider` for that model. |
| 400 | `WRONG_MODALITY` | Model isn't an image model (probably a chat or video model). |
| 402 | `INSUFFICIENT_CREDITS` | App is out of credits. |
| 404 | `JOB_NOT_FOUND` | jobId doesn't exist or belongs to another end-user. |
| 409 | `JOB_NOT_COMPLETED` | Requested `/content` on a job that hasn't reached terminal status. |
| 502 | `MODEL_UNAVAILABLE` | Upstream temporarily unavailable. Retry. |
### Notes on URL expiration
Content URLs are backed by the upstream provider's storage, which typically expires **~30 days** after generation. If you need long-term storage, download the image and mirror it to your own bucket (Butterbase Storage works well) before the window closes.
### Concurrency
There is no per-app or per-key concurrency cap on the Butterbase side — fire off as many parallel POSTs as your credit balance covers, and poll each returned `job_id` independently. Upstream rate limits from the underlying model provider are the only ceiling; if you hit one, you'll get a `429` with the specific upstream error surfaced.
## Configuration
```json
PUT /v1/{app_id}/ai/config
{
"defaultModel": "anthropic/claude-3.5-sonnet",
"maxTokensPerRequest": 4096,
"allowedModels": ["anthropic/claude-3.5-sonnet"]
}
```
| Field | Description |
|-------|-------------|
| `defaultModel` | Model used when none specified |
| `maxTokensPerRequest` | Token limit per request (1-100,000) |
| `allowedModels` | Restrict allowed models |
## Usage
```
GET /v1/{app_id}/ai/usage?startDate=2026-01-01&endDate=2026-01-31
```
**Response:**
```json
{
"totalTokens": 150000,
"totalCost": 0.45,
"byModel": {
"anthropic/claude-3.5-sonnet": {
"tokens": 120000,
"cost": 0.40,
"requests": 25
}
}
}
```
## Personal API keys
To call the gateway endpoints from outside the dashboard (scripts, CLIs, the OpenAI SDK), mint a personal API key with the `ai:gateway` scope.
```json
POST /api-keys
Authorization: Bearer {jwt}
{
"name": "my-cli",
"scopes": ["ai:gateway"]
}
```
The response contains the plaintext key once — store it immediately. Subsequent requests show only the prefix.
### Scopes
| Scope | Grants |
|---|---|
| `*` | Full access to all Butterbase APIs the user can use. |
| `ai:gateway` | Access to `POST /v1/chat/completions`, `POST /v1/embeddings`, and `GET /v1/models`. Nothing else. |
The dashboard at `/api-keys` lists and revokes keys; for now, scoping a key to `ai:gateway` is done by calling `POST /api-keys` directly.
## Meeting bots
`ctx.ai.meetings` lets your app spawn a bot that joins a Zoom, Google Meet, Microsoft Teams, or Webex call, records it, and transcribes the audio. Your app starts a bot via the REST API or SDK, then waits for webhook events to learn when the call ends and the artifacts (recording, transcript) are ready to download. Recordings and transcripts are billed against the app's AI credit balance using the same ledger as chat completions.
### Endpoints
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/ai/meetings | Start a bot |
| GET | /v1/ai/meetings/\{bot_id} | Get bot status + artifact URLs |
| DELETE | /v1/ai/meetings/\{bot_id} | Stop a bot |
| GET | /v1/ai/meetings | List bots |
| GET | /v1/ai/meetings/_estimate | Estimate cost up front |
### Start a bot
**Request:**
```json
POST /v1/ai/meetings
Authorization: Bearer bb_sk_...
{
"meetingUrl": "https://meet.google.com/abc-defg-hij",
"transcript": true,
"recording": "mp4",
"metadata": {
"dealId": "d_42"
}
}
```
**Request fields:**
| Field | Type | Required | Default | Description |
|-------|------|----------|---------|-------------|
| `meetingUrl` | string | yes | — | Full URL of the meeting to join. |
| `transcript` | boolean | no | `true` | Whether to generate a transcript. |
| `recording` | `"mp4" \| "audio_only" \| false` | no | `"mp4"` | Recording format, or `false` to skip recording. |
| `metadata` | `Record` | no | `{}` | Arbitrary key–value pairs stored on the bot. Keys starting with `bb_` are reserved and will be rejected with `400`. |
**Response (201 Created):**
```json
{
"id": "bot_01j9...",
"status": "joining",
"startedAt": null,
"completedAt": null,
"durationSeconds": null,
"recordingUrl": null,
"transcriptUrl": null,
"metadata": {
"dealId": "d_42"
}
}
```
The `MeetingBot` shape is the same for all endpoints that return a bot.
### Bot status lifecycle
Bots move through these states in order:
| Status | Meaning |
|--------|---------|
| `joining` | Bot is dialing into the meeting. |
| `waiting_room` | Bot reached the meeting but is held in the waiting room. |
| `in_call` | Bot has been admitted to the call. |
| `recording` | Bot is actively recording (and transcribing, if enabled). |
| `ended` | The call has ended; artifacts are being processed. |
| `done` | Artifacts are ready. `recordingUrl` and `transcriptUrl` (if applicable) are now populated. |
| `fatal` | Bot encountered an unrecoverable error. Check `status` for details and the `bot.fatal` webhook. |
### SDK usage
```ts
import { butterbase } from '@butterbase/sdk';
const bb = butterbase({ apiKey: '...', appId: '...' });
// Start a bot
const { data: bot, error } = await bb.ai.meetings.start({
meetingUrl: 'https://meet.google.com/abc-defg-hij',
transcript: true,
recording: 'mp4',
metadata: { dealId: 'd_42' },
});
// Later, after the webhook tells you the bot is done:
const { data: finished } = await bb.ai.meetings.get(bot!.id);
// finished.recordingUrl + finished.transcriptUrl are now populated
```
Additional SDK methods:
```ts
// Stop a bot early
await bb.ai.meetings.stop(bot!.id);
// List bots with optional filters
const { data: bots } = await bb.ai.meetings.list({ status: 'done', limit: 20, cursor: '...' });
// Estimate cost before dispatching
const { data: estimate } = await bb.ai.meetings.estimateCost({ durationMinutes: 60, transcript: true });
// estimate.usd — projected total charge
```
### Pricing
Recording: **$0.50/hr + markup**, prorated per second. Transcription: **$0.15/hr + markup**, also prorated per second. Both charges are applied to the app's AI credit balance once the bot reaches `done` status.
Use `GET /v1/ai/meetings/_estimate?durationMinutes=N&transcript=true` to project the charge before dispatching a bot.
### Webhook events
Apps receive forwarded events at the URL configured via `manage_ai`'s `configure_meetings_webhook` action. Butterbase re-signs each forwarded event before delivery.
**Event types:**
| Event | When it fires |
|-------|---------------|
| `bot.in_call_recording` | Bot has been admitted and recording has started. |
| `bot.done` | Bot left the call; recording artifact is available. |
| `bot.fatal` | Bot failed; check bot status for details. |
| `recording.done` | Recording artifact is ready to download. |
| `transcript.done` | Transcript artifact is ready to download. |
| `transcript.failed` | Transcription failed for this bot. |
**Payload shape:**
```json
POST
Content-Type: application/json
x-bb-event: bot.done
x-bb-signature: v1,
x-bb-key-id: <16-char identifier>
{
"event": "bot.done",
"data": { /* event-specific payload */ }
}
```
### Signature & freshness
The `x-bb-signature` header is an HMAC-SHA256 of the raw request body bytes, signed with Butterbase's webhook signing key. A valid signature confirms the event originated from Butterbase's infrastructure. Full per-tenant HMAC verification (where each app has its own signing key) is on the roadmap. For now, verify the request arrived over TLS from a Butterbase-owned origin, and confirm that `x-bb-key-id` matches the first 16 characters of the secret returned on the most recent `rotate_secret` call. If it does not match, the event was signed before your latest key rotation — treat it as stale and drop it.
**Do not trigger side-effects (database writes, downstream calls) on duplicate deliveries.** Use the event payload's `bot.id` combined with the event name as an idempotency key. The upstream delivery service may retry for up to 24 hours.
### Limits
- **Single region.** In v1, bots are spawned from the US East workspace. Latency-sensitive multi-region routing is on the roadmap.
- **No hard duration cap.** Bots run until the call ends or the app's AI credit balance is exhausted.
- **Artifact retention.** Recording and transcript artifacts are retained for 7 days after the call ends. Download them before the retention window expires.
---
## API Reference / AI Meetings API
Endpoints for spawning meeting bots, inspecting their lifecycle, retrieving recordings + transcripts, and configuring webhook delivery. See [AI Meetings](/core-concepts/ai-meetings/) for the conceptual overview and a complete worked example.
All endpoints are app-scoped — the `app_id` lives in the URL path, and the call is authenticated with a Butterbase service-key (`bb_sk_...`) belonging to that app's owner.
## Endpoints
| Method | Path | Purpose |
|---|---|---|
| POST | /v1/\{app_id\}/ai/meetings | Spawn a meeting bot |
| GET | /v1/\{app_id\}/ai/meetings/\{bot_id\} | Get one bot — status, duration, URLs |
| DELETE | /v1/\{app_id\}/ai/meetings/\{bot_id\} | Force the bot to leave the call |
| GET | /v1/\{app_id\}/ai/meetings | List this app's bots |
| GET | /v1/\{app_id\}/ai/meetings/\_estimate | Predict the USD charge for a session |
| GET | /v1/\{app_id\}/ai/meetings/usage | Recent `actor_usage_logs` rows for the app |
| PUT | /v1/\{app_id\}/ai/meetings/webhook | Configure forward URL + (re)mint signing secret |
| GET | /v1/ai/meetings/\_status | Public — `{ "available": true \| false }` |
## Spawn a bot
```
POST /v1/{app_id}/ai/meetings
Authorization: Bearer {token}
Content-Type: application/json
{
"meetingUrl": "https://zoom.us/j/12345...",
"transcript": true,
"recording": "mp4",
"botName": "Acme Notetaker",
"metadata": { "session_id": "abc123" },
"automaticLeave": {
"waitingRoomTimeoutSec": 900,
"noOneJoinedTimeoutSec": 600,
"everyoneLeftTimeoutSec": 120,
"inCallNotRecordingTimeoutSec": 1800
}
}
```
| Field | Type | Default | Notes |
|---|---|---|---|
| `meetingUrl` | string | required | Any Zoom / Meet / Teams / Webex URL |
| `transcript` | boolean | `true` | Transcribe in addition to recording |
| `recording` | `"mp4" \| "audio_only" \| false` | `"mp4"` | `false` skips recording entirely |
| `botName` | string | `"Butterbase Notetaker"` | Display name the bot uses when it joins the call. 1–64 chars |
| `metadata` | `Record` | `{}` | Arbitrary string→string map. Keys may not start with `bb_` (reserved) |
| `automaticLeave` | object | `{}` | Per-bot overrides for the auto-leave timers. Any sub-field you omit inherits the provider default. See [Auto-leave timers](#auto-leave-timers). |
### Auto-leave timers
Tell the bot when to give up and leave on its own. All sub-fields are optional; omitted ones fall back to the provider's default. All values are positive integers in **seconds** (max `86400` = 24h).
| Sub-field | Triggers when… |
|---|---|
| `waitingRoomTimeoutSec` | Bot has been stuck in the waiting room (host hasn't admitted it) for this many seconds. |
| `noOneJoinedTimeoutSec` | Bot is in the call but no participants ever joined within this many seconds. |
| `everyoneLeftTimeoutSec` | All participants have left and this many seconds pass with the room empty. |
| `inCallNotRecordingTimeoutSec` | Bot is in the call but not recording (e.g. recording consent denied) for this many seconds. |
**Example — make the bot leave if not admitted within 15 minutes:**
```json
{ "automaticLeave": { "waitingRoomTimeoutSec": 900 } }
```
Response:
```json
{
"id": "c086e720-d319-44b8-82d8-3a363f2cd9f4",
"status": "joining",
"startedAt": null,
"completedAt": null,
"durationSeconds": null,
"recordingUrl": null,
"transcriptUrl": null,
"botName": "Acme Notetaker",
"metadata": { "session_id": "abc123" }
}
```
`botName` is echoed back so callers can confirm what was sent. Bots created before this field was supported come back with `"Butterbase Notetaker"`.
`startedAt` / `completedAt` / URLs populate as the bot progresses. Poll `GET /v1/{app_id}/ai/meetings/{id}` or rely on webhooks.
## Get a bot
```
GET /v1/{app_id}/ai/meetings/{bot_id}
Authorization: Bearer {token}
```
Returns the same shape as `POST`. The `status` field moves through:
| Status | Meaning |
|---|---|
| `joining` | Bot is dialing in |
| `waiting_room` | Bot is in the waiting room awaiting host admit |
| `in_call` | Bot is in the call (recording may not have started yet) |
| `recording` | Recording in progress |
| `ended` | Call ended; artifacts being finalised |
| `done` | Terminal — call finished cleanly, `recordingUrl` + `transcriptUrl` available |
| `fatal` | Terminal — bot failed to join, was kicked, or had a fatal error |
## List bots
```
GET /v1/{app_id}/ai/meetings?status={status}&limit={n}&cursor={cursor}
Authorization: Bearer {token}
```
Query params (all optional):
| Param | Type | Default | Notes |
|---|---|---|---|
| `status` | string | — | Filter to one lifecycle phase |
| `limit` | integer | 20 | 1–100 |
| `cursor` | string | — | From `nextCursor` in a prior response |
Response:
```json
{
"bots": [ /* MeetingBot[] */ ],
"nextCursor": "..." | null
}
```
## Stop a bot
```
DELETE /v1/{app_id}/ai/meetings/{bot_id}
Authorization: Bearer {token}
```
Forces the bot to leave the call. Returns `204` on success. Idempotent — a stopped or already-done bot still returns `204`.
## Cost estimate
```
GET /v1/{app_id}/ai/meetings/_estimate?durationMinutes={n}&transcript={bool}
Authorization: Bearer {token}
```
| Param | Type | Default | Notes |
|---|---|---|---|
| `durationMinutes` | integer | required | 1 – 1440 |
| `transcript` | boolean | `true` | Whether to include transcription cost |
Response:
```json
{ "usd": 0.39 }
```
## Configure forward webhook
```
PUT /v1/{app_id}/ai/meetings/webhook
Authorization: Bearer {token}
Content-Type: application/json
{
"forward_url": "https://your-app.example.com/recall/events",
"rotate_secret": true
}
```
| Field | Type | Notes |
|---|---|---|
| `forward_url` | string (URL) | Where Butterbase will POST forwarded events |
| `rotate_secret` | boolean | If true (or no row exists yet), mint a fresh per-app secret |
Response:
```json
{
"ok": true,
"app_id": "app_abc123",
"forward_url": "https://your-app.example.com/recall/events",
"secret": "wsec_..."
}
```
`secret` is returned **once** — only on initial create and when `rotate_secret: true`. Store it immediately. On subsequent calls without `rotate_secret`, `secret` is `null`. Butterbase stores the value AES-256-GCM-encrypted; the platform decrypts it transiently each time it signs an outbound forward.
### Forwarded event shape
When the bot's status advances or an artifact becomes ready, Butterbase POSTs to your `forward_url`:
```
POST /your/configured/path
content-type: application/json
x-bb-event: bot.done
x-bb-signature: v1,
{
"event": "bot.done",
"data": {
"bot": { "id": "c086e720-...", "metadata": { ... } },
"data": { "code": "done", "sub_code": null, "updated_at": "..." }
}
}
```
### Verifying the signature
Recompute `base64(HMAC-SHA256(, ))`, prefix with `v1,`, and compare to `x-bb-signature` in constant time. The full Stripe / GitHub / Recall.ai webhook pattern — see the [worked example](/core-concepts/ai-meetings/#verifying-a-forwarded-event).
### Default subscriptions
Each new app gets these events forwarded by default:
- `bot.in_call_recording`
- `bot.done`
- `bot.fatal`
- `recording.done`
- `transcript.done`
- `transcript.failed`
### Webhook payloads carry IDs, not URLs
`recording.done` and `transcript.done` events deliver only the artifact **id** and metadata. To get a downloadable URL, follow up with `GET /v1/{app_id}/ai/meetings/{bot_id}` and read `recordingUrl` / `transcriptUrl` from the response. URLs are short-lived (Recall re-mints them on demand), which is why they're not baked into the webhook payload.
## Usage
```
GET /v1/{app_id}/ai/meetings/usage
Authorization: Bearer {token}
```
Returns the last 100 rows from `actor_usage_logs`:
```json
{
"rows": [
{
"id": "5",
"dimension": "recording",
"seconds": 44,
"usd_charged": "0.007333",
"created_at": "2026-06-11T19:18:53.734Z"
},
{
"id": "4",
"dimension": "transcription",
"seconds": 44,
"usd_charged": "0.002200",
"created_at": "2026-06-11T19:18:53.485Z"
}
]
}
```
One row per dimension (`recording` and, when transcription was enabled, `transcription`) per completed session.
## Availability
```
GET /v1/ai/meetings/_status
```
No auth — public. Returns:
```json
{ "available": true }
```
`false` means the provider isn't registered on this deployment (e.g. an OSS-mode deployment without `MEETINGS_API_KEY` set). Use this to gate UI affordances client-side.
## Errors
OpenAI-shaped: `{ "error": { "message", "type", "code" } }`.
| Status | `error.type` | `error.code` | When |
|---|---|---|---|
| 400 | `invalid_request_error` | `invalid_request` | Request body failed validation. `error.details` has the zod issues. |
| 401 | `authentication_error` | `missing_credentials` | No / invalid Authorization header. |
| 402 | `billing_error` | `insufficient_credits` | Your credit balance is below the organization's credit floor, so no new call is admitted. `error.balance_usd` (combined monthly allowance + top-up balance) and `error.credit_floor_usd` (the lowest balance at which calls are still accepted — `0` unless credit has been extended to you) are included. |
| 403 | `permission_error` | `not_authorized` | Authenticated user doesn't own this app. |
| 404 | `invalid_request_error` | `app_not_found` | `app_id` doesn't exist. |
| 501 | `api_error` | `provider_unavailable` | Meetings adapter isn't registered on this deployment. |
| 5xx | `api_error` | (varies) | Upstream provider error. Retry with backoff. |
---
## API Reference / Auth API
All auth routes are scoped by `{app_id}`. Each app has independent user accounts and tokens.
## Endpoints
| Method | Path | Rate Limit | Purpose |
|--------|------|------------|---------|
| POST | /auth/\{app_id}/signup | 5/15min | Register a new user |
| POST | /auth/\{app_id}/login | 10/15min | Sign in |
| POST | /auth/\{app_id}/magic-link | 5/15min | Send a 6-digit sign-in code by email |
| POST | /auth/\{app_id}/magic-link/verify | 10/15min | Exchange a code for tokens |
| POST | /auth/\{app_id}/refresh | 20/15min | Refresh access token |
| POST | /auth/\{app_id}/logout | Auth required | End session |
| POST | /auth/\{app_id}/verify-email | 10/15min | Verify email with code |
| POST | /auth/\{app_id}/forgot-password | 3/15min | Request reset code |
| POST | /auth/\{app_id}/reset-password | 5/15min | Reset password |
| GET | /auth/\{app_id}/me | Auth required | Get current user profile |
| GET | /auth/\{app_id}/.well-known/jwks.json | Cached 5min | Public keys for token verification |
## OAuth endpoints
| Method | Path | Purpose |
|--------|------|---------|
| GET | /auth/\{app_id}/oauth/\{provider}?redirect_to=\{url} | Start OAuth flow |
| GET | /auth/\{app_id}/oauth/\{provider}/callback | OAuth callback |
| POST | /auth/\{app_id}/oauth/\{provider}/callback | POST callback (Apple) |
## OAuth configuration
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/auth/oauth-config | Register a provider |
| GET | /v1/\{app_id}/auth/oauth-config | List all providers |
| GET | /v1/\{app_id}/auth/oauth-config/\{provider} | Get provider config |
| PATCH | /v1/\{app_id}/auth/oauth-config/\{provider} | Update a provider |
| DELETE | /v1/\{app_id}/auth/oauth-config/\{provider} | Remove a provider |
### Register a provider
```json
POST /v1/{app_id}/auth/oauth-config
{
"provider": "google",
"client_id": "YOUR_CLIENT_ID.apps.googleusercontent.com",
"client_secret": "YOUR_CLIENT_SECRET",
"redirect_uris": ["https://api.example.com/auth/app_yourid/oauth/google/callback"]
}
```
**Built-in providers** (only need `provider`, `client_id`, `client_secret`, `redirect_uris`):
google, github, discord, facebook, linkedin, microsoft, apple, x
**Custom providers** also need: `authorization_url`, `token_url`, `userinfo_url`
### Apple provider
Requires `provider_metadata`:
```json
{
"provider": "apple",
"client_id": "com.example.app",
"client_secret": "placeholder",
"redirect_uris": ["https://api.example.com/auth/app_yourid/oauth/apple/callback"],
"provider_metadata": {
"teamId": "ABCDE12345",
"keyId": "KEY123",
"privateKey": "-----BEGIN PRIVATE KEY-----\n..."
}
}
```
## Request/response examples
### Signup
```json
POST /auth/{app_id}/signup
{
"email": "user@example.com",
"password": "MyP@ssw0rd!",
"display_name": "Jane Doe"
}
```
**Password requirements:** 8+ characters, uppercase, lowercase, number, special character.
### Login response
```json
{
"access_token": "eyJhbGciOi...",
"refresh_token": "...",
"expires_in": 3600,
"token_type": "Bearer",
"user": {
"id": "uuid",
"email": "user@example.com",
"email_verified": true,
"display_name": "Jane Doe",
"avatar_url": null
}
}
```
### Magic-link send
```json
POST /auth/{app_id}/magic-link
{ "email": "user@example.com" }
```
Response is identical whether or not the email exists (prevents enumeration):
```json
{ "message": "If an account exists with that email, a sign-in code has been sent" }
```
Codes expire after **15 minutes** and are single-use. New users are auto-created on first verify.
### Magic-link verify
```json
POST /auth/{app_id}/magic-link/verify
{ "email": "user@example.com", "code": "123456" }
```
Response shape is identical to the login response. Failure responses are HTTP 400 with one of: `Invalid sign-in code`, `Sign-in code already used`, `Sign-in code expired`.
## App configuration
| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/\{app_id}/config | Read full app config |
| PATCH | /v1/\{app_id}/config/cors | Update CORS origins |
| PATCH | /v1/\{app_id}/config/jwt | Update token lifetimes |
| PATCH | /v1/\{app_id}/config/pause | Pause / resume the app (kill-switch). Body: `{ paused: boolean, reason?: string }`. While paused, all data-plane traffic returns 503 with `code: APP_PAUSED`. Auth and control-plane endpoints stay reachable. |
## Audit logs
| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/\{app_id}/audit-logs | Query auth events. Filters: `user_id`, `event_type`, `limit`, `offset` |
---
## API Reference / Billing API
## Platform billing
| Method | Path | Purpose |
|--------|------|---------|
| GET | /dashboard/billing | Current plan, usage, and limits |
| GET | /dashboard/usage | Daily usage history |
| POST | /dashboard/billing/checkout | Start upgrade checkout |
| POST | /dashboard/billing/portal | Open billing portal |
### Usage history
```
GET /dashboard/usage?startDate=2026-01-01&endDate=2026-01-31&meterType=ai_tokens
```
| Parameter | Description |
|-----------|-------------|
| `startDate` | Start of range (ISO date) |
| `endDate` | End of range (ISO date) |
| `meterType` | Filter: `storage_bytes`, `ai_tokens`, `lambda_invocations`, `bandwidth_bytes` |
## Stripe Connect (monetization)
### Developer endpoints (platform auth)
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/billing/connect/onboard | Start Connect onboarding |
| GET | /v1/\{app_id}/billing/connect/status | Check onboarding status |
### Subscription plans
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/billing/plans | Create a plan |
| GET | /v1/\{app_id}/billing/plans | List plans |
| PUT | /v1/\{app_id}/billing/plans/\{plan_id} | Update a plan |
**Create:**
```json
{
"name": "Pro Plan",
"priceCents": 999,
"interval": "month",
"features": ["Feature 1", "Feature 2"]
}
```
### Products (one-time purchases)
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/billing/products | Create a product |
| GET | /v1/\{app_id}/billing/products | List products |
| PUT | /v1/\{app_id}/billing/products/\{product_id} | Update a product |
**Create:**
```json
{
"name": "Premium Template",
"priceCents": 2999,
"description": "50+ templates",
"metadata": { "category": "templates" }
}
```
### End user endpoints (app JWT)
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/billing/subscribe | Start subscription |
| GET | /v1/\{app_id}/billing/subscription | Current subscription |
| POST | /v1/\{app_id}/billing/cancel | Cancel at period end |
| POST | /v1/\{app_id}/billing/purchase | Purchase a product |
| GET | /v1/\{app_id}/billing/orders | List orders |
| GET | /v1/\{app_id}/billing/orders/{order_id} | Get order details |
### Webhooks
```
POST /webhooks/stripe/connect
```
Set `STRIPE_CONNECT_WEBHOOK_SECRET` in the control API environment.
Handled events: `checkout.session.completed`, `customer.subscription.updated`, `customer.subscription.deleted`, `invoice.payment_succeeded`, `invoice.payment_failed`, `payment_intent.payment_failed`, `charge.refunded`
---
## API Reference / Data API
Once tables exist in your schema, these endpoints are automatically available.
## Endpoints
| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/\{app_id}/\{table} | List rows |
| GET | /v1/\{app_id}/\{table}/\{id} | Read single row |
| POST | /v1/\{app_id}/\{table} | Create a row |
| PATCH | /v1/\{app_id}/\{table}/\{id} | Update a row |
| DELETE | /v1/\{app_id}/\{table}/\{id} | Delete a row |
## Query parameters
### Filtering
Format: `column=operator.value`
| Operator | Example | SQL |
|----------|---------|-----|
| `eq` | `status=eq.published` | `= 'published'` |
| `neq` | `status=neq.draft` | `!= 'draft'` |
| `gt` | `age=gt.18` | `> 18` |
| `gte` | `age=gte.18` | `>= 18` |
| `lt` | `price=lt.100` | `< 100` |
| `lte` | `price=lte.100` | `<= 100` |
| `like` | `title=like.%hello%` | `LIKE '%hello%'` |
| `ilike` | `title=ilike.%hello%` | `ILIKE '%hello%'` |
| `is` | `deleted_at=is.null` | `IS NULL` |
| `in` | `id=in.(1,2,3)` | `IN (1,2,3)` |
| `fts` | `title=fts.hello` | Full-text search |
### Sorting
```
?order=created_at.desc
?order=name.asc,created_at.desc
```
### Pagination
```
?limit=20&offset=40
```
### Column selection
```
?select=id,title,created_at
```
## Authentication
| Auth method | Role | Access |
|---|---|---|
| None | butterbase_anon | Public data only |
| End-user JWT | butterbase_user | User-scoped data (RLS) |
| API key (`bb_sk_...`) | butterbase_service | All data (bypasses RLS) |
## Create a row
```bash
POST /v1/{app_id}/posts
Content-Type: application/json
Authorization: Bearer {token}
{
"title": "Hello World",
"body": "My first post",
"published": true
}
```
If the table has a user isolation policy with auto-populate trigger, the `user_id` column is filled automatically.
## Update a row
```bash
PATCH /v1/{app_id}/posts/{id}
Content-Type: application/json
Authorization: Bearer {token}
{
"published": false
}
```
Only send columns you want to change.
## Delete a row
```bash
DELETE /v1/{app_id}/posts/{id}
Authorization: Bearer {token}
```
## Schema endpoints
| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/\{app_id}/schema | Read current schema |
| POST | /v1/\{app_id}/schema/apply | Apply schema update (`dry_run: true` to preview) |
| GET | /v1/\{app_id}/migrations | List applied migrations |
## App management
| Method | Path | Purpose |
|--------|------|---------|
| GET | /apps | List your apps |
| POST | /init | Create a new app. Body: `{"name": "my-app"}` |
| DELETE | /apps/\{app_id} | Delete an app permanently |
---
## API Reference / Frontend API
## Endpoints
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/frontend/deployments | Create a deployment |
| POST | /v1/\{app_id}/frontend/deployments/\{id}/start | Start a deployment |
| GET | /v1/\{app_id}/frontend/deployments | List deployment history |
| GET | /v1/\{app_id}/frontend/deployments/\{id} | Get deployment details |
| POST | /v1/\{app_id}/frontend/deployments/\{id}/sync | Force-sync status |
| POST | /v1/\{app_id}/frontend/deployments/\{id}/cancel | Cancel deployment |
| DELETE | /v1/\{app_id}/frontend/deployments/\{id} | Delete a deployment |
| PUT | /v1/\{app_id}/frontend/env | Set environment variables |
| GET | /v1/\{app_id}/frontend/env | List environment variable keys |
## Create deployment
```json
POST /v1/{app_id}/frontend/deployments
Authorization: Bearer {token}
{
"framework": "react-vite"
}
```
**Response:**
```json
{
"id": "deployment-uuid",
"uploadUrl": "https://...",
"expiresIn": 900,
"maxSizeBytes": 104857600
}
```
### Framework values
| Framework | Value |
|-----------|-------|
| React (Vite) | `react-vite` |
| Next.js (static) | `nextjs-static` |
| Static HTML | `static` |
| Other | `other` |
## Upload and start
**Upload zip:**
```bash
curl -X PUT "{uploadUrl}" \
-H "Content-Type: application/zip" \
--data-binary @frontend.zip
```
**Start deployment:**
```
POST /v1/{app_id}/frontend/deployments/{id}/start
```
## Deployment statuses
| Status | Meaning |
|--------|---------|
| `WAITING` | Created, awaiting upload |
| `UPLOADING` | Processing |
| `BUILDING` | Building |
| `READY` | Succeeded |
| `ERROR` | Failed |
| `CANCELED` | Canceled |
## Environment variables
```json
PUT /v1/{app_id}/frontend/env
{
"VITE_API_URL": "https://api.butterbase.ai/v1/app_abc123",
"NEXT_PUBLIC_API_KEY": "pk_test_123"
}
```
Values are encrypted at rest. Only keys are returned when listing.
## Limits
| Limit | Value |
|-------|-------|
| Max size | 100 MB (compressed) |
| Upload expiration | 15 minutes |
| Free plan | 1 active deployment |
| Pro plan | Unlimited |
## Custom Domains
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/custom-domains | Add a custom domain |
| GET | /v1/\{app_id}/custom-domains | List custom domains |
| GET | /v1/\{app_id}/custom-domains/\{id}/status | Check verification status |
| POST | /v1/\{app_id}/custom-domains/\{id}/verify | Re-trigger verification |
| DELETE | /v1/\{app_id}/custom-domains/\{id} | Remove a custom domain |
### Add custom domain
```json
POST /v1/{app_id}/custom-domains
Authorization: Bearer {token}
{
"hostname": "app.example.com"
}
```
**Response:**
```json
{
"domain": {
"id": "uuid",
"hostname": "app.example.com",
"status": "pending",
"ssl_status": "pending"
},
"cname_target": "butterbase.dev",
"instructions": "Add a CNAME record..."
}
```
The response `instructions` field contains the exact CNAME setup steps for your DNS provider. If your DNS is managed by Cloudflare, the record **must be set to DNS-only (grey cloud)**. Proxied (orange cloud) CNAMEs between different Cloudflare accounts produce Error 1014 and will not work.
### Check status
```
GET /v1/{app_id}/custom-domains/{id}/status
```
Returns current verification and SSL status from Cloudflare. Poll this endpoint after adding a domain (typically resolves within 5–15 minutes).
### Errors
| Error | Meaning |
|-------|---------|
| `feature_not_available` | Plan doesn't include custom domains (upgrade to Pro) |
| `RESOURCE_ALREADY_EXISTS` | Hostname is already registered |
| `RESOURCE_NOT_FOUND` | Domain ID not found |
---
## API Reference / Functions API
## Endpoints
| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/functions | Deploy or update a function |
| GET | /v1/\{app_id}/functions | List all functions |
| GET | /v1/\{app_id}/functions/\{name} | Get function details and metrics |
| DELETE | /v1/\{app_id}/functions/\{name} | Delete a function |
| POST | /v1/\{app_id}/functions/\{name}/invoke | Test-invoke a function |
| GET | /v1/\{app_id}/functions/\{name}/logs | View invocation logs |
## Public invocation
| Method | Path | Purpose |
|--------|------|---------|
| ANY | /v1/\{app_id}/fn/\{function_name} | Call a deployed function (any HTTP method) |
End-user tokens are forwarded to the function.
## Deploy a function
```json
POST /v1/{app_id}/functions
Authorization: Bearer {token}
{
"name": "hello-world",
"code": "export default async function handler(req) {\n return new Response(JSON.stringify({ message: 'Hello!' }), {\n headers: { 'Content-Type': 'application/json' }\n });\n}",
"description": "A simple greeting function",
"triggers": [
{ "type": "http", "config": { "auth": "required" } },
{ "type": "cron", "config": { "schedule": "0 9 * * *" } }
],
"envVars": {
"API_KEY": "secret123"
},
"timeoutMs": 30000,
"memoryLimitMb": 128
}
```
### Required fields
| Field | Description |
|-------|-------------|
| `name` | Unique name (1-100 characters) |
| `code` | Source code with default export handler |
### Optional fields
| Field | Default | Description |
|-------|---------|-------------|
| `description` | — | What the function does |
| `envVars` | — | Environment variables (encrypted). The platform also auto-injects `BUTTERBASE_*` keys at runtime — see [Platform context](/core-concepts/functions/#platform-context). Platform keys are injected after your `envVars` so you can't shadow them. On redeploy, `envVars` merge into the existing env (incoming keys win); omit it to leave the env untouched. |
| `envVarsReplace` | `false` | Set `true` to replace the function's entire env with `envVars` instead of merging. |
| `timeoutMs` | 30000 | Max execution time (max: 300000) |
| `memoryLimitMb` | 128 | Memory limit (range: 64-1024) |
| `triggers` | `[{type: "http"}]` | Array of trigger configs. At most one per type. |
| `trigger` | — | **Legacy** single-trigger shorthand; normalized server-side to a 1-element `triggers` array. |
| `agent_tool` | `false` | Expose this function to agents as a tool. |
| `agent_tool_description` | — | Short description shown to the LLM (max 500 chars). |
| `agent_tool_mode` | `read_only` | `read_only` or `read_write`. `read_write` requires HITL approval. |
| `agent_tool_exposed_to` | `developer_only` | `developer_only` or `end_user`. |
| `allow_service_key_impersonation` | `true` | When `true`, this function accepts `X-Butterbase-As-User` from app-scoped service keys and the runtime populates `ctx.user.id` accordingly. Set to `false` on admin-only or billing-webhook handlers — the platform 403s any `X-Butterbase-As-User` header on them at the edge. See [Server-to-server function calls](/core-concepts/functions/#server-to-server-function-calls). |
### Trigger types
Each trigger object has a `type` and a type-specific `config`. At most one trigger of each type may be attached to a function (enforced by a unique index).
| Type | Config | Notes |
|------|--------|-------|
| `http` | `{ method?, path?, auth? }` | `auth` defaults to `required` — anonymous callers get 401 at the edge. Set `none` only for intentionally public endpoints. |
| `cron` | `{ schedule, timezone? }` | `schedule` is a cron expression (e.g. `*/5 * * * *`). `timezone` defaults to UTC. |
| `s3_upload` | `{ bucket, prefix?, contentTypes? }` | Fires when an object lands in the bucket matching `prefix` and (optionally) the listed MIME types. |
| `webhook` | `{ secret_required?, allowed_sources? }` | Generates a signed webhook URL. `allowed_sources` is a comma-separated list of provider tags. |
| `websocket` | `{}` | Invoked on each incoming WebSocket frame from the realtime channel. |
### Exposing a function as an agent tool
When `agent_tool: true`, this function becomes callable from any agent in the same app whose graph spec lists its name under `tools.functions[]`. See the [Agents API](/api-reference/agents-api/) for how agents reference function tools.
```json
{
"name": "lookup_account",
"code": "...",
"agent_tool": true,
"agent_tool_description": "Look up a customer by email. Returns id, plan, status.",
"agent_tool_mode": "read_only",
"agent_tool_exposed_to": "developer_only"
}
```
The 4 `agent_tool*` fields are returned on `GET /functions` and `GET /functions/{name}` so clients can render UI state.
## Update function settings
```json
PATCH /v1/{app_id}/functions/{name}/settings
Authorization: Bearer {token}
{
"allow_service_key_impersonation": false
}
```
Toggle per-function settings without redeploying code. Currently the only
supported field is `allow_service_key_impersonation` (the Phase 2
impersonation gate). On success, the runtime cache is invalidated so the new
value takes effect on the next invocation.
## Update environment variables
```json
PATCH /v1/{app_id}/functions/{name}/env
Authorization: Bearer {token}
{
"envVars": {
"API_KEY": "new-secret",
"NEW_VAR": "value",
"OLD_VAR": null
}
}
```
Values are **merged** with existing env vars (not replaced). Set a value to `null` to delete a key.
## Invocation logs
```
GET /v1/{app_id}/functions/{name}/logs?limit=50&since=2026-01-01T00:00:00Z&level=error
```
| Parameter | Description |
|-----------|-------------|
| `limit` | Number of log entries |
| `since` | ISO date filter |
| `level` | Filter by level (`error`, `all`) |
| `include_deleted` | `true` to read logs for a soft-deleted function (post-incident forensics). Default `false`. |
### Log entry fields
| Field | Description |
|-------|-------------|
| `method` | HTTP method |
| `path` | Request path |
| `status_code` | Response status |
| `duration_ms` | Execution time |
| `memory_mb` | Memory used |
| `error` | Error message (if any) |
| `consoleLogs` | Array of captured console output (`{ level, message, timestamp }`) |
## Function metrics
| Metric | Description |
|--------|-------------|
| `total_invocations` | Total invocation count |
| `error_count` | Number of errors |
| `error_rate` | Error percentage |
| `avg_duration_ms` | Average execution time |
| `last_invocation` | Timestamp of last call |
---
## API Reference / Integrations API
All integration endpoints require authentication. Admin endpoints (configure, disable, list config) require an API key (`Authorization: Bearer bb_sk_...`). End-user endpoints (connect, execute, connections) accept either a user JWT or an API key with a `userId` body field.
## Endpoints
| Method | Path | Auth | Description |
|--------|------|------|-------------|
| `GET` | `/v1/:appId/integrations/available` | API key | List curated toolkits or search catalog |
| `GET` | `/v1/:appId/integrations/config` | API key | List enabled integrations |
| `POST` | `/v1/:appId/integrations/configure` | API key | Enable a toolkit |
| `DELETE` | `/v1/:appId/integrations/configure/:toolkit` | API key | Disable a toolkit |
| `POST` | `/v1/:appId/integrations/connect` | JWT or API key + userId | Generate OAuth URL for end-user |
| `GET` | `/v1/:appId/integrations/callback` | Public | OAuth callback handler |
| `GET` | `/v1/:appId/integrations/connections` | JWT or API key | List connected accounts |
| `DELETE` | `/v1/:appId/integrations/connections/:id` | JWT or API key | Disconnect an account |
| `GET` | `/v1/:appId/integrations/tools` | JWT or API key | List available tools |
| `POST` | `/v1/:appId/integrations/execute` | JWT or API key + userId | Execute a tool |
## GET /v1/:appId/integrations/available
List the 10 curated toolkits, or search the full catalog with `?search=`.
```
GET /v1/app_abc/integrations/available?search=salesforce
```
Response:
```json
{
"integrations": [
{ "toolkit": "salesforce", "displayName": "Salesforce", "curated": false }
]
}
```
## POST /v1/:appId/integrations/configure
Enable a toolkit for the app.
```json
{
"toolkit": "gmail",
"displayName": "Gmail",
"scopes": []
}
```
| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `toolkit` | string | ✓ | Toolkit slug (e.g. `gmail`, `google-calendar`) |
| `displayName` | string | | Human-readable name shown in the dashboard |
| `scopes` | string[] | | OAuth scopes (defaults to platform-managed) |
## POST /v1/:appId/integrations/connect
Generate an OAuth URL for an end-user. Redirect the user to `authUrl`.
```json
{
"toolkit": "gmail",
"redirectUrl": "https://yourapp.com/settings",
"userId": "uuid"
}
```
`userId` is required when authenticating with an API key. Omit when using a user JWT.
Response:
```json
{
"authUrl": "https://accounts.google.com/...",
"connectionRequestId": "ca_xxx"
}
```
## POST /v1/:appId/integrations/execute
Execute a tool using the authenticated user's connected account.
```json
{
"toolName": "GMAIL_SEND_EMAIL",
"params": { "to": "x@y.com", "subject": "Hi", "body": "Hello" },
"userId": "uuid"
}
```
`userId` is required when using an API key. Omit when using a user JWT.
Response on success:
```json
{ "successful": true, "data": { ... } }
```
Response on failure (`422` soft failure, `502` network error):
```json
{
"error": {
"code": "INTEGRATIONS_EXECUTION_FAILED",
"message": "...",
"remediation": "Check the tool name and parameters. Ensure the user has a connected account."
}
}
```
## Error codes
| Code | HTTP | Meaning |
|------|------|---------|
| `INTEGRATIONS_NOT_CONFIGURED` | 400 | Integration service not configured on the platform |
| `INTEGRATIONS_TOOLKIT_NOT_ENABLED` | 400 | Toolkit not enabled for this app — call `/configure` first |
| `INTEGRATIONS_EXECUTION_FAILED` | 422/502 | Tool execution failed (422 = soft failure, 502 = network error) |
---
## API Reference / KV API
Butterbase KV is a per-app key-value store accessible over HTTP. Every operation targets a single app and is authenticated at the request level. All endpoints share a common base path and the same `{ error, message }` error shape.
## Base URL
```
https://api.butterbase.ai/v1/{app_id}/kv/...
```
Replace `{app_id}` with your app's ID (e.g. `app_abc123`). The `kv/` prefix is fixed; everything after it is either a user key or one of the reserved `_`-prefixed paths described below.
For auth details see [Authentication](/core-concepts/authentication).
---
## Authentication
Every request must carry an `Authorization: Bearer ` header, or it is treated as an anonymous request (no header). Three token shapes are accepted.
### Function key
```http
Authorization: Bearer
```
Used by server-side code running inside a Butterbase function handler. The function key is injected automatically by the runtime; you do not manage it directly. Function keys have full read/write access to all keys and can manage expose rules.
### End-user JWT
```http
Authorization: Bearer
```
A JWT issued by the app's auth providers (configured via `auth_config`). Sent from frontend code after a user signs in. Access is limited to keys covered by an active `expose()` rule; keys with no matching rule return `401` or `403`. The JWT must have exactly three `.`-separated segments (`header.payload.signature`).
### Platform JWT (owner / dashboard)
```http
Authorization: Bearer
```
A JWT issued by Butterbase for the platform account that owns the app. Used by the Butterbase dashboard and owner-level tooling. Grants the same permissions as a function key, including expose-rule management. Most application code should use a function key instead.
---
## Endpoints
### GET /v1/:app_id/kv/:key
Read the value stored at `key`. Keys may contain slashes (e.g. `session/abc-123`).
**Auth:** Any (function key, platform JWT, end-user JWT if key is covered by a `read`-permissive expose rule, or anonymous if the rule allows `public` reads).
**Query parameters**
| Parameter | Type | Description |
|-----------|------|-------------|
| `touch` | `boolean` | When `true`, refreshes the TTL on durable keys to their original value (sliding expiry). Default `false`. |
**Response `200`**
```json
{ "value": }
```
**Response `404`**
```json
{ "error": "not_found", "message": "not_found" }
```
**Example**
```bash
GET /v1/app_abc123/kv/session/user-42
Authorization: Bearer
```
```json
{ "value": { "userId": "user-42", "role": "admin" } }
```
---
### GET /v1/:app_id/kv/:key/ttl
Return the remaining TTL of `key` in seconds.
**Auth:** Same as GET `:key`.
**Response `200`**
```json
{ "ttl": 86312 }
```
`ttl` is `null` when the key has no expiry, or a positive integer in seconds when it does. Returns `404` if the key does not exist.
---
### GET /v1/:app_id/kv/:key/exists
Check whether `key` exists without fetching its value.
**Auth:** Same as GET `:key`.
**Response `200`**
```json
{ "exists": true }
```
Always `200`; `exists` is `true` or `false`.
---
### PUT /v1/:app_id/kv/:key
Create or overwrite `key`. The previous value, if any, is replaced atomically.
**Auth:** Function key, platform JWT, or end-user JWT if key is covered by a `write`-permissive expose rule.
**Request body**
| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `value` | any JSON | Yes | The value to store. Any JSON-serialisable type is accepted. |
| `ttl` | integer or `null` | No | Time-to-live in seconds. `null` removes the expiry. Omit to use the default (30 days). Must be a positive integer if provided. |
| `ephemeral` | boolean | No | When `true`, the key is stored in the ephemeral tier (shorter-lived, lower cost). Default `false` (durable). |
**Response `204`** — No body.
**Example**
```bash
PUT /v1/app_abc123/kv/session/user-42
Authorization: Bearer
Content-Type: application/json
{
"value": { "userId": "user-42", "role": "admin" },
"ttl": 3600
}
```
---
### DELETE /v1/:app_id/kv/:key
Delete `key`. If the key existed in both the durable and ephemeral tiers, both copies are removed.
**Auth:** Function key, platform JWT, or end-user JWT if key is covered by a `write`-permissive expose rule.
**Response `200`**
```json
{ "deleted": 1 }
```
`deleted` is the count of underlying store entries removed (`0` if the key did not exist, `1` or `2` if it existed in one or both tiers).
---
### POST /v1/:app_id/kv/:key/incr
Atomically increment a numeric counter stored at `key`. If the key does not exist it is initialised to `0` before incrementing.
**Auth:** Function key, platform JWT, or end-user JWT (write expose rule required).
**Request body**
| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `by` | integer | No | Amount to increment by. Default `1`. Must be a whole number. |
**Response `200`**
```json
{ "value": 42 }
```
`value` is the new integer value after the operation.
---
### POST /v1/:app_id/kv/:key/decr
Atomically decrement a numeric counter. Same rules as `incr` except the counter is reduced.
**Auth:** Function key, platform JWT, or end-user JWT (write expose rule required).
**Request body**
| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `by` | integer | No | Amount to decrement by. Default `1`. Must be a whole number. |
**Response `200`**
```json
{ "value": 7 }
```
---
### POST /v1/:app_id/kv/:key/setnx
Set `key` only if it does **not** already exist ("set if not exists").
**Auth:** Function key, platform JWT, or end-user JWT (write expose rule required).
**Request body**
| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `value` | any JSON | Yes | The value to store if the key is absent. |
| `ttl` | integer or `null` | No | TTL in seconds. Same rules as PUT. |
| `ephemeral` | boolean | No | Store in the ephemeral tier. Default `false`. |
**Response**
| Code | Body | Meaning |
|------|------|---------|
| `201` | `{ "wrote": true }` | Key was absent; value was written. |
| `200` | `{ "wrote": false }` | Key already existed; no change made. |
---
### POST /v1/:app_id/kv/:key/cas
Compare-and-swap: atomically replace the value of `key` only when the current value equals `expected`.
**Auth:** Function key, platform JWT, or end-user JWT (write expose rule required).
**Request body**
| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `expected` | any JSON or `null` | Yes | The value the key must currently hold. Pass `null` to match an absent key. |
| `next` | any JSON | Yes | The new value to write on a match. |
**Response `200`**
```json
{ "swapped": true }
```
`swapped` is `true` if the swap succeeded, `false` if the current value did not match `expected`.
**Note:** A value that is itself the JSON string `"__NULL__"` cannot be distinguished from the absent-key sentinel in the CAS comparison. To use literal key names ending in an action word (e.g. `session/cas`), URL-encode the separator (`session%2Fcas`).
---
### POST /v1/:app_id/kv/:key/expire
Update (or remove) the TTL on an existing key without changing its value.
**Auth:** Function key, platform JWT, or end-user JWT (write expose rule required).
**Request body**
| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `ttl` | integer or `null` | Yes | New TTL in seconds (non-negative integer), or `null` to persist the key indefinitely. |
**Response `200`**
```json
{ "applied": true }
```
`applied` is `true` when the key existed and the TTL was updated, `false` when the key did not exist.
---
### POST /v1/:app_id/kv/_batch
Execute up to 100 `get`, `set`, or `del` operations in a single round-trip.
**Auth:** Any (function key, platform JWT, or end-user JWT). Per-operation access checks against expose rules apply for JWT/anonymous callers.
**Request body**
```json
{
"ops": [
{ "op": "get", "key": "counter/daily" },
{ "op": "set", "key": "counter/daily", "value": 0 },
{ "op": "del", "key": "temp/scratch" }
]
}
```
| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `ops` | array | Yes | Array of operation objects. Maximum 100 items. |
| `ops[].op` | `"get"` \| `"set"` \| `"del"` | Yes | The operation type. |
| `ops[].key` | string | Yes | The key to operate on. |
| `ops[].value` | any JSON | Required for `set` | The value to write. |
**Response `200`**
```json
{
"results": [
{ "value": 17 },
{ "ok": true },
{ "deleted": 1 }
]
}
```
Results are returned in the same order as the input `ops`. Failing items carry an `error` field rather than causing the entire batch to fail:
| Result shape | Meaning |
|---|---|
| `{ "value": }` | `get` succeeded (`value` is `null` if the key was absent) |
| `{ "ok": true }` | `set` succeeded |
| `{ "deleted": N }` | `del` completed (`N` is `0` or `1`) |
| `{ "error": "key_invalid" }` | Key failed validation |
| `{ "error": "KV_VALUE_TOO_LARGE" }` | Value exceeds 256 KB |
| `{ "error": "KV_FORBIDDEN" }` | Expose rule denied access for this key |
| `{ "error": "invalid op" }` | `op` is not `get`, `set`, or `del` |
| `{ "error": "missing value" }` | `set` operation missing `value` field |
| `{ "error": "redis_error", "message": "..." }` | Transient storage error |
---
### GET /v1/:app_id/kv/_scan
Scan all keys belonging to the app, with optional prefix filtering. Intended for tooling and administrative scripts.
**Auth:** Function key or platform JWT only. End-user JWTs and anonymous requests receive `403`.
**Query parameters**
| Parameter | Type | Description |
|-----------|------|-------------|
| `prefix` | string | Only return keys that begin with this string. |
| `limit` | integer | Maximum number of keys to return per page. |
| `cursor` | string | Opaque cursor returned by a previous scan; pass to fetch the next page. |
**Response `200`**
```json
{
"keys": ["counter/daily", "session/user-1", "session/user-2"],
"cursor": "eyJwYWdlIjoxfQ"
}
```
`cursor` is `null` (or absent) when there are no more pages.
---
### GET /v1/:app_id/kv/_stats
Return storage statistics for the app.
**Auth:** Function key or platform JWT only. End-user JWTs and anonymous requests receive `403`.
**Response `200`**
```json
{
"keys_total": 4821,
"bytes_used": 1048576,
"ops_per_sec": null,
"limit": {
"max_ops_per_sec": 50,
"max_storage_bytes": 10485760,
"max_keys_total": 100000,
"max_value_bytes": 262144
}
}
```
`ops_per_sec` reflects live traffic and may be `null` when no recent ops are recorded. The `limit` block shows the caps in effect for the app's current plan tier.
---
### POST /v1/:app_id/kv/_flush
Delete all keys belonging to the app. Irreversible.
**Auth:** Function key or platform JWT only. End-user JWTs and anonymous requests receive `403`.
**Request body**
| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `confirm` | `true` | Yes | Must be the boolean `true`. Omitting this field or passing any other value returns a `400 confirm_required` error. |
| `include_config` | boolean | No | When `true`, expose rules and other per-app KV configuration are also deleted. Default `false`. |
**Response `200`**
```json
{ "deleted": 4821 }
```
`deleted` is the total number of keys removed.
---
### GET /v1/:app_id/kv/_expose
List all expose rules defined for the app. Expose rules control which keys, and at what permission level, end-user JWTs and anonymous callers can access.
**Auth:** Function key or platform JWT only.
**Response `200`**
```json
{
"rules": [
{ "pattern": "session/{user.id}/*", "read": "owner", "write": "owner", "order": 0 },
{ "pattern": "public/*", "read": "public", "write": "deny", "order": 1 }
]
}
```
| Field | Type | Description |
|-------|------|-------------|
| `pattern` | string | Glob-style key pattern. `{user.id}` and `{user.role}` are substituted from the caller's JWT claims for `owner` checks. |
| `read` | `"public"` \| `"authed"` \| `"owner"` \| `"deny"` | Required level for read operations. |
| `write` | `"public"` \| `"authed"` \| `"owner"` \| `"deny"` | Required level for write operations. |
| `order` | integer | Declaration order; lower numbers take priority on conflict. |
Role meanings:
| Role | Meaning |
|------|---------|
| `public` | Any caller, including anonymous requests. |
| `authed` | Any caller with a valid end-user JWT. |
| `owner` | The authenticated user whose `user.id` (or `user.role`) matches the pattern substitution. |
| `deny` | Always denied for the matched access type. |
---
### PUT /v1/:app_id/kv/_expose/:pattern
Create or update an expose rule. The `:pattern` segment must be URL-encoded (e.g. `session%2F%7Buser.id%7D%2F*`).
**Auth:** Function key or platform JWT only.
**Request body**
| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `read` | `"public"` \| `"authed"` \| `"owner"` \| `"deny"` | Yes | Read permission for this pattern. |
| `write` | `"public"` \| `"authed"` \| `"owner"` \| `"deny"` | Yes | Write permission for this pattern. |
**Response `204`** — Rule saved. No body.
**Response `409`**
```json
{
"error": "KV_EXPOSE_CONFLICT",
"message": "pattern conflicts with existing rule",
"existing": { "pattern": "session/*", "read": "authed", "write": "deny" }
}
```
Returned when the new pattern would be ambiguous with an existing rule (same key space, overlapping permission).
**Example**
```bash
PUT /v1/app_abc123/kv/_expose/session%2F%7Buser.id%7D%2F*
Authorization: Bearer
Content-Type: application/json
{ "read": "owner", "write": "owner" }
```
---
### DELETE /v1/:app_id/kv/_expose/:pattern
Remove an expose rule. The `:pattern` segment must be URL-encoded.
**Auth:** Function key or platform JWT only.
**Response `200`**
```json
{ "deleted": 1 }
```
`deleted` is `1` if the rule existed and was removed, `0` if no matching rule was found.
---
### GET /v1/:app_id/kv/_audit_recent
Return recent KV error events for the app (HTTP 4xx/5xx responses). Useful for debugging access-denied patterns and identifying misconfigured expose rules.
**Auth:** Any authenticated caller (function key, platform JWT, or end-user JWT). Anonymous callers receive `401`.
**Query parameters**
| Parameter | Type | Description |
|-----------|------|-------------|
| `limit` | integer | Number of entries to return. Default `50`, maximum `200`. |
**Response `200`**
```json
{
"entries": [
{
"at": "2026-05-24T10:31:02.000Z",
"method": "PUT",
"path": "/v1/app_abc123/kv/session/user-42",
"status_code": 403,
"error_code": "forbidden",
"key": "session/user-42"
}
]
}
```
| Field | Type | Description |
|-------|------|-------------|
| `at` | ISO 8601 string | When the request occurred. |
| `method` | string | HTTP method. |
| `path` | string | Full request path. |
| `status_code` | integer | HTTP status returned. |
| `error_code` | string or `null` | The `error` field from the response body, if any. |
| `key` | string or `null` | The user key involved, extracted from the path (absent for `_`-prefixed admin paths). |
---
## Limits
These are the default limits applied to every new app. Higher caps are available on paid plans.
| Limit | Default |
|-------|---------|
| Max operations per second | 50 ops/sec |
| Max total storage | 10 MB per app |
| Max total keys | 100,000 keys |
| Max value size | 256 KB per key |
| Max batch size | 100 ops per `_batch` request |
| Default TTL (no `ttl` supplied on PUT) | 30 days |
When a limit is exceeded the response carries the corresponding error code (see [Error codes](#error-codes) below).
---
## Error codes
All error responses use the shape `{ "error": "
", "message": "" }`.

| Code | HTTP status | Meaning | How to handle |
|------|-------------|---------|---------------|
| `auth_failed` | 401 / 403 / 404 | Authentication could not be completed. Emitted as a wrapper; the `error` field in the body will be one of the more specific codes below. | Check the specific nested error code. |
| `bad_request` | 400 | A required field is missing or has an invalid type (e.g. `ttl` is not a positive integer, `by` is not a whole number, `read`/`write` role is unrecognised, `ops` is not an array, batch exceeds 100 items). | Fix the request body or query parameters. |
| `confirm_required` | 400 | `POST _flush` was called without `{ "confirm": true }`. | Add `"confirm": true` to the request body. |
| `forbidden` | 403 | The caller is authenticated but does not have permission for this operation — either no expose rule matches, the matching rule's role is `deny`, or the operation requires a function/platform key (e.g. `_scan`, `_stats`, `_flush`, `_expose` writes). | Check expose rules (`GET _expose`). Upgrade to a function key for admin operations. |
| `invalid_key` | 400 | The key portion of the URL is empty (no key segment provided). | Provide a non-empty key after `/kv/`. |
| `invalid_jwt` | 401 | The `Authorization` header contains a three-segment token that failed signature verification. | Re-issue a fresh user session token. |
| `key_invalid` | 400 | The key string contains characters or patterns not permitted by the key format rules. | Use printable ASCII; avoid control characters and reserved prefixes. |
| `KV_EXPOSE_CONFLICT` | 409 | `PUT _expose/:pattern` was rejected because the new pattern overlaps ambiguously with an existing rule. The response body includes an `existing` field showing the conflicting rule. | Update the conflicting rule first, or choose a non-overlapping pattern. |
| `KV_FORBIDDEN` | — (batch item error) | A single operation inside a `_batch` request was denied by an expose rule. The batch itself still returns `200`; this code appears only inside `results[].error`. | Check expose rules for the affected key. |
| `KV_VALUE_TOO_LARGE` | 413 (or batch item error) | The serialised value exceeds the 256 KB per-key limit. | Reduce the value size, or split data across multiple keys. |
| `no_kv_credential` | 404 | KV is not provisioned for this app, or the app does not exist. | Ensure the app is initialised and KV is enabled. |
| `not_found` | 404 | The requested key does not exist. | Check for typos in the key name or verify the key was written first. |
| `redis_error` | — (batch item error) | A transient storage error occurred during a batch operation. The item failed but other items in the batch may have succeeded. | Retry the failed operation individually. |
| `unauthorized` | 401 | The request requires authentication (an expose rule requires at least `authed` or `owner`), but no valid credential was supplied. | Sign the user in and attach the resulting JWT. |

---

## API Reference / MCP Tools

These tools are available when connected via MCP. See [MCP Setup](/getting-started/mcp-setup) for connection instructions.

## App Management

| Tool | Description |
|------|-------------|
| `init_app` | Create a new app. Accepts an optional `region` slug. Returns app_id and API base URL. |
| `list_regions` | List the regions an app can be created or moved to. |
| `manage_app` | Comprehensive app management: list/delete/pause, configure access/visibility, move between regions, clone templates, set webhooks. See `manage_app` actions below. |

### manage_app actions

| Action | Description |
|--------|-------------|
| `list` | List all apps with metadata. |
| `delete` | Permanently delete an app. Irreversible. |
| `pause` | Kill-switch — pause/resume all data-plane traffic. Returns 503 (`APP_PAUSED`) on data-plane endpoints while paused. |
| `get_config` | Read app configuration (CORS, JWT, storage limits). |
| `update_cors` | Set allowed CORS origins. |
| `update_access_mode` | Toggle anonymous vs authenticated-only access. |
| `set_visibility` | Mark an app public or private, optionally setting the templates-browser `listed` flag. |
| `move` | Move an existing app to another region. Pass `dest_region`. Returns a `migration_id`; the app stays available for reads during the move. |
| `move_status` | Check the progress of a move in flight. Pass `migration_id` (returned by `action: "move"`). |
| `teardown_source_replica` | After a completed move, decommission the retained source-region replica. Pass `migration_id`. |
| `find_templates` | Search public, listed app templates. Pass optional `q` (name prefix), `region`, `sort` (`recent` or `popular`), `limit` (max 50), `offset`. Returns `{ items: [...], total, limit, offset }`. |
| `clone` | Clone a public app's repo snapshot into a new app you own. Pass `source_app_id` and optionally `name` and `region`. Returns `{ job_id, status: "pending" }`. |
| `get_clone_job` | Poll the status of a clone job by `job_id`. Returns `status` (`pending`, `completed`, or `failed`), `dest_app_id` when completed, and `error_message` when failed. |
| `set_clone_webhook` | Configure a webhook that fires when someone clones this app. Pass `webhook_url` and `webhook_secret`, or `clear_webhook: true` to remove. |
| `get_env` | Read the app-level environment variable **key names** (values are never returned). Returns `{ keys: string[], updated_at }`. See [Environment variables](/core-concepts/functions/#environment-variables). |
| `update_env` | Merge app-level env vars in one call. Pass `env: { KEY: "value" }` to set/upsert, or `env: { KEY: null }` to delete. Values live for every function in the app via `ctx.env.`. Response reports `updated_keys` plus the list of functions whose cache was invalidated. Keys matching `/^BUTTERBASE_/i` are rejected as reserved. |

## Schema & Migrations

| Tool | Description |
|------|-------------|
| `get_schema` | Read current database schema. |
| `apply_schema` | Apply declarative schema. Set `dry_run: true` to preview. |
| `dry_run_schema` | Preview SQL without executing. |
| `list_migrations` | View migration history. |

## Data Operations

| Tool | Description |
|------|-------------|
| `select_rows` | Query rows with filtering, sorting, pagination. |
| `insert_row` | Insert a row into a table. |
| `seed_database` | Bulk-insert up to 100 rows in one call. Bypasses RLS (uses platform role). |

## Authentication & Security

| Tool | Description |
|------|-------------|
| `configure_oauth_provider` | Register a social sign-in provider. |
| `get_oauth_config` | List configured OAuth providers. |
| `update_oauth_provider` | Modify an OAuth provider. |
| `delete_oauth_provider` | Remove an OAuth provider. |
| `enable_rls` | Enable row-level security on a table. |
| `create_policy` | Create a custom RLS policy. |
| `create_user_isolation_policy` | Quick user isolation setup. |
| `get_rls_policies` | List active RLS policies. |
| `delete_rls_policy` | Remove RLS from a table. |
| `query_audit_logs` | Search auth audit logs. |
| `update_app_access_mode` | Toggle an app's data-API access between `public` and `authenticated`. |
| `set_visibility` | Mark an app public or private as a template, optionally setting the templates browser `listed` flag. |
| `secure_app` | Set `access_mode = "authenticated"` and create user-isolation RLS policies on listed tables in one call. |
| `configure_auth_hook` | Configure (or remove) the function invoked after every successful auth event. |

## App Repo

| Tool | Description |
|------|-------------|
| `manage_repo` | Push, pull, inspect, or wipe your app's repo (content-addressed code snapshots). MCP pushes are capped at ~1 MB; for larger snapshots shell out to `butterbase repo push`. |

## Storage

| Tool | Description |
|------|-------------|
| `generate_upload_url` | Get a presigned upload URL. |
| `generate_download_url` | Get a presigned download URL. |
| `get_storage_objects` | List all files. |
| `delete_storage_object` | Delete a file. |
| `update_storage_config` | Toggle app-wide public read access for storage objects. |

## Serverless Functions

| Tool | Description |
|------|-------------|
| `deploy_function` | Deploy a TypeScript/JavaScript function. |
| `list_functions` | List deployed functions. |
| `invoke_function` | Test-invoke a function. |
| `delete_function` | Delete a function. |
| `update_function_env` | Update **function-level** environment variables (overrides app-level values on collision). For env vars shared across every function in the app, use `manage_app.update_env` instead. See [Environment variables](/core-concepts/functions/#environment-variables). |
| `get_function_logs` | View invocation logs. |

## Frontend Deployment

| Tool | Description |
|------|-------------|
| `create_frontend_deployment` | Create deployment and get upload URL. |
| `start_frontend_deployment` | Start deployment after upload. |
| `list_frontend_deployments` | View deployment history. |
| `set_frontend_env` | Configure build environment variables. |

## Realtime

| Tool | Description |
|------|-------------|
| `configure_realtime` | Enable realtime on tables. |
| `get_realtime_config` | View realtime configuration. |

## AI Gateway

All AI actions are routed through the single `manage_ai` MCP tool. Pass `{ app_id, action, ... }` where `action` selects the operation.

| Action | Description |
|--------|-------------|
| `chat` | Synchronous chat completion (OpenAI-compatible). Pass `messages`, optional `model`, `temperature`, `max_tokens`. |
| `embed` | Generate vector embeddings. Pass `input` (string or array), optional `model`, `encoding_format`. |
| `list_models` | List models available through the app's gateway (chat, embedding, and video). |
| `get_config` | Read the app's AI configuration (default model, allowed models, max tokens). |
| `update_config` | Update AI configuration. Can rotate BYOK keys, set default model, set allowed models. |
| `get_usage` | Aggregate token counts and credit spend over a date window. |
| `submit_video` | Submit an async video generation job. Pass `model`, `prompt`, optional `duration`, `resolution`, `aspect_ratio`, `generate_audio`, `seed`. Returns `{ job_id, status, polling_url }`. |
| `poll_video` | Poll a video job's status. Pass `job_id`. Returns the current job state including `content_urls` (absolute) and `charged_credits_usd` when `status === 'completed'`. |
| `configure_meetings_webhook` | Configure where Butterbase forwards meeting-bot events for this app. Pass `forward_url` and optionally `rotate_secret: true` to mint a fresh signing-secret identifier (returned **once**). The stored hash is used in the `x-bb-key-id` header so your handler can detect post-rotation staleness. |
| `usage_meetings` | List recent meeting-bot usage rows for this app — `actor_id`, dimension (`recording` or `transcription`), `seconds`, `usd_charged`, `created_at`. Last 100 rows ordered by time desc. |

For the full HTTP request/response shapes and end-to-end video example, see the [AI API reference](./ai-api.md).

## RAG (Retrieval-Augmented Generation)

| Tool | Description |
|------|-------------|
| `rag_create_collection` | Create a named collection for storing and querying documents. |
| `rag_list_collections` | List all RAG collections with document counts. |
| `rag_delete_collection` | Delete a collection and all its documents, chunks, and embeddings. |
| `rag_ingest` | Ingest raw text or an uploaded file into a collection. Returns a document ID; processing is async. |
| `rag_ingest_status` | Poll ingestion status (`pending` → `processing` → `ready` / `failed`). |
| `rag_query` | Semantic search over a collection. Returns ranked chunks; optionally synthesizes an AI answer. |
| `rag_list_documents` | List all documents in a collection with status and metadata. |
| `rag_delete_document` | Delete a document and all its vector chunks. |

## Integrations

| Tool | Description |
|------|-------------|
| `configure_integration` | Enable a toolkit (Gmail, Slack, etc.) for an app. |
| `list_available_integrations` | List curated toolkits or search the full catalog. |
| `list_integration_tools` | List executable tools for a connected toolkit. |
| `execute_integration_action` | Execute a tool on behalf of a user. |
| `list_connected_accounts` | List all users with connected accounts for an app. |

## People (people / company search + enrichment)

| Tool | Description |
|------|-------------|
| `manage_people` | Search for people and companies using structured filters or natural-language queries, enrich profiles by LinkedIn URL (with 30-day cache), and queue async work-email lookups. All metered against the user's Butterbase credits at platform pricing. See [People API](./people-api.md) for HTTP shapes, response payloads, and pricing details. |

Each action is routed to one of two configurable backends (`primary` or `secondary`); routing is operator-controlled at deploy time and not visible to MCP callers.

### manage_people actions

All actions take `{ app_id, action, ... }` where `action` selects the operation.

| Action | Description |
|--------|-------------|
| `search_person` | Search for people using structured filters, a free-form `query`, or both. When `query` is set it takes priority; otherwise structured filters are used. Structured filters: `current_role_title`, `past_role_title`, `current_company_name`, `current_company_industry`, `country`, `region`, `city`, `education_school_name`, `education_degree_name`, `education_field_of_study`, plus `page_size`, `next_token`. Boolean operators in structured fields are honored as ranking hints. Empty searches are free. |
| `search_company` | Search for companies using structured filters, a free-form `query`, or both. Filters: `industry`, `country`, `employee_count_max`, plus `page_size`, `next_token`. |
| `get_profile` | Fetch a full profile by LinkedIn URL with cache. Pass `linkedin_profile_url`. Optional `live_fetch: "force"` skips cache. 2 credits on a cache miss, 0 on a hit (cache TTL: 30d for hits, 7d for not-found, 1h for failed). |
| `queue_email_lookup` | Queue an async work-email lookup. Pass `linkedin_profile_url`. Returns `lookup_id` and `status: "pending"`. Poll with `get_email_lookup`. Charged ~3 credits at queue time and 1 more when the webhook resolves. |
| `get_email_lookup` | Poll an email lookup by `id`. Returns `{ status, email, credits_consumed }`. |

### Search examples

```jsonc
// Semantic query — natural-language description of the ideal match
{
  "action": "search_person",
  "query": "founder of a YC-backed AI startup based in San Francisco",
  "page_size": 25
}

// Structured filters — boolean syntax honored as ranking hints
{
  "action": "search_person",
  "current_role_title": "(VP OR \"Vice President\") AND NOT assistant",
  "education_school_name": "(Harvard OR Stanford OR MIT OR Princeton OR Yale)",
  "country": "US",
  "page_size": 25
}

// Company search
{
  "action": "search_company",
  "industry": "Financial Services",
  "employee_count_max": 200,
  "country": "US"
}

// Profile lookup — cache absorbs duplicates within 30 days
{ "action": "get_profile", "linkedin_profile_url": "https://www.linkedin.com/in/jane-doe-abc123" }
```

### Pricing summary

Costs vary by which provider the operator routes the action to. Numbers below are typical defaults; actual cost is always reported in the `x-people-*` response headers and the `usage` body. See [People API](./people-api.md#pricing) for the full table.

| Action | Typical credits | Typical USD |
|---|---|---|
| `search_person` / `search_company` (up to 10 results) | 7 | $0.0084 |
| `get_profile` cache miss | 2 | $0.040 |
| `get_profile` cache hit | 0 | $0 |
| `queue_email_lookup` queue accept | 3 | $0.060 |
| Webhook email resolution | 1 | $0.020 |
| Empty search (0 results) | 0 | $0 |

### Errors

`manage_people` returns `isError: true` with the underlying control-api error text. Common conditions:

- `insufficient_credits` (402) — user's Butterbase balance is below the minimum gate ($0.05 default). No provider call is made.
- `forbidden` (403) — authed user doesn't own the app.
- `people_disabled` (503) — feature flag is off on this deployment.
- `people_unavailable` (503) — feature not enabled or required platform configuration missing on this deployment.
- `provider_not_registered` (503) — operator misconfiguration; no provider configured for the slot this action routed to.
- `provider_action_unsupported` (503) — operator misconfiguration; the configured provider for this slot doesn't support this action.

### Conceptual notes

- **Caching saves real money.** Repeated `get_profile` calls against the same normalized LinkedIn URL within 30 days cost $0. Treat the cache as durable and feel free to re-fetch on render.
- **Searches return 0 credits when there are 0 results** — use a `page_size: 1` probe to preview cost (look at `data.totalResultCount`) before paginating.
- **Async email is genuinely async.** The queue call returns immediately; the email lands minutes later via webhook. Plan your UI for a `pending` state.
- **Phone numbers are not supported** at this tier.

## KV Store

| Tool | Description |
|------|-------------|
| `manage_kv` | Manage app KV store: config rules (expose/unexpose namespaces) and data-plane operations (get/set/del/incr/etc). |

### manage_kv actions

| Action | Description |
|--------|-------------|
| `list_rules` | List all KV namespace exposure rules for the app |
| `expose` | Expose a key pattern with read/write role access control |
| `unexpose` | Remove an exposure rule by pattern |
| `stats` | Get KV usage stats (key count, memory, etc.) |
| `scan` | Scan keys by prefix (cursor-based pagination) |
| `flush` | Delete all keys in the KV store (requires confirm: true) |
| `get` | Get the value of a key |
| `set` | Set a key to a value with optional TTL or ephemeral flag |
| `del` | Delete one key |
| `incr` | Increment a key's integer value |
| `decr` | Decrement a key's integer value |
| `setnx` | Set a key only if it does not already exist |
| `setex` | Set a key with an explicit TTL in seconds |
| `cas` | Compare-and-swap: atomically set next only if current value matches expected |
| `exists` | Check if a key exists |
| `ttl` | Get remaining TTL of a key in seconds |
| `expire` | Set a TTL on an existing key |
| `mget` | Get values of multiple keys at once |
| `mset` | Set multiple key-value pairs at once |

### manage_kv example

```json
{
  "action": "manage_kv",
  "app_id": "app_abc123",
  "action": "set",
  "key": "counter:requests",
  "value": 42,
  "ttl": 3600
}
```

## Substrate

All substrate operations are routed through the single `manage_substrate` MCP tool. Pass `{ action, ... }` where `action` selects the operation. The agent's calling user is implicit — there is no `app_id` and no `substrate_user_id`; every call operates on the substrate that belongs to the caller.

| Tool | Description |
|------|-------------|
| `manage_substrate` | Read/write the caller's substrate: propose/approve/reject actions, browse the ledger, look up entities and source artifacts, search memory, manage outbox and attention rules, read snapshots, toggle yolo. See `manage_substrate` actions below. |

### manage_substrate actions

Writes — every substrate write (decisions, commitments, learnings, entities, source artifacts, side-effects) goes through `propose` with the appropriate `capability`.

| Action | Description |
|--------|-------------|
| `propose` | Propose an action. Pass `capability`, `payload`, optional `idempotency_key`, optional `dangerously_skip_approval`. Returns `{ action_id, verdict, requires_approval, result? }`. |
| `approve` | Approve a pending action. Pass `action_id`. |
| `reject` | Reject a pending action. Pass `action_id`, optional `reason`. |

Action ledger.

| Action | Description |
|--------|-------------|
| `list_actions` | List ledger rows. Optional `status` (`proposed` \| `executed` \| `rejected`), `capability`, `source_app_id`, `source_rule_id`, `limit` (1–500, default 100), `before` (ISO timestamp). |
| `get_action` | Fetch one action by `action_id`. |

Entities.

| Action | Description |
|--------|-------------|
| `find_entities` | List/search entities. Optional `type` (`person` \| `company` \| `fund` \| `workspace` \| `team` \| `project` \| `event` \| `agent` \| `self`), `q` (display-name search), `limit` (1–200, default 50). |
| `get_entity` | Fetch one entity by `entity_id`. |

Source artifacts — durable source material (meeting transcripts, email threads, call recordings, documents) that decisions, commitments, and learnings can link back to.

| Action | Description |
|--------|-------------|
| `list_source_artifacts` | List/search artifacts. Optional `kind`, `q` (FTS over title+summary+content), `limit`, `count` (`true` to include `total`). |
| `get_source_artifact` | Fetch one artifact by `artifact_id`, including its full `content`. |

Memory.

| Action | Description |
|--------|-------------|
| `search_memory` | Full-text search across long-form memory. Pass `q`; optional `kinds` (any subset of `decisions`, `commitments`, `learnings`, `source_artifacts` — defaults to all of them), `limit`. |

Outbox.

| Action | Description |
|--------|-------------|
| `list_outbox` | List outbox deliveries. Optional `status`, `limit`. |
| `retry_outbox` | Retry a failed delivery by `outbox_id`. |
| `cancel_outbox` | Cancel a pending delivery by `outbox_id`. |

Attention rules.

| Action | Description |
|--------|-------------|
| `list_rules` | List rules. Optional `enabled` filter. |
| `get_rule` | Fetch one rule by `rule_id`. |
| `create_rule` | Create a rule. Pass `rule` (see [Substrate API](./substrate-api.md#attention-rules) for the body shape). |
| `update_rule` | Update a rule. Pass `rule_id` and `rule`. |
| `delete_rule` | Delete a rule by `rule_id`. |
| `enable_rule` | Enable a rule by `rule_id`. |
| `disable_rule` | Disable a rule by `rule_id`. |
| `list_rule_firings` | List firings for a rule. Pass `rule_id`; optional `status`, `limit`, `before`. |

Snapshots & settings.

| Action | Description |
|--------|-------------|
| `snapshots` | List daily substrate snapshots. Optional `days` (default 7). |
| `get_settings` | Read per-user toggles (yolo mode, etc.). |
| `set_yolo` | Toggle yolo mode. Pass `yolo_mode: true \| false`. |

### manage_substrate example

```json
{
  "tool": "manage_substrate",
  "action": "propose",
  "capability": "upsert_source_artifact",
  "payload": {
    "kind": "meeting_transcript",
    "title": "Weekly product sync — 2026-06-09",
    "external_system": "fireflies",
    "external_id": "abc123",
    "content": "Alice: we should ship phase 6 by Friday…"
  }
}
```

## Custom Domains

| Tool | Description |
|------|-------------|
| `configure_custom_domain` | Add, list, check status, verify, or remove custom domains. Actions: `add`, `list`, `status`, `verify`, `remove`. |

## Hackathon

These tools are listed whenever any hackathon's submission window is open. Multiple hackathons can be open simultaneously; tools that target one require an explicit `hackathon_slug`. See [Hackathon](/hackathon).

| Tool | Description |
|------|-------------|
| `prep_and_submit_hackathon_entry` | Two-step flow. `action: "prep"` resolves the hackathon from your `submission_code` and returns its `field_schema` plus a `next_call` template — a fully-formed example `submit` invocation with a placeholder per field. `action: "submit"` sends the confirmed `data` (use `matched.slug` from prep as `hackathon_slug`). First submission also needs `submission_code`. Pass `app_id` (from `manage_app` `list`) so automated scoring can award feature points and judges can verify your app. |

## Feedback & Documentation

| Tool | Description |
|------|-------------|
| `submit_suggestion` | Submit feedback, bug reports, or feature requests. |
| `butterbase_docs` | Read documentation by topic. |

---

## API Reference / People API

Endpoints for finding people and companies, fetching enriched profiles, and queuing async work-email lookups via Butterbase's built-in people search. Useful for lead finders, CRM enrichment, and people-search features.

All endpoints are app-scoped — the `app_id` lives in the URL path and the call is authenticated with a Butterbase service-key (`bb_sk_...`) or JWT belonging to that app's owner.

Every call is metered against the user's Butterbase credit balance at platform pricing. Cache hits are free.

## Endpoints

| Method | Path | Purpose |
|---|---|---|
| POST | /v1/\{app_id\}/people/search/person | Structured + semantic search for people |
| POST | /v1/\{app_id\}/people/search/company | Structured + semantic search for companies |
| POST | /v1/\{app_id\}/people/profile | Enrich a profile by LinkedIn URL (30-day cache) |
| POST | /v1/\{app_id\}/people/profile/email | Queue an async work-email lookup |
| GET | /v1/\{app_id\}/people/email-lookup/\{lookup_id\} | Poll a pending email lookup |

## Response headers

Every people response (success and error) carries these headers so callers can track cost without parsing the body:

| Header | Notes |
|---|---|
| `x-people-provider` | Which provider slot served the call (`primary` or `secondary`) |
| `x-people-credits-consumed` | Integer |
| `x-people-usd-charged` | What was deducted from the user |
| `x-people-cached` | Profile route only |

Headers are present on every reply path — success, cache hit, balance-gate rejection (402), and error (503/4xx). For error or balance-rejection paths, numeric headers are `0` or `0.000000`. The `x-people-cached` header appears only on the `/profile` route.

## Pricing

Costs vary by which provider the operator routes the action to. Numbers below are typical defaults for the standard platform configuration; actual cost per call is always reported in the `x-people-*` response headers and the `usage` body.

| Action | Typical credits | Typical USD | Notes |
|---|---|---|---|
| `search/person` (up to 10 results) | 7 | $0.0084 | Scales with result count; ~$0.0012 per additional result above 10 |
| `search/company` (up to 10 results) | 7 | $0.0084 | Same scaling |
| `profile` (cache miss) | 2 | $0.040 | Variable; depends on configured profile provider |
| `profile` (cache hit, within 30 days) | 0 | $0 | Always free |
| `profile/email` (queue) | 3 | $0.060 | Charged at queue time |
| Email lookup resolved (provider webhook) | 1 | $0.020 | Charged when the async result arrives |
| Empty result set | 0 | $0 | Never billed |

Costs vary by deployment — each platform operator configures pricing and routing independently. The actual credit count and USD cost for any individual call is always reported in the `x-people-*` response headers and the `usage` field of the body, so client code never needs to guess. Treat the numbers in the table above as typical defaults, not contractual values.

## Authentication

```
Authorization: Bearer {service-key or JWT}
```

The call's user must own the app referenced by `{app_id}` — Butterbase enforces this via an ownership check on every route. Non-owners get `403 Forbidden`.

## Search people

```
POST /v1/{app_id}/people/search/person
Authorization: Bearer {token}
Content-Type: application/json

{
  "query": "founder of a YC-backed AI startup based in San Francisco",
  "country": "US",
  "pageSize": 25
}
```

Both structured filters and the optional `query` field are accepted. When `query` is set it takes priority; when omitted, the structured fields are stitched into a natural-language description automatically and sent to the configured search backend.

The platform's search backend interprets all queries semantically. Boolean operators (`AND`, `OR`, `NOT`, parentheses, double-quoted phrases) may be included in structured fields and are honored where the configured provider supports them; for semantic providers they are treated as ranking hints rather than strict filters. Behavior may vary by deployment.

| Field | Type | Notes |
|---|---|---|
| `query` | string | Optional. Free-form natural-language description of the ideal match. Takes priority over structured filters when set. |
| `currentRoleTitle` | string | Current job title. Boolean syntax honored as a ranking hint. |
| `pastRoleTitle` | string | Any past role. |
| `currentCompanyName` | string | |
| `currentCompanyIndustry` | string | |
| `country` | string | E.g. `US`, `GB`. |
| `region` | string | State/region. |
| `city` | string | |
| `educationSchoolName` | string | E.g. `(Harvard OR Stanford)`. |
| `educationDegreeName` | string | E.g. `MBA`, `PhD`, `MD`. |
| `educationFieldOfStudy` | string | E.g. `"Computer Science"`. |
| `pageSize` | number | 1–100. |
| `nextToken` | string | Pagination cursor from a prior response. |

### Response

```json
{
  "data": {
    "results": [
      {
        "linkedinProfileUrl": "https://www.linkedin.com/in/jane-doe-abc123",
        "profile": {
          "fullName": "Jane Doe",
          "firstName": "Jane",
          "lastName": "Doe",
          "headline": "Founder at InwestCo",
          "city": "San Francisco",
          "state": "CA",
          "country": "US",
          "experiences": [
            { "title": "Founder", "company": "InwestCo", "location": "San Francisco, CA", "startsAt": "2021-03", "endsAt": null }
          ],
          "education": [
            { "school": "Stanford University", "degree": "BS Computer Science", "schoolUrl": "https://www.linkedin.com/school/stanford-university/", "dates": "2013–2017" }
          ],
          "skills": ["Product Strategy", "AI", "Fundraising"],
          "languages": ["English"],
          "profilePicUrl": "https://media.licdn.com/..."
        },
        "lastUpdated": "2026-06-15T00:00:00Z"
      }
    ],
    "nextPage": "https://api.platform.example.com/search/person?next_token=...",
    "totalResultCount": 8269
  },
  "usage": {
    "creditsConsumed": 7,
    "usdCharged": 0.0084
  }
}
```

Not every field is guaranteed for every result — providers vary in what they expose. `linkedinProfileUrl` may occasionally point to an internal reference page when the canonical LinkedIn URL is not reliably available.

`totalResultCount` is the search backend's count for the full filter — useful for cost-preview before paginating. `nextPage` (when present) embeds a `next_token`; extract and pass as `nextToken` on the next request.

### Errors

| HTTP | Body | When |
|---|---|---|
| 402 | `{ "error": "insufficient_credits" }` | User's total Butterbase credit balance is below the minimum gate (default $0.05). No provider call is made. |
| 403 | `{ "error": "forbidden" }` | Authed user doesn't own the app. |
| 404 | `{ "error": "app_not_found" }` | No app with that ID. |
| 502 | The configured search/enrichment provider returned an upstream error. Body contains a transient error description — don't machine-parse; treat as retryable. |
| 503 | `{ "error": "people_disabled" }` | Feature flag is off on this deployment. |
| 503 | `{ "error": "people_unavailable" }` | No provider registered for this deployment. |
| 503 | `{ "error": "provider_not_registered", "slot": "primary" }` | Operator misconfiguration; no provider configured for the slot this action routed to. |
| 503 | `{ "error": "provider_action_unsupported", "slot": "primary" }` | Operator misconfiguration; the configured provider for this slot doesn't support this action. |

## Search companies

```
POST /v1/{app_id}/people/search/company
Authorization: Bearer {token}
Content-Type: application/json

{
  "industry": "Financial Services",
  "country": "US",
  "employeeCountMax": 200,
  "pageSize": 25
}
```

Accepts the same `query` field as `search/person`. When `query` is set it takes priority over structured filters.

| Field | Type |
|---|---|
| `query` | string — optional free-form natural-language description |
| `industry` | string |
| `country` | string |
| `employeeCountMax` | number |
| `pageSize` / `nextToken` | as for people search |

### Response

```json
{
  "data": {
    "results": [
      { "linkedinUrl": "https://www.linkedin.com/company/inwestco/", "name": "InwestCo", "industry": "Financial Services", "country": "US", "employeeCount": 187 }
    ],
    "nextPage": null,
    "totalResultCount": 94950
  },
  "usage": { "creditsConsumed": 7, "usdCharged": 0.0084 }
}
```

### Errors

Same error table as `search/person` above.

## Get a profile (cached)

```
POST /v1/{app_id}/people/profile
Authorization: Bearer {token}
Content-Type: application/json

{
  "linkedinProfileUrl": "https://www.linkedin.com/in/jane-doe-abc123"
}
```

| Field | Type | Notes |
|---|---|---|
| `linkedinProfileUrl` | string | Required. Normalized server-side (lowercase host/path, trim trailing slash, strip query). |
| `liveFetch` | `"force"` | Skip cache and force a live provider call. |

### Cache behavior

The first call against a given normalized URL hits the configured profile provider (~2s) and writes the result into `people_profile_cache`. Subsequent calls within the TTL are served from cache (typically <30ms) at **$0 cost**.

| Result | TTL |
|---|---|
| `ok` (profile returned) | 30 days |
| `not_found` (provider returned 404) | 7 days |
| `failed` (transient error) | 1 hour — treated as a cache miss; allows retry |

### Response — cache miss

```json
{
  "data": {
    "publicIdentifier": "jane-doe-abc123",
    "firstName": "Jane",
    "lastName": "Doe",
    "fullName": "Jane Doe",
    "headline": "VP at InwestCo",
    "occupation": "VP at InwestCo",
    "summary": "…",
    "city": "New York", "state": "NY", "country": "US",
    "experiences": [ "…" ],
    "education": [ "…" ]
  },
  "status": "ok",
  "usage": { "creditsConsumed": 2, "usdCharged": 0.040, "cached": false }
}
```

### Response — cache hit

```json
{
  "data": { "…": "same shape as above" },
  "status": "ok",
  "usage": { "creditsConsumed": 0, "usdCharged": 0, "cached": true }
}
```

### Response — not found

```json
{
  "data": null,
  "status": "not_found",
  "usage": { "creditsConsumed": 0, "usdCharged": 0, "cached": false }
}
```

### Errors

Error codes: same as [Search people](#search-people).

## Queue an async work-email lookup

Work-email lookups are asynchronous — the platform queues the request and waits for a provider webhook callback.

```
POST /v1/{app_id}/people/profile/email
Authorization: Bearer {token}
Content-Type: application/json

{
  "linkedinProfileUrl": "https://www.linkedin.com/in/jane-doe-abc123"
}
```

### Response

```json
{
  "lookupId": "0e9796cf-0b54-4d49-9fbd-80ad2a3468ae",
  "status": "pending",
  "usage": { "creditsConsumed": 3 }
}
```

Save the `lookupId` and poll `GET /email-lookup/{lookup_id}` until `status === "resolved"`.

### Errors

Error codes: same as [Search people](#search-people).

## Poll an email lookup

```
GET /v1/{app_id}/people/email-lookup/{lookup_id}
Authorization: Bearer {token}
```

```json
{
  "status": "pending" | "resolved" | "failed" | "expired",
  "email": "jane.doe@inwestco.com" | null,
  "credits_consumed": 1
}
```

`email` is populated once the webhook fires. `credits_consumed` is the total billed across the queue + resolve flow.

### Errors

Error codes: same as [Search people](#search-people).

## Audit trail

Every successful call (and every provider-thrown failure) writes a row to `people_usage_logs`:

| Column | Notes |
|---|---|
| `action` | `search_person`, `search_company`, `profile`, `profile_cache_hit`, `profile_email_queue`, `profile_email_resolved`, plus `*_error` for failures. |
| `credits_consumed` | Provider credits used. |
| `usd_cost` | What Butterbase owes the provider. |
| `usd_charged` | What was deducted from the user (may be less if balance ran out mid-call). |
| `response_status` | Provider HTTP status. |
| `linkedin_url` | When applicable. |
| `created_at` | |

Query directly via `manage_data` / `select_rows` MCP tools for usage analytics in your CRM.

## Notes

- Searches return 0 credits charged when there are 0 results.
- Cache hits don't count against the credit balance.
- `profile/email` returns 503 if async email lookups aren't enabled on this deployment. Async email lookups resolve over time. The platform handles vendor callbacks server-side; poll the `GET /people/email-lookup/{id}` endpoint to check status.

---

## API Reference / Platform API

## MCP over HTTP

The same MCP tool surface is available over HTTP:

| Method | Path | Purpose |
|--------|------|---------|
| GET, POST, DELETE | /mcp | Streamable HTTP MCP session |

Send `Authorization: Bearer {platform_api_key}` so requests run as your account. Use this when your assistant or automation can't use stdio MCP but can call HTTPS.

## Apps & regions

See the [Regions](/core-concepts/regions/) concept guide for an overview.

### List supported regions

```http
GET /v1/regions
```

Public — no API key required.

```json
{ "regions": ["us-east-1", "us-west-2"] }
```

### Create an app

```http
POST /init
Authorization: Bearer {api_key}

{
  "name": "my-app",
  "region": "us-west-2"
}
```

| Field | Required | Notes |
|-------|----------|-------|
| `name` | Yes | App display name; also used to derive the subdomain. |
| `region` | No | One of the regions returned by `GET /v1/regions`. Defaults to the platform default if omitted. |

Returns `{ app_id, api_base_url, region, ... }`.

### Move an app to another region

```http
POST /v1/apps/{app_id}/move
Authorization: Bearer {api_key}

{ "dest_region": "us-east-1" }
```

Returns `{ migration_id, status: "queued" }`. The app stays available for reads during the move; writes pause briefly during the cutover and resume automatically when the move completes.

### Check move status

```http
GET /v1/apps/{app_id}/migrations/{migration_id}
Authorization: Bearer {api_key}
```

Returns the current step, source and destination regions, and timing.

## Agent guidance

| Method | Path | Purpose |
|--------|------|---------|
| GET | /llms.txt | Plain-text guidance for LLM agents |

Provides quick start patterns, common patterns, error shape, and response metadata.

## App access mode

Control whether anonymous (unauthenticated) requests can reach the data API and realtime WebSocket. See [Access modes](/core-concepts/authentication#access-modes) for the conceptual overview.

| Method | Path | Purpose |
|--------|------|---------|
| PATCH | /v1/\{app_id}/config/access-mode | Toggle between `public` and `authenticated` |
| POST | /v1/\{app_id}/secure | Set `access_mode = "authenticated"` and create user-isolation RLS policies in one call |

### Toggle access mode

```json
PATCH /v1/{app_id}/config/access-mode
Authorization: Bearer {token}

{ "access_mode": "authenticated" }
```

### Secure (composite)

```json
POST /v1/{app_id}/secure
Authorization: Bearer {token}

{
  "tables": [
    { "table_name": "posts", "user_column": "author_id" },
    { "table_name": "comments", "user_column": "user_id", "public_read_column": "is_published" }
  ]
}
```

Pass an empty body or omit `tables` to flip access mode only. Response includes `tables_secured` and a `table_errors` array — failures on individual tables don't roll back the whole call.

## App visibility

Control whether other Butterbase users can discover and clone your app as a template. This is separate from [access mode](#app-access-mode), which controls whether anonymous requests reach the data API. An app can be `visibility="public"` (template-shareable) and `access_mode="authenticated"` (no anonymous data reads) at the same time.

`visibility` defaults to `"private"`. Set it to `"public"` to make the app appear in the dashboard Templates browser and `GET /v1/templates`. Combine with `listed: false` to keep the app clonable by direct id but hidden from browse listings.

| Method | Path | Purpose |
|--------|------|---------|
| PATCH | /v1/\{app_id}/config/visibility | Set `visibility` and optionally `listed` |

### Toggle visibility

```json
PATCH /v1/{app_id}/config/visibility
Authorization: Bearer {token}

{ "visibility": "public" }
```

Response:

```json
{ "message": "Visibility updated to \"public\"", "app_id": "{app_id}", "visibility": "public", "listed": true }
```

`listed` is optional. When `true` (the default for public apps), the app will appear in the upcoming public templates browser. Pass `"listed": false` to keep the app accessible by direct link while hiding it from the browse list.

`visibility` accepts `"public"` or `"private"`. Defaults to `"private"`.

### Read current visibility

`GET /v1/{app_id}/config` returns `visibility` and `listed` alongside the other app settings.

## Templates

Clone a public app to get a copy of its repo snapshot as a starting point for your own project.

| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/templates | Browse public app templates (anonymous) |
| GET | /v1/templates/\{app_id} | Detail for a single public app template |
| POST | /v1/templates/\{source_app_id}/clone | Start a clone of a public app. Returns `{ job_id }` |
| GET | /v1/clone-jobs/\{job_id} | Status of a clone job |
| POST | /v1/clone-jobs/\{job_id}/retry | Retry a failed clone job |

### Discover public templates

`GET /v1/templates` returns the catalog of public, listed apps across all regions. No authentication required. Supports `q` (name prefix), `region`, `sort=recent|popular`, `limit` (max 50), `offset`. Response: `{ items: [{ app_id, name, owner_display_name, region, created_at, fork_count, has_repo, schema_summary: { table_count, function_count } }], total, limit, offset }`.

`GET /v1/templates/{app_id}` returns full detail for a single template, including `tables`, `functions`, and `forks_sample` (5 most recent clones). Private or unlisted apps return 404 (no existence leak).

### Clone a public app

`POST /v1/templates/{source_app_id}/clone` creates a new app owned by the caller and copies the source into it. Body: `{ name?: string, region?: string }` — region defaults to the source's region. Source must be public; private apps return 404 (no existence leak). Returns `{ job_id, status: "pending" }`.

Poll `GET /v1/clone-jobs/{job_id}` until `status` is `"completed"` (response includes the new `dest_app_id`) or `"failed"` (response includes `error_message`). Failed jobs can be retried via `POST /v1/clone-jobs/{job_id}/retry`.

**What the clone copies:** the source app's database schema (tables, columns, indexes), row-level security policies, function code, repo files (latest snapshot at clone time), non-secret configuration (storage settings, allowed origins, OAuth provider and URLs, AI model defaults), and any rows in tables the template author marked as seed data.

**What it does not copy:** end-user accounts and sessions, OAuth client credentials, function environment variables, bring-your-own-key (BYOK) AI provider keys, custom domains, billing, function invocation history, and audit logs. The clone owner must set these up themselves. See [What a clone copies](/core-concepts/database#what-a-clone-copies) for the full breakdown.

## App repo

Push a codebase to your app as a content-addressed snapshot. Useful as a cross-device backup / source of truth for your app's files. Snapshots are content-addressed: re-pushing an unchanged file does not re-upload it. The last 5 snapshots are retained.

Repo content is stored in your app's object storage under a reserved prefix and is **not** counted as a normal storage object — uploads go through a separate two-phase flow.

Push has two phases:

1. `prepare` — send the manifest (file paths + their sha256 + sizes). Server validates and returns presigned PUT URLs for any blobs it doesn't already have.
2. `commit` — after uploading the listed blobs to S3 with the returned URLs, send the manifest again. Server verifies every blob landed at the declared size, writes the manifest, and points `latest` at the new snapshot.

| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/\{app_id}/repo/snapshots/prepare | Validate a manifest; receive presigned PUTs for missing blobs |
| POST | /v1/\{app_id}/repo/snapshots/commit | Finalize the snapshot after all blobs are uploaded |
| GET | /v1/\{app_id}/repo/snapshots | List snapshot history (newest first) |
| GET | /v1/\{app_id}/repo/snapshots/latest | Fetch the current snapshot manifest |
| GET | /v1/\{app_id}/repo/snapshots/\{snapshot_id} | Fetch a specific snapshot's manifest |
| GET | /v1/\{app_id}/repo/blobs/\{sha256} | Receive a presigned GET URL for a single blob |
| POST | /v1/\{app_id}/repo/blobs/batch | Presign multiple blob download URLs in a single call |
| DELETE | /v1/\{app_id}/repo | Wipe the entire repo |

Reads (`GET`) on a **public** app are anonymous. On a **private** app, only the owner can read or write.

### Manifest shape

```json
{
  "files": [
    { "path": "src/index.ts", "sha256": "<64 hex>", "size": 1234 }
  ],
  "message": "optional push message"
}
```

Paths must be relative, ASCII-safe, contain no `..` segments, no leading `/`, no backslashes, no null bytes, and be at most 4 KB. Hard caps: 10 MB per file, 100 MB per snapshot.

### Prepare

```json
POST /v1/{app_id}/repo/snapshots/prepare
Authorization: Bearer {token}

{ "files": [ { "path": "a.txt", "sha256": "...", "size": 5 } ] }
```

Response:

```json
{
  "snapshot_id": "<64 hex>",
  "total_bytes": 5,
  "file_count": 1,
  "missing_blobs": [ { "sha256": "...", "uploadUrl": "https://..." } ]
}
```

Upload each `missing_blob.uploadUrl` with `PUT`. The presigned URL expires after 10 minutes.

### Commit

```json
POST /v1/{app_id}/repo/snapshots/commit
Authorization: Bearer {token}

{ "manifest": { "files": [ ... ], "message": "..." } }
```

If any blob is still missing or its uploaded size doesn't match the manifest, the response is 409 with `details.missing_shas` and `details.size_mismatches`. Re-upload the listed blobs and re-call commit.

### Pull

```http
GET /v1/{app_id}/repo/snapshots/latest
```

Returns `{ snapshot_id, manifest }`. For each file in the manifest, request `GET /v1/{app_id}/repo/blobs/{sha256}` to receive a presigned GET URL (1 hour expiry), then fetch.

### Wipe

`DELETE /v1/{app_id}/repo` removes every snapshot, blob, and the `latest` pointer. Cannot be undone.

### Snapshot history

`GET /v1/{app_id}/repo/snapshots` returns `{ snapshots: [{ snapshot_id, created_at }] }` sorted newest-first. Visibility rules are the same as `latest`: anonymous on a public app, owner-only on a private one (returns 404 to non-owners — no existence leak).

### Batch blob presign

`POST /v1/{app_id}/repo/blobs/batch` accepts `{ shas: string[] }` (max 1000 entries) and returns `{ blobs: [{ sha256, size, downloadUrl, expiresIn }] }`. Missing or pruned shas are omitted from the response, so the response length can be less than the request length. Visibility rules match the single-blob endpoint: anonymous on a public app, owner-only on a private one.

This is useful when you have a manifest with many files and want to fetch all blobs without N round trips. The MCP `manage_repo` `pull_latest` action uses this internally.

## Per-app subdomains

When subdomain routing is enabled, each app has a subdomain derived from its name. Traffic to `https://{subdomain}.{base_domain}` resolves the app from the Host header, so you omit `{app_id}` from paths.

| Subdomain path | Equivalent purpose |
|----------------|-------------------|
| /data/\{table} | Data API CRUD |
| /fn/\{function_name} | Invoke function |
| /auth/signup, /auth/login, ... | End-user auth |
| /storage/upload, /storage/objects, ... | File storage |
| /schema, /schema/apply, /migrations | Schema management |

## Product suggestions

**MCP tool:** `submit_suggestion`

**HTTP:**

```json
POST /suggestions
Authorization: Bearer {api_key}

{
  "category": "feature_request",
  "description": "Add support for GraphQL subscriptions",
  "severity": "medium",
  "source": "human_prompted"
}
```

| Field | Required | Values |
|-------|----------|--------|
| `category` | Yes | `bug_report`, `feature_request`, `improvement`, `documentation` |
| `description` | Yes | Description text |
| `severity` | No | `low`, `medium`, `high`, `critical` |
| `affected_tool` | No | Tool name if applicable |
| `proposed_solution` | No | Suggested fix |
| `source` | No | `agent` or `human_prompted` |

## Health checks

| Method | Path | Purpose |
|--------|------|---------|
| GET | /health | Liveness check |
| GET | /health/ready | Readiness check (database connectivity) |

## Error format

All errors include structured objects:

```json
{
  "error": {
    "code": "RESOURCE_NOT_FOUND",
    "message": "Table 'nonexistent' does not exist",
    "remediation": "Check the table name and ensure it exists in your schema",
    "documentation_url": "https://docs.butterbase.ai/api-reference/data-api"
  }
}
```

Follow the `remediation` field before retrying.

## Rate limiting

Sensitive routes (especially auth) have strict per-route rate limits. Other routes may have additional limits depending on deployment configuration.

---

## API Reference / RAG API

All RAG endpoints are under `/v1/{app_id}/rag/`. Authentication: `Authorization: Bearer {service_key_or_jwt}`.

See [RAG (Native)](/core-concepts/rag) for conceptual overview and SDK examples.

## Collections

### Create collection

```
POST /v1/{app_id}/rag/collections
```

**Request body:**

| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `name` | string | Yes | Lowercase alphanumeric, hyphens, underscores |
| `description` | string | No | Human-readable description |
| `accessMode` | `private` \| `shared` \| `custom` | No | Default: `private` |
| `chunkSize` | number | No | Characters per chunk. Default: 512 |
| `chunkOverlap` | number | No | Overlap between chunks. Default: 64 |

**Response:** `Collection` object (201).

---

### List collections

```
GET /v1/{app_id}/rag/collections
```

**Response:** Array of `Collection` objects.

---

### Get collection

```
GET /v1/{app_id}/rag/collections/{name}
```

Returns collection details including document and chunk counts.

**Response:** `CollectionDetails` object.

---

### Delete collection

```
DELETE /v1/{app_id}/rag/collections/{name}
```

Permanently deletes the collection and all its documents, chunks, and embeddings. Irreversible.

**Response:** `204 No Content`.

---

## Documents

### Ingest document

```
POST /v1/{app_id}/rag/collections/{name}/ingest
```

Enqueues a document for async processing. Returns immediately with `status: "pending"`.

**Request body (text):**

| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `text` | string | Yes* | Raw text content to ingest |
| `filename` | string | No | Display name for the document |
| `metadata` | object | No | Arbitrary key-value metadata stored with each chunk |

**Request body (file from storage):**

| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `storage_object_id` | string | Yes* | Object ID returned by the storage upload endpoint |
| `filename` | string | No | Override display name |
| `metadata` | object | No | Arbitrary key-value metadata |

*Either `text` or `storage_object_id` is required.

**Response:** `IngestResult` object (202).

```json
{
  "documentId": "uuid",
  "status": "pending",
  "message": "Document queued for processing"
}
```

---

### List documents

```
GET /v1/{app_id}/rag/collections/{name}/documents
```

**Response:** Array of `RagDocument` objects.

---

### Get document

```
GET /v1/{app_id}/rag/collections/{name}/documents/{document_id}
```

Returns document status and metadata. Use this to poll until `status` is `ready` or `failed`.

**Response:** `RagDocument` object.

---

### Delete document

```
DELETE /v1/{app_id}/rag/collections/{name}/documents/{document_id}
```

Deletes the document and all its vector chunks. Irreversible.

**Response:** `204 No Content`.

---

## Query

### Semantic query

```
POST /v1/{app_id}/rag/collections/{name}/query
```

**Request body:**

| Field | Type | Required | Description |
|-------|------|----------|-------------|
| `query` | string | Yes | Natural language question |
| `topK` | number | No | Number of chunks to return. Default: 5 |
| `threshold` | number | No | Minimum cosine similarity (0–1). Chunks below excluded. |
| `synthesize` | boolean | No | Generate an AI answer from retrieved chunks. Default: false |
| `model` | string | No | Model for synthesis (e.g. `anthropic/claude-haiku-4-5`). Auto-selected if omitted. |
| `filter` | object | No | Metadata filter (key-value pairs). Only chunks with matching metadata are returned. |

**Response:** `QueryResult` (when `synthesize: false`) or `SynthesizedQueryResult` (when `synthesize: true`).

---

## Response schemas

### Collection

```json
{
  "id": "uuid",
  "name": "support-docs",
  "description": "Product support documentation",
  "accessMode": "shared",
  "chunkSize": 512,
  "chunkOverlap": 64,
  "createdAt": "2026-04-23T10:00:00Z",
  "updatedAt": "2026-04-23T10:00:00Z"
}
```

### CollectionDetails

Extends `Collection` with:

```json
{
  "documentCount": 12,
  "chunkCount": 347
}
```

### RagDocument

```json
{
  "id": "uuid",
  "collectionId": "uuid",
  "filename": "refund-policy.pdf",
  "status": "ready",
  "chunkCount": 28,
  "metadata": {},
  "errorMessage": null,
  "createdAt": "2026-04-23T10:00:00Z",
  "updatedAt": "2026-04-23T10:01:30Z"
}
```

**Status values:** `pending` → `processing` → `ready` | `failed`

### IngestResult

```json
{
  "documentId": "uuid",
  "status": "pending",
  "message": "Document queued for processing"
}
```

### QueryResult

```json
{
  "chunks": [
    {
      "text": "Refunds are accepted within 30 days...",
      "score": 0.92,
      "documentId": "uuid",
      "metadata": {}
    }
  ]
}
```

### SynthesizedQueryResult

Extends `QueryResult` with:

```json
{
  "chunks": [...],
  "answer": "Refunds are accepted within 30 days of purchase with a valid receipt.",
  "model": "anthropic/claude-haiku-4-5"
}
```

---

## API Reference / Storage API

## Endpoints

| Method | Path | Purpose |
|--------|------|---------|
| POST | /storage/\{app_id}/upload | Request a presigned upload URL |
| GET | /storage/\{app_id}/objects | List all files for the app |
| GET | /storage/\{app_id}/download/\{object_id} | Request a presigned download URL |
| DELETE | /storage/\{app_id}/\{object_id} | Delete a file |

## Upload

```json
POST /storage/{app_id}/upload
Authorization: Bearer {token}

{
  "filename": "profile.jpg",
  "contentType": "image/jpeg",
  "sizeBytes": 102400,
  "public": false
}
```

Set `public: true` to mark the uploaded file as downloadable by any authenticated user (not just the uploader). See [Public files](/core-concepts/storage#public-files).

**Response:**

```json
{
  "uploadUrl": "https://storage.example.com/...",
  "objectKey": "app_id/user_id/uuid_profile.jpg",
  "objectId": "uuid",
  "expiresIn": 300
}
```

Then upload the file:

```javascript
await fetch(uploadUrl, {
  method: 'PUT',
  headers: { 'Content-Type': 'image/jpeg' },
  body: fileBlob
});
```

## Download

```json
GET /storage/{app_id}/download/{object_id}
Authorization: Bearer {token}
```

**Response:**

```json
{
  "downloadUrl": "https://storage.example.com/...",
  "filename": "profile.jpg",
  "expiresIn": 3600
}
```

## List files

```
GET /storage/{app_id}/objects
Authorization: Bearer {token}
```

Returns array of `{ id, filename, content_type, size_bytes, created_at }`.

## URL expiration

| URL type | Expiration |
|----------|-----------|
| Upload | 5 minutes |
| Download | 1 hour |

## Storage limits

| Limit | Default |
|-------|---------|
| Max file size | 10 MB |
| Total storage | 1 GB per app |
| Content types | All (configurable) |

## Access control

| Auth | Access |
|------|--------|
| Service key | All files, no user association |
| End-user JWT | Own files only, auto-associated |

## App-wide storage configuration

| Method | Path | Purpose |
|--------|------|---------|
| PATCH | /v1/\{app_id}/config/storage | Toggle app-wide public read access |

```json
PATCH /v1/{app_id}/config/storage
Authorization: Bearer {token}

{ "publicReadEnabled": true }
```

**Response:**

```json
{
  "message": "Storage configuration updated successfully",
  "app_id": "app_abc123",
  "storage_config": {
    "maxFileSizeMb": 10,
    "allowedContentTypes": ["*/*"],
    "publicReadEnabled": true
  }
}
```

When `publicReadEnabled` is `true`, any authenticated user can download any file in the app. Uploads and deletes remain user-scoped.

---

## API Reference / Substrate API

The substrate API is a per-user surface: every route operates on the substrate that belongs to the calling user, identified by the Bearer token. There is no `{app_id}` path segment.

## Authentication

All routes accept either:

- A **substrate-scoped API key**: `Authorization: Bearer bb_sub_…` (generate with `butterbase keys generate --substrate`).
- A **platform JWT** (dashboard / Cognito session).

Non-substrate-scoped API keys (`bb_sk_…`) are not accepted by these routes — they return `403`.

Errors follow the standard envelope:

```json
{ "error": { "code": "AUTH_INVALID_TOKEN", "message": "…", "remediation": "…" } }
```

## Settings

| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/me/substrate/settings | Get yolo mode and other per-user toggles |
| PUT | /v1/me/substrate/settings/yolo | Toggle yolo mode |

```json
PUT /v1/me/substrate/settings/yolo
{ "yolo_mode": true }
```

## Actions

| Method | Path | Purpose |
|--------|------|---------|
| POST | /v1/me/substrate/actions/propose | Propose a new action |
| GET | /v1/me/substrate/actions | List actions in the ledger |
| GET | /v1/me/substrate/actions/\{action_id} | Fetch one action |
| POST | /v1/me/substrate/actions/\{action_id}/approve | Approve a pending action |
| POST | /v1/me/substrate/actions/\{action_id}/reject | Reject a pending action |

### Propose

```json
POST /v1/me/substrate/actions/propose
{
  "capability": "record_decision",
  "payload": { "title": "…", "kind": "operational", "rationale": "…" },
  "idempotency_key": "optional-stable-string"
}
```

Response:

```json
{
  "action_id": "act_01…",
  "verdict": { "result": "auto_approved", "reason": "capability default = auto" },
  "requires_approval": false,
  "result": { "decision_id": "dec_01…" }
}
```

Verdict values: `auto_approved`, `auto_approved_yolo`, `requires_approval`, `rejected`.

#### `idempotency_key` — deduplicating retries

`idempotency_key` is an optional string field in the request body. When set, the substrate deduplicates retries so that a network blip or a lambda re-run does not produce a duplicate ledger row.

- **Scope:** per substrate user. Two different users can use the same key without collision.
- **Window:** forever. Keys are never aged out. Pick keys that are stable for the unit-of-work you are deduplicating (e.g. `meeting_id + ":" + capability` is a good choice; a per-call UUID is not).
- **Collision behavior:** if a prior action with the same `(substrate_user_id, idempotency_key)` exists, the propose returns that prior action's verdict and result without executing the capability again.
- **Response shape on replay:** the response is identical to the original — same `action_id`, same `verdict` (with `conflicts` always empty on replay), same `result`. The replay reflects the action's **current** status: if the original action was later approved, `requires_approval` on the replay will be `false`. A top-level `"replay": true` field is added so callers can distinguish a replay from a fresh propose.

Example — same key sent twice:

```json
// First call — fresh propose
POST /v1/me/substrate/actions/propose
{
  "capability": "record_decision",
  "payload": { "title": "Migrate billing to Stripe", "kind": "strategic" },
  "idempotency_key": "mtg_2026-06-16:record_decision"
}
// → { "action_id": "act_01…", "verdict": { … }, "requires_approval": false, "result": { … } }

// Second call — same key, same user
POST /v1/me/substrate/actions/propose
{ …same body… }
// → { "action_id": "act_01…", "verdict": { … }, "requires_approval": false, "result": { … }, "replay": true }
```

For the capability payload schemas, see [Capability payloads](#capability-payloads).

### List

```
GET /v1/me/substrate/actions?status=executed&capability=send_email_draft&limit=25&before=2026-05-28T00:00:00Z
```

| Query param | Type | Default |
|---|---|---|
| `status` | `proposed` \| `executed` \| `rejected` | _all_ |
| `capability` | string | _all_ |
| `limit` | int (1–500) | 100 |
| `before` | ISO timestamp | _now_ |
| `source_app_id` | string | _all_ |
| `source_rule_id` | string | _all_ |

### Approve / reject

```
POST /v1/me/substrate/actions/{action_id}/approve
POST /v1/me/substrate/actions/{action_id}/reject
{ "reason": "policy mismatch" }
```

Both return the updated action row. Approving or rejecting an action that is not in `proposed` status returns `409 wrong_status`.

## Entities

| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/me/substrate/entities | List entities |
| GET | /v1/me/substrate/entities/\{entity_id} | Fetch one entity |
| PATCH | /v1/me/substrate/entities/\{entity_id} | Update an entity (routed through propose) |

```
GET /v1/me/substrate/entities?type=person&q=alice&limit=20&count=true
```

| Query param | Type | Default |
|---|---|---|
| `type` | `person` \| `company` \| `fund` \| `workspace` \| `team` \| `project` \| `event` \| `agent` \| `self` | _all_ |
| `q` | string (display-name search) | _none_ |
| `limit` | int (1–200) | 50 |
| `count` | `true` to include `total` in response | `false` |

## Source artifacts

Source artifacts are durable, full-text-indexed source material — meeting transcripts, email threads, call recordings, documents — that the substrate extracts decisions, commitments, and learnings from. A commitment can carry a `source_artifact_id` pointing back to the artifact it was extracted from.

| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/me/substrate/source-artifacts | List / filter / FTS over artifacts |
| GET | /v1/me/substrate/source-artifacts/\{artifact_id} | Fetch one artifact (incl. full `content`) |

```
GET /v1/me/substrate/source-artifacts?kind=meeting_transcript&q=billing&limit=20&count=true
```

| Query param | Type | Default |
|---|---|---|
| `kind` | string | _all_ |
| `q` | string (FTS over `title + summary + content`) | _none_ |
| `limit` | int (1–200) | 50 |
| `count` | `true` to include `total` in response | `false` |

Response:

```json
{
  "artifacts": [
    {
      "id": "art_01…",
      "kind": "meeting_transcript",
      "external_system": "fireflies",
      "external_id": "abc123",
      "title": "Weekly product sync — 2026-06-09",
      "summary": "Reviewed phase 6 scope; Alice owns billing migration.",
      "url": "https://fireflies.ai/…",
      "storage_object_id": null,
      "links": { "entity_ids": ["ent_01…"], "project_tags": ["phase-6"] },
      "attrs": {},
      "source_app_id": "app_…",
      "created_at": "2026-06-09T…",
      "updated_at": "2026-06-09T…"
    }
  ]
}
```

`GET /v1/me/substrate/source-artifacts/{artifact_id}` returns the same shape plus the full `content` field.

Artifacts are written via the `upsert_source_artifact` capability through `POST /v1/me/substrate/actions/propose`. Upsert is idempotent: if `id` is omitted, the substrate resolves the row by `(external_system, external_id)`; otherwise it generates an `art_`. Artifacts proposed by an installed app are auto-attributed to that app via `source_app_id`.

## Memory search

Full-text search across `decisions`, `commitments`, `learnings`, and `source_artifacts`.

```
GET /v1/me/substrate/memory?q=billing&kinds=decisions,commitments&limit=20
```

`kinds` accepts any subset of `decisions`, `commitments`, `learnings`, `source_artifacts` (comma-separated). Omitting `kinds` searches all of them.

| Query param | Type | Default |
|---|---|---|
| `q` | string (FTS query; omit or pass `*` to list all) | _none_ |
| `kinds` | comma-separated subset of `decisions`, `commitments`, `learnings`, `source_artifacts` | _all_ |
| `limit` | int (1–200) | 20 |
| `match` | `and` \| `or` \| `phrase` | `and` |

When `q` is omitted or empty (or `*`), the endpoint returns the most recent items across the selected kinds ordered by `updated_at DESC`, capped by `limit`. No full-text ranking is performed — `rank` will be `null` in those rows. Use this as a "list all" path.

`match` controls how multi-word queries are evaluated: `and` requires all words (default), `or` matches any word, `phrase` requires words to appear adjacently. Omitting `match` is identical to `match=and`.

:::note[When to use which]
Use `GET /v1/me/substrate/memory` when you need FTS-ranked results and a relevance score (`rank`). Use `GET /v1/me/substrate/memory/list` when you need chronological ordering or structural filters (kind subset, source artifact scope, superseded status). The two endpoints share the same underlying tables but serve different query shapes.
:::

Response:

```json
{
  "results": [
    {
      "id": "dec_01…",
      "kind": "decision",
      "title": "Adopt substrate",
      "body_text": "agent memory needs a single source of truth",
      "rank": 0.18,
      "updated_at": "2026-05-31T…",
      "source_artifact_id": null,
      "supersedes": null,
      "status": "active"
    },
    {
      "id": "art_01…",
      "kind": "source_artifact",
      "title": "Weekly product sync — 2026-06-09",
      "body_text": "Reviewed phase 6 scope; Alice owns billing migration.",
      "rank": 0.12,
      "updated_at": "2026-06-09T…",
      "source_artifact_id": null,
      "supersedes": null,
      "status": null
    }
  ]
}
```

Three fields are present on every result row:

| Field | Type | Notes |
|---|---|---|
| `source_artifact_id` | `string \| null` | Back-pointer to the source artifact this memory was extracted from. `null` for source artifacts themselves and for items ingested without one. |
| `supersedes` | `string \| null` | Only set on `kind: 'decision'` rows where this decision replaces an earlier one (holds the replaced decision ID). |
| `status` | `string \| null` | `'active'` / `'superseded'` / `'reversed'` / `'expired'` for decisions; `'proposed'` / `'confirmed'` / `'fulfilled'` / `'expired'` / `'broken'` / etc. for commitments; `null` for learnings and source_artifacts. |

## Memory list (chronological browse)

Chronological browse across `decisions`, `commitments`, `learnings`, and `source_artifacts` with structural filters. Unlike the FTS search endpoint, results are always ordered by `updated_at DESC` and there is no relevance ranking.

```
GET /v1/me/substrate/memory/list?source_artifact_id=art_…&kinds=decisions,commitments,learnings&limit=25
```

| Query param | Type | Default |
|---|---|---|
| `kinds` | comma-separated subset of `decisions`, `commitments`, `learnings`, `source_artifacts` | _all_ |
| `source_artifact_id` | string | _none_ |
| `superseded` | `true` \| `false` | _include all_ |
| `before` | ISO timestamp (keyset cursor from `next_before`) | _none_ |
| `limit` | int (1–100) | 25 |

**`source_artifact_id`** restricts results to rows linked to that source artifact. Source-artifact rows themselves are excluded from the response when this filter is set, because they carry no `source_artifact_id` back-pointer of their own.

**`superseded`** when `false`, excludes decisions with `status='superseded'` and commitments with `status='expired'`. When `true` or omitted, all statuses are returned.

**`before`** accepts the `next_before` value from a previous response for keyset pagination. Pass it verbatim — it is an ISO timestamp.

Response:

```json
{
  "results": [
    {
      "id": "dec_…",
      "kind": "decision",
      "title": "…",
      "body_text": "…",
      "updated_at": "…",
      "source_artifact_id": "art_…",
      "supersedes": "dec_…",
      "status": "active"
    }
  ],
  "next_before": "2026-06-09T14:32:00.000Z"
}
```

`next_before` is `null` when there are no more pages.

`status` is set on decisions and commitments; `null` for learnings and source_artifacts. `supersedes` is only set on decisions that replace an earlier decision.

### Example — list every decision, commitment, and learning extracted from a meeting

```
GET /v1/me/substrate/memory/list
  ?source_artifact_id=art_01JXYZ…
  &kinds=decisions,commitments,learnings
  &superseded=false
  &limit=50
```

Response:

```json
{
  "results": [
    {
      "id": "dec_01JXYZ…",
      "kind": "decision",
      "title": "Ship phase 6 by end of June",
      "body_text": "Agreed in the weekly sync. Alice owns the billing migration.",
      "updated_at": "2026-06-09T14:30:00.000Z",
      "source_artifact_id": "art_01JXYZ…",
      "supersedes": null,
      "status": "active"
    },
    {
      "id": "com_01JXYZ…",
      "kind": "commitment",
      "title": "Alice to deliver billing migration PR by 2026-06-13",
      "body_text": null,
      "updated_at": "2026-06-09T14:30:01.000Z",
      "source_artifact_id": "art_01JXYZ…",
      "supersedes": null,
      "status": "confirmed"
    }
  ],
  "next_before": null
}
```

## Capabilities

A few capabilities accept fields that aren't obvious from their name:

| Capability | Optional fields | Notes |
|---|---|---|
| `record_commitment` | `source_artifact_id`, `attrs` | `source_artifact_id` links the commitment back to the artifact it was extracted from (FK to `source_artifacts(id) ON DELETE SET NULL`). `attrs` is a free-form JSON bag for caller metadata. |
| `upsert_source_artifact` | `id`, `external_system`, `external_id`, `summary`, `content`, `storage_object_id`, `url`, `links`, `attrs` | Required: `kind`, `title`. Idempotent by `(external_system, external_id)` when `id` is omitted. `default_policy='auto'`, `reversible=true`, `yolo_eligible=true`. Returns `{ artifact_id, was_insert, before }`. |

## Capability payloads

For the default-policy and flags for every capability, see the [Capabilities at a glance table](/core-concepts/substrate/#capabilities-at-a-glance) in the concept doc.

The schemas below list exact field names and types as defined in the capability Zod schemas. Fields marked optional may be omitted.

### Memory writes

```
record_decision
  required: title (string), kind ('operational'|'strategic'|'mission'|'vision'|'principle'|'policy_decision')
  optional: rationale (string), salience ('ambient'|'normal'|'archival', default 'normal'), source_artifact_id (string)
  default_policy: auto

record_commitment
  required: description (string), status ('proposed'|'tentative'|'confirmed'|'fulfilled'|'expired'|'broken')
  optional: from_entity (string), to_entity (string), amount (number), unit (string), due_at (string, ISO 8601), source_artifact_id (string), attrs (object)
  default_policy: auto

record_learning
  required: title (string), description (string)
  optional: resolution_taken (string), related_decision_id (string), source_artifact_id (string)
  default_policy: auto

record_principle
  required: title (string), applies_to (object, e.g. {capability: "send_email_draft", target_role: "investor"}), constraint_spec (object, e.g. {type: "max_per_week", params: {n: 2}})
  optional: rationale (string), salience ('ambient'|'normal'|'archival', default 'ambient')
  default_policy: approval_required

supersede_decision
  required: old_decision_id (string), new_title (string), kind ('operational'|'strategic'|'mission'|'vision'|'principle'|'policy_decision')
  optional: new_rationale (string)
  default_policy: approval_required

retire_principle
  required: principle_id (string), reason (string)
  default_policy: approval_required
```

### Entity writes

```
upsert_entity
  required: type ('person'|'company'|'fund'|'workspace'|'team'|'project'|'event'|'agent'|'self'), display_name (string)
  optional: id (string), primary_email (string, email), canonical_keys (object), linked_app_user_id (string, uuid), linked_app_id (string), attrs (object)
  default_policy: auto
  note: dedups by id > canonical_keys > primary_email

update_entity
  required: id (string)
  optional: display_name (string), primary_email (string, email), attrs (object)
  default_policy: auto
  note: replaces attrs wholesale; prefer patch_entity for partial updates

patch_entity
  required: id (string)
  optional: display_name (string), primary_email (string, email), attrs_patch (object, RFC 7396 merge-patch), if_updated_at (string, datetime, optimistic lock)
  default_policy: auto

merge_entities
  required: loser_id (string), winner_id (string), reason (string)
  default_policy: approval_required

delete_entity
  required: id (string), reason (string)
  default_policy: approval_required
```

### Source artifacts

```
upsert_source_artifact
  required: kind (string), title (string)
  optional: id (string), external_system (string), external_id (string), summary (string), content (string), storage_object_id (string), url (string), links ({entity_ids?: string[], project_tags?: string[]}), attrs (object)
  default_policy: auto
  note: idempotent by (external_system, external_id) when id is omitted
```

### Revert / bulk-revert

```
revert_action
  required: action_id (string)
  default_policy: auto

bulk_revert_actions
  required: action_ids (string[], 1–200 items), reason (string)
  default_policy: approval_required
```

### Side-effecting

```
send_email_draft
  required: to (string), subject (string), body (string)
  optional: target_role (string)
  default_policy: approval_required
```

## Daily snapshots

Snapshots are the basis for attention-rule `snapshot_predicate` conditions.

```
GET /v1/me/substrate/snapshots?days=7
```

Response:

```json
{
  "snapshots": [
    { "snapshot_date": "2026-05-31", "entity_count": 12, "decision_count": 8, "…": "…" }
  ]
}
```

## Attention rules

| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/me/substrate/attention-rules | List rules |
| GET | /v1/me/substrate/attention-rules/\{rule_id} | Fetch one rule |
| POST | /v1/me/substrate/attention-rules | Create a rule |
| PUT | /v1/me/substrate/attention-rules/\{rule_id} | Update a rule |
| DELETE | /v1/me/substrate/attention-rules/\{rule_id} | Delete a rule |
| POST | /v1/me/substrate/attention-rules/\{rule_id}/enable | Enable |
| POST | /v1/me/substrate/attention-rules/\{rule_id}/disable | Disable |
| POST | /v1/me/substrate/attention-rules/preview | Dry-run a rule body against today's snapshot |
| GET | /v1/me/substrate/attention-rules/\{rule_id}/firings | List firings |

### Rule body

```json
{
  "name": "weekly digest",
  "description": "Monday morning summary",
  "trigger_cron": "0 9 * * 1",
  "condition_mode": "snapshot_predicate",
  "condition": { ">": [ { "var": "entity_count" }, 0 ] },
  "action_capability": "send_email_draft",
  "action_payload_template": {
    "to": "you@example.com",
    "subject": "Weekly digest",
    "body": "{{entity_count}} entities."
  },
  "enabled": true,
  "max_fires_per_day": 1
}
```

| Field | Required | Notes |
|---|---|---|
| `name` | yes | Display name. |
| `trigger_cron` | yes | Standard 5-field cron expression (UTC). |
| `condition_mode` | yes | `snapshot_predicate` evaluates a JSON-Logic predicate against today's snapshot. `row_query` runs the condition as a row-query (advanced). |
| `condition` | yes | JSON-Logic object. Available variables depend on `condition_mode`. |
| `action_capability` | yes | The capability to propose when the rule fires. |
| `action_payload_template` | yes | Object with `{{var}}` placeholders interpolated from the matched binding. |
| `enabled` | no | Defaults to `true`. |
| `max_fires_per_day` | no | Caps daily proposals. |

### Preview

```json
POST /v1/me/substrate/attention-rules/preview
{  }
```

Response:

```json
{
  "bindings_count": 3,
  "sample_proposals": [
    { "binding": { "entity_count": 12 }, "rendered_payload": { … }, "would_require_approval": false }
  ],
  "skip_reason": null
}
```

`skip_reason` is set (and `bindings_count` is 0) when the snapshot is missing or the condition can't be evaluated.

## Outbox targets

When an action with `capability X` executes, the substrate POSTs the rendered payload to the registered outbox target for `X` (if any). Deliveries are HMAC-signed and retried with backoff.

| Method | Path | Purpose |
|--------|------|---------|
| GET | /v1/me/substrate/outbox-targets | List all targets |
| PUT | /v1/me/substrate/outbox-targets/\{capability} | Register or replace a target |
| DELETE | /v1/me/substrate/outbox-targets/\{capability} | Remove the target |

```json
PUT /v1/me/substrate/outbox-targets/send_email_draft
{
  "webhook_url": "https://example.com/hooks/substrate",
  "signing_secret": "min-8-chars",
  "source_app_id": "app_optional_scope"
}
```

`source_app_id` is optional; when set, the target only fires for actions proposed by that app.

### Webhook delivery

```
POST https://example.com/hooks/substrate
Content-Type: application/json
X-Butterbase-Signature: sha256=
X-Butterbase-Delivery:

{
  "action_id": "act_01…",
  "capability": "send_email_draft",
  "payload": { … the rendered action payload … },
  "executed_at": "2026-05-31T…"
}
```

Verify the signature with HMAC-SHA-256 over the raw body using `signing_secret`.

## WebSocket stream

Live push of every change to the caller's substrate.

```
GET /v1/me/substrate/stream
```

### Browser flow

Browsers can't send custom headers on a WebSocket upgrade, so the stream accepts a one-shot ticket.

1. Mint a ticket (Cognito or `bb_sub_` Bearer):

   ```
   POST /v1/me/substrate/ws-ticket
   ```

   ```json
   { "ticket": "wst_…", "expires_in": 60 }
   ```

2. Open the WS with `?ticket=`:

   ```
   wss://api.butterbase.ai/v1/me/substrate/stream?ticket=wst_…
   ```

Tickets are **single-use** and expire after 60 seconds. Reused or expired tickets close the WS with code `1008 unauthenticated`.

### Server-side flow

Programmatic / server clients can put the substrate-scoped key in the Authorization header on the upgrade:

```
GET /v1/me/substrate/stream
Upgrade: websocket
Authorization: Bearer bb_sub_…
```

Or as a fallback query string:

```
wss://api.butterbase.ai/v1/me/substrate/stream?token=bb_sub_…
```

### App-function flow

An app linked to an org can mint a ticket for its own users **without** ever putting a substrate key in the browser. Inside a deployed function, call:

```ts
const { ticket, expires_in } = await ctx.substrate.wsTicket();
```

It returns a 60s single-use ticket scoped to the app's linked org (server-to-server, over the internal bridge). Return it to the browser, which opens the stream with `?ticket=`. This is the recommended pattern for end-user-facing apps — see the [browser example](/core-concepts/substrate/#8-stream-live-updates-to-a-ui).

### Frames

```json
// First frame on open:
{ "type": "hello", "ts": 1780198304 }

// Subsequent frames, one per change — envelope only, no row payload:
{ "tbl": "entities",               "op": "insert", "id": "ent_…",  "org": "…" }
{ "tbl": "action_ledger",          "op": "insert", "id": "act_…",  "org": "…" }
{ "tbl": "decisions",              "op": "insert", "id": "dec_…",  "org": "…" }
{ "tbl": "commitments",            "op": "update", "id": "com_…",  "org": "…" }
{ "tbl": "learnings",              "op": "insert", "id": "lrn_…",  "org": "…" }
{ "tbl": "attention_rules",        "op": "update", "id": "rule_…", "org": "…" }
{ "tbl": "attention_rule_firings", "op": "insert", "id": "fire_…", "org": "…" }
```

Each change frame is `{ org, op, tbl, id }`:

| Field | Meaning |
|---|---|
| `org` | The substrate organization the change belongs to. The stream is **org-scoped** — a connection only ever receives changes for the org bound to its ticket or key. |
| `op` | `insert`, `update`, or `delete`. |
| `tbl` | The physical table that changed (e.g. `entities`, `action_ledger`, `decisions`). |
| `id` | The changed row's id. |

The stream does not include payloads — clients are expected to re-fetch the affected row by id.

### Close codes

| Code | Meaning |
|---|---|
| 1000 | Normal close (initiated by client) |
| 1008 | Ticket missing, expired, reused, or token rejected |

## SDK / CLI

- **CLI**: see [`butterbase substrate`](/cli/substrate/) for every command.
- **TypeScript SDK**: substrate calls are namespaced under `butterbase.substrate.*` (mirror of the HTTP surface).
- **Inside a function**: `ctx.substrate.*` (`propose`, `getEntity`, `findEntities`, `searchMemory`, `listMemory`) — see [Substrate](/core-concepts/substrate/).

---

## Reference / Error Reference

Every Butterbase API error response follows the agent-friendly shape defined by `AgentFriendlyError`:

```json
{
  "error": {
    "code": "RESOURCE_NOT_FOUND",
    "message": "App \"my-app\" not found",
    "remediation": "Verify the app_id is correct. Use list_apps to see available apps.",
    "documentation_url": "https://docs.butterbase.ai/errors#resource-not-found",
    "details": { }
  }
}
```

The `documentation_url` field links to the matching anchor on this page. Codes are grouped by category below.

## Validation errors

These indicate that the request payload, schema, or input value is malformed or fails validation. They typically map to HTTP `400 Bad Request`.

### Validation Invalid Schema

**Code:** `VALIDATION_INVALID_SCHEMA`
**Status:** 400

The request body does not conform to the expected schema (missing required fields, wrong shape, or invalid combinations).

**Remediation:** Review the validation errors in the response `details` field and correct your input. Compare your payload against the API reference for the endpoint you called.

### Validation Missing Field

**Code:** `VALIDATION_MISSING_FIELD`
**Status:** 400

A required field was not provided in the request body.

**Remediation:** Add the missing field listed in `details`. Required fields are documented per endpoint in the API reference.

### Validation Invalid Type

**Code:** `VALIDATION_INVALID_TYPE`
**Status:** 400

A field was provided with the wrong JSON type (e.g. string where an array was expected, or a non-numeric value for a numeric column).

**Remediation:** Cast or rewrite the value to match the expected type. For database columns, the schema declares the column type — JSON columns require a JSON value (object/array), not a stringified literal.

### Validation Invalid Input

**Code:** `VALIDATION_INVALID_INPUT`
**Status:** 400

PostgreSQL rejected the value as malformed user input — invalid JSON, bad numeric or date format, value too long for the column, or out-of-range numeric value (SQLSTATE class 22).

**Remediation:** Check that each field matches its column type. JSON columns require a JSON value (object/array), not a stringified array literal; numeric/date columns require properly formatted values.

### Validation Column Not Found

**Code:** `VALIDATION_COLUMN_NOT_FOUND`
**Status:** 400

The request references a column that does not exist on the target table.

**Remediation:** Check the table's current schema with `manage_schema` (action `inspect`) and verify column names. Column names are case-sensitive.

### Validation Table Not Found

**Code:** `VALIDATION_TABLE_NOT_FOUND`
**Status:** 400

The request references a table that does not exist in the app's schema.

**Remediation:** List existing tables via `manage_schema` or the dashboard. Create the table first if it is missing, or correct the table name.

### Validation Invalid Name

**Code:** `VALIDATION_INVALID_NAME`
**Status:** 400

A name (table, column, app, function, etc.) violates Butterbase's naming rules — usually disallowed characters, reserved words, or length limits.

**Remediation:** Use lowercase letters, numbers, and underscores. Names must start with a letter and avoid SQL reserved words. See the schema design guide for the full ruleset.

### Validation Constraint Violation

**Code:** `VALIDATION_CONSTRAINT_VIOLATION`
**Status:** 400

A database constraint was violated, but the violation could not be classified into one of the more specific constraint codes below.

**Remediation:** Inspect `details.constraint_details` for the underlying constraint name and adjust the request payload accordingly.

### Validation Unique Constraint Violation

**Code:** `VALIDATION_UNIQUE_CONSTRAINT_VIOLATION`
**Status:** 409

The insert/update would create a duplicate value for a column with a unique constraint.

**Remediation:** This record already exists. Use a different value for the unique field, or update the existing record instead.

### Validation Foreign Key Violation

**Code:** `VALIDATION_FOREIGN_KEY_VIOLATION`
**Status:** 400

The value provided for a foreign-key column does not match any row in the referenced table.

**Remediation:** Ensure all foreign key references point to existing records. Insert the parent row first, or correct the reference to an existing row.

### Validation Check Constraint Violation

**Code:** `VALIDATION_CHECK_CONSTRAINT_VIOLATION`
**Status:** 400

A `CHECK` constraint declared on the table rejected the value (e.g. a numeric range, regex, or domain rule).

**Remediation:** Review the constraint definition (visible in the schema) and adjust your input to satisfy it.

### Validation Not Null Violation

**Code:** `VALIDATION_NOT_NULL_VIOLATION`
**Status:** 400

A non-nullable column was not provided in the request, and no default is configured.

**Remediation:** Provide a value for the column listed in `details.column`, or set a default in the schema (e.g. `"default": "gen_random_uuid()"` for uuid columns, `"default": "now()"` for timestamps) so it auto-populates on insert.

## Authentication & authorization errors

These indicate that the caller is not authenticated, lacks permission, or supplied an invalid token. They typically map to HTTP `401 Unauthorized` or `403 Forbidden`.

### Auth Required

**Code:** `AUTH_REQUIRED`
**Status:** 401

The endpoint requires authentication but no credentials were supplied.

**Remediation:** Send an `Authorization: Bearer ` header. Use a service key for server-to-server calls or an end-user JWT for user-scoped calls.

### Auth Invalid Token

**Code:** `AUTH_INVALID_TOKEN`
**Status:** 401

The bearer token is malformed, signed with the wrong key, or otherwise invalid.

**Remediation:** Verify the token is the one issued to your app and was not modified in transit. Generate a fresh token if needed.

### Auth Invalid API Key

**Code:** `AUTH_INVALID_API_KEY`
**Status:** 401

The supplied API key (e.g. `bb_sk_...`) does not match a known key for this app, or the key has been revoked.

**Remediation:** Check the key in your dashboard's API Keys page. Generate a new service key if the old one was rotated. Keys are app-scoped — using a key from one app against another's endpoint will fail.

### Auth Insufficient Permissions

**Code:** `AUTH_INSUFFICIENT_PERMISSIONS`
**Status:** 403

The caller is authenticated but does not have permission to perform this action (e.g. a publishable key being used for a service-only endpoint).

**Remediation:** Use credentials with the required scope. Service keys can do everything; publishable keys are limited to client-safe operations.

### Auth Invalid End User JWT

**Code:** `AUTH_INVALID_END_USER_JWT`
**Status:** 401

The end-user JWT is invalid, signed with the wrong key, or end-user authentication is not configured for this app.

**Remediation:** Verify the `Authorization: Bearer` token is a valid JWT issued for this app. If end-user auth has not been set up, configure OAuth or generate a signing key first via `configure_oauth_provider`.

### Auth End User JWT Expired

**Code:** `AUTH_END_USER_JWT_EXPIRED`
**Status:** 401

The end-user session token has expired.

**Remediation:** Sign in again or refresh your session to obtain a new end-user token, then retry the request.

### Auth RLS Requires User JWT

**Code:** `AUTH_RLS_REQUIRES_USER_JWT`
**Status:** 401

The table has Row-Level Security enabled and requires an authenticated end-user. The request was made with a service key or anonymous credentials.

**Remediation:** Send an end-user JWT in the `Authorization` header. Service keys bypass RLS only when explicitly configured; for user-scoped data access use the end-user token your auth flow issues.

### Auth RLS Policy Violation

**Code:** `AUTH_RLS_POLICY_VIOLATION`
**Status:** 403

The end-user is authenticated but RLS policies on the target table do not permit this row or operation.

**Remediation:** Verify the policy allows the action for this user. Use `manage_rls` to inspect policies, or see the [Row-Level Security guide](/core-concepts/row-level-security/) for debugging.

## Resource errors

These indicate that the target resource does not exist or is in a conflicting state.

### Resource Not Found

**Code:** `RESOURCE_NOT_FOUND`
**Status:** 404

The requested resource (app, function, deployment, file, row, etc.) does not exist or is not accessible to the caller.

**Remediation:** Verify the identifier. Use the corresponding `list_*` MCP tool (e.g. `list_apps`, `list_functions`) to enumerate available resources.

### App Not Found

**Code:** `APP_NOT_FOUND`
**Status:** 404

The `app_id` in the request does not match any app you can access.

**Remediation:** Run `list_apps` to see your apps, or check the dashboard for the correct ID. App IDs are short slugs, not UUIDs.

### Resource Already Exists

**Code:** `RESOURCE_ALREADY_EXISTS`
**Status:** 409

A resource with the supplied identifier already exists and creation was attempted again.

**Remediation:** Either use the existing resource, choose a different identifier, or update instead of create.

### Resource Conflict

**Code:** `RESOURCE_CONFLICT`
**Status:** 409

The operation cannot proceed because of a concurrent modification or an inconsistent target state.

**Remediation:** Re-fetch the resource to see its current state, then retry the operation with up-to-date inputs.

## Quota errors

These indicate plan limits or per-resource quotas have been reached. They typically map to HTTP `402 Payment Required` or `429 Too Many Requests`.

### Quota Storage Exceeded

**Code:** `QUOTA_STORAGE_EXCEEDED`
**Status:** 402

The app has used all of its allowed storage. Further uploads are rejected.

**Remediation:** Delete unused files or upgrade the app's plan. The current usage and limit are returned in the response details.

### Quota File Size Exceeded

**Code:** `QUOTA_FILE_SIZE_EXCEEDED`
**Status:** 413

A single file exceeds the per-file size limit configured for the app's storage bucket or plan.

**Remediation:** Split the file, compress it, or upgrade the plan to raise the per-file limit. The configured limit is included in the error message.

### Quota Storage Error

**Code:** `QUOTA_STORAGE_ERROR`
**Status:** 500

An internal error occurred while checking the storage quota.

**Remediation:** Retry the upload. If the error persists, contact support — this typically indicates a transient backend issue, not an actual quota breach.

### Quota Rate Limit

**Code:** `QUOTA_RATE_LIMIT`
**Status:** 429

The caller exceeded the request-rate limit for this endpoint or app.

**Remediation:** Back off and retry after the duration in the `Retry-After` header. Batch requests where possible to reduce request volume.

### Quota Table Limit

**Code:** `QUOTA_TABLE_LIMIT`
**Status:** 402

The app has reached the maximum number of tables permitted by its plan.

**Remediation:** Drop unused tables or upgrade the plan. Plan limits are listed on the [Plans & Usage](/core-concepts/plans-and-usage/) page.

### Quota Deployment Limit

**Code:** `QUOTA_DEPLOYMENT_LIMIT`
**Status:** 402

The app has reached the maximum number of frontend or function deployments permitted by its plan.

**Remediation:** Delete inactive deployments via `delete_app` / `manage_edge_ssr` or upgrade the plan.

## State errors

These indicate that the resource exists but its current state does not allow the requested operation.

### State Invalid Transition

**Code:** `STATE_INVALID_TRANSITION`
**Status:** 409

The resource cannot move from its current state to the requested state (e.g. resuming an app that is not paused).

**Remediation:** Inspect the current state, then call the right transition. The error `details` typically includes the actual and expected state.

### State Prerequisite Missing

**Code:** `STATE_PREREQUISITE_MISSING`
**Status:** 409

A prerequisite resource or configuration is missing for the action (e.g. deploying a function before the app schema is initialized).

**Remediation:** Complete the prerequisite step listed in `remediation`, then retry.

### App Paused

**Code:** `APP_PAUSED`
**Status:** 423

The app is paused; data and runtime endpoints are unavailable until it is resumed.

**Remediation:** Call the unpause/resume action on the app, or reactivate it from the dashboard. Paused apps still incur storage but reject new traffic.

## Schema errors

### Schema Destructive Change

**Code:** `SCHEMA_DESTRUCTIVE_CHANGE`
**Status:** 400

The proposed schema migration would drop a column or table containing data, and was not explicitly confirmed.

**Remediation:** Re-run the migration with the destructive-change confirmation flag, or rewrite the migration as additive (e.g. add a new column instead of replacing one). Back up data before destructive changes.

### Schema Migration Failed

**Code:** `SCHEMA_MIGRATION_FAILED`
**Status:** 500

The schema migration was rejected by PostgreSQL during execution.

**Remediation:** Check the response `details` for the underlying SQL error. Common causes are NOT NULL backfills without a default, foreign keys to non-existent rows, or type changes that fail to cast existing data.

## RLS errors

### RLS Unsafe Expression

**Code:** `RLS_UNSAFE_EXPRESSION`
**Status:** 400

The submitted RLS policy expression contains a construct that is not allowed (e.g. mutating subqueries, disallowed functions, or unsafe casts).

**Remediation:** Rewrite the policy using the allowed expression grammar. See the [Row-Level Security guide](/core-concepts/row-level-security/) for permitted patterns.

## Realtime errors

### Realtime Not Configured

**Code:** `REALTIME_NOT_CONFIGURED`
**Status:** 400

Realtime has not been enabled for the app or for the specific table.

**Remediation:** Enable realtime via `manage_realtime` before subscribing. Realtime must be enabled per-table.

### Realtime Connection Limit

**Code:** `REALTIME_CONNECTION_LIMIT`
**Status:** 429

The app has reached the maximum number of concurrent realtime connections permitted by its plan.

**Remediation:** Close idle connections, share connections across clients, or upgrade the plan.

## Function errors

### Function Timeout

**Code:** `FUNCTION_TIMEOUT`
**Status:** 504

The serverless function exceeded its execution timeout.

**Remediation:** Optimize the function or move long-running work to a background job. Function timeouts are plan-dependent — see `core-concepts/functions` for limits.

## Integration errors

### Integrations Not Configured

**Code:** `INTEGRATIONS_NOT_CONFIGURED`
**Status:** 400

The integrations subsystem is not set up for this app.

**Remediation:** Run `configure_integration` to enable integrations, then connect the desired toolkit.

### Integrations Toolkit Not Enabled

**Code:** `INTEGRATIONS_TOOLKIT_NOT_ENABLED`
**Status:** 400

The named toolkit (e.g. `slack`, `github`) is not enabled for this app.

**Remediation:** Enable the toolkit via `configure_integration` before invoking its tools.

### Integrations Not Connected

**Code:** `INTEGRATIONS_NOT_CONNECTED`
**Status:** 400

The end-user does not have an active connected account for the requested toolkit.

**Remediation:** Run the OAuth flow for the user with `manage_oauth` to create a connected account, then retry the action.

### Integrations Connection Expired

**Code:** `INTEGRATIONS_CONNECTION_EXPIRED`
**Status:** 401

The user's connected-account credentials have expired and could not be refreshed.

**Remediation:** Re-run the OAuth consent flow for the user to mint a fresh connection.

### Integrations Execution Failed

**Code:** `INTEGRATIONS_EXECUTION_FAILED`
**Status:** 502

The downstream integration tool returned an error during execution.

**Remediation:** Inspect `details` for the upstream provider's error body. Common causes are invalid arguments, missing scopes, or rate limits at the provider.

### Integrations Quota Exceeded

**Code:** `INTEGRATIONS_QUOTA_EXCEEDED`
**Status:** 429

The integrations execution quota for this app or user has been exhausted.

**Remediation:** Wait for the quota window to reset, or upgrade the plan.

## External-system errors

These indicate that an upstream provider (S3, Cloudflare, the database, or a generic network call) returned an error.

### S3 Error

**Code:** `S3_ERROR`
**Status:** 502

The S3-compatible storage backend returned an unexpected error.

**Remediation:** Retry the request with backoff. If the error persists, contact support; this is a backend issue, not a client error.

### External S3 Error

**Code:** `EXTERNAL_S3_ERROR`
**Status:** 502

A request to the underlying object-storage provider failed (e.g. transient network error, signature mismatch, or provider-side outage).

**Remediation:** Retry with exponential backoff. If the failure recurs, capture the request ID from `details` and contact support.

### External DB Error

**Code:** `EXTERNAL_DB_ERROR`
**Status:** 502

The PostgreSQL backend returned an error that is not classified as a constraint or validation issue.

**Remediation:** Retry once. Persistent failures usually indicate a backend incident — check the status page or contact support.

### External Network Error

**Code:** `EXTERNAL_NETWORK_ERROR`
**Status:** 502

A network call to an upstream service failed (DNS, connection, or transport-level error).

**Remediation:** Retry with backoff. If the upstream service is one you provided (e.g. a webhook target), verify its availability and TLS configuration.

### External Cloudflare Error

**Code:** `EXTERNAL_CLOUDFLARE_ERROR`
**Status:** 502

A Cloudflare API call (Workers, Pages, R2, Durable Objects, etc.) returned an error.

**Remediation:** Inspect `details` for the Cloudflare error code. Some errors are transient and resolve on retry; others (e.g. account-limit errors) require dashboard or plan action.

## Internal errors

### Internal Error

**Code:** `INTERNAL_ERROR`
**Status:** 500

An unexpected error occurred inside Butterbase that does not match a more specific code.

**Remediation:** Retry the request. If the error reproduces, capture the response body (which includes a request identifier where available) and contact support.